
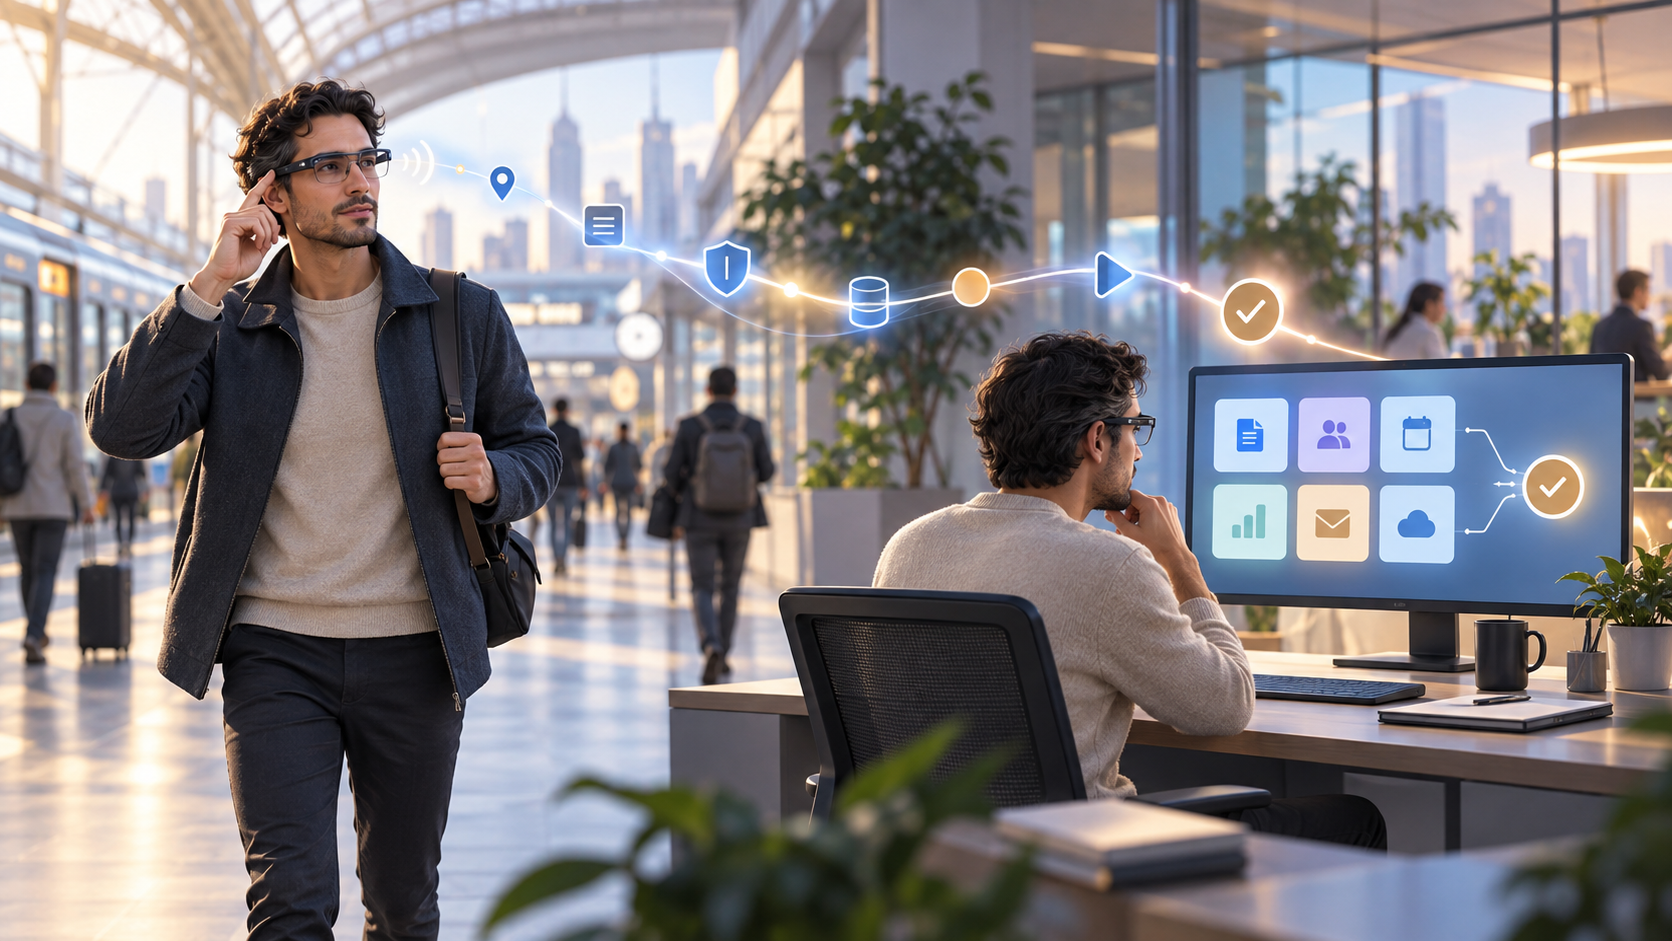
You have two plausible AI roadmaps in front of you. One puts an assistant into glasses or another voice-first device. The other puts an agent inside the systems where employees already work. Both promise less friction, but they remove different kinds of friction and create different kinds of risk.
The product decision is not which surface feels more futuristic. It is whether the assistant can recognize a specific moment, obtain the right context, take an appropriate action, and prove what it did. That complete loop should determine the interface, permissions, architecture, and success metric.
Wearable assistants and enterprise agents have different contracts
A wearable assistant begins in the user’s physical surroundings. An enterprise agent begins inside an organizational workflow. The same model may help power both, but the products should not behave as if their operating conditions are interchangeable.
| Product question | Wearable assistant | Enterprise agent |
|---|---|---|
| What triggers use? | A fleeting situation in the physical world | A task, event, or exception inside a business process |
| What context matters? | What the user can see or hear, plus immediate intent | Records, documents, permissions, policies, and workflow state |
| What does speed mean? | Respond before the moment passes | Move work forward without sacrificing control or accuracy |
| What is a useful action? | Identify, capture, interpret, navigate, or create a reminder | Retrieve, draft, reconcile, update, route, or escalate |
| What makes failure costly? | Misreading the scene, interrupting at the wrong time, or recording too much | Changing the wrong record, exposing restricted data, or triggering an unauthorized process |
| How is trust earned? | Clear sensing state, concise responses, and easy correction | Evidence, scoped authority, approval controls, and an audit trail |
Meta’s planned expansion of Muse illustrates the wearable contract: the company says the assistant will be able to act on objects a person is looking at, such as a product on a shelf or a flyer on a wall. That is not merely chat moved closer to the user’s face. The physical scene becomes an input, and its relevance may disappear within seconds.
Gemini Enterprise illustrates the other contract. Gemini 3.8 Live with Live Avatar can, in Google’s description, continue a spoken interaction while calling tools in the background. The consequential part is not the generated face. It is the transition from conversation to an operation in another system.
Use this distinction to reject vague roadmap language. Improve the proposal until it fits one of these forms:
- In a time-sensitive physical moment, help the user understand or capture something without reaching for another device.
- Inside a governed workflow, use organizational context to complete or advance a defined unit of work.
- Capture context on a wearable, then transfer a resumable task to an enterprise surface where the user can inspect and complete it.
If a proposal is simply to put the assistant everywhere, the team has selected a distribution strategy without selecting a job.
Choose a job with a complete context-action loop
An assistant job is not answer questions or help employees. A usable job describes the triggering moment, the context the system may use, the action it may take, and the evidence the user receives afterward.
Write the first version of the product contract in six lines:
- User: Name the person doing the work, not the department buying the product.
- Trigger: State the observable moment that makes help useful. This might be a spoken request, a viewed object, a new support case, or a workflow exception.
- Required context: List exactly what the assistant needs from the scene, conversation, record, or document.
- Permitted action: Define the smallest action that produces value. Separate reading, drafting, proposing, and executing.
- Proof: Show what the assistant used, inferred, changed, and could not verify.
- Recovery: Specify how the user corrects the interpretation, cancels the action, or resumes the task elsewhere.
Consider a product concept for someone who sees a company flyer while moving between meetings. Capture the company name is only a feature. A complete loop would let the user capture the flyer, confirm the interpreted company and intent, create a follow-up draft, and finish the task later in the customer system. The original image or extracted details should remain attached so the user can check the interpretation before anything becomes an official record.
This example also exposes where teams tend to overreach. The wearable has enough context to preserve the moment, but it may not have enough context to choose the right account, owner, pipeline stage, or follow-up language. The enterprise product has those records, but it did not witness the physical scene. A good design lets each surface do the part for which it has sufficient context.
Before approving a use case, ask five practical questions:
- Can the assistant reliably recognize when this job has started?
- Can it obtain the required context without silently expanding its access?
- Is the proposed action narrow enough to describe in one sentence?
- Can the user inspect the important evidence before a consequential action?
- Can a mistake be corrected without reconstructing the entire interaction?
If the answer to one of these is no, broadening the prompt will not repair the product. Reduce the scope of the job, add a deliberate confirmation, or move the final action to a richer interface.
Make permission, memory, and recovery visible
Voice makes an assistant feel informal. Tool access makes it operational. That combination can hide the moment when a casual request becomes a consequential instruction, especially when the user cannot see a screen full of fields, sources, and side effects.
Design authority as a ladder rather than a single consent screen:
- Sense: Use a microphone, camera, or other device input for the current interaction.
- Interpret: Infer objects, intent, entities, or a requested task from that input.
- Retrieve: Read selected records, documents, or connected applications.
- Propose: Prepare a draft action and expose the target, fields, and expected effect.
- Execute: Write to a system, send a message, place an order, or trigger a workflow.
- Remember: Retain selected information beyond the session for future use.
Each step should have its own policy. Permission to look at a flyer does not imply permission to retain its image. Permission to read a customer record does not imply permission to modify it. Permission to draft a response does not imply permission to send it. A single connected-app toggle is too coarse to communicate these differences.
For most initial releases, start with read access and reversible drafts. Add execution only after the team has evidence that the assistant selects the correct target, constructs the correct action, and handles ambiguity safely. When the action can create financial, legal, security, or customer consequences, present a structured confirmation that names the destination and side effects. A conversational yes is not enough when the user cannot see what the system believes it is approving.
The interface should expose five controls wherever the assistant operates:
- Sensing state: Make it obvious when the product is listening, looking, recording, or idle.
- Scope: Let the user see which application, record set, account, or device input is available to the assistant.
- Provenance: Distinguish observed facts, retrieved data, model inferences, and user-provided instructions.
- Action summary: Show the exact target and proposed changes before approval.
- History and revocation: Make completed actions, retained memories, connected systems, and permission changes inspectable.
Model-level safety does not replace these product controls. Anthropic reports that Claude Opus 5.5 has stronger resistance to prompt injection, but that is a vendor-reported model property, not a guarantee that every tool-using product built on it is secure. Retrieved documents, web content, visual text, and connected applications can still introduce instructions that conflict with the user’s intent. The policy layer must decide which instructions are authoritative and which actions require confirmation.
Memory needs the same separation. Keep session context transient by default. Store reusable preferences only when the user can identify and remove them. Put durable business facts in the appropriate system of record, with its normal access rules and history, rather than in an invisible conversational memory.
Build continuity across surfaces, not one universal interface
An assistant can feel continuous without forcing every surface to behave the same way. Wearables need short exchanges and low interaction cost. Enterprise screens need evidence, workflow state, approvals, and room to resolve ambiguity. Trying to make both interfaces identical usually leaves the wearable too verbose and the enterprise product too opaque.
A practical cross-surface architecture separates six responsibilities:
- Input adapters turn speech, visual input, text, files, and workflow events into structured context.
- A context broker assembles only the information permitted for the current job.
- A policy layer evaluates identity, data scope, action authority, confirmation requirements, and retention.
- A reasoning layer interprets the request and creates a proposed plan or response.
- A tool layer performs approved reads and writes against external systems.
- A durable task record stores status, evidence, approvals, results, and recovery information for work that moves between surfaces.
This separation lets you change a model, device, avatar, or application integration without redefining the authority of the product. It also prevents the conversation transcript from becoming the only record of what happened.
A handoff should preserve a task, not just a transcript
Use a four-step handoff when a wearable interaction needs enterprise context:
- Capture the minimum information needed before the physical moment disappears.
- Repeat back the interpreted object, intent, and next step in a form the user can correct quickly.
- Create a resumable task with its original evidence, current status, and unresolved fields.
- Open the task in the enterprise interface with the proposed action, relevant records, and required approval already assembled.
Do not hand the user a raw transcript and ask them to rediscover the task. A transcript records words. A task record preserves intent, evidence, pending decisions, and the next valid action.
The same principle applies to expressive enterprise interfaces. Google says Gemini 3.8 Live with Live Avatar supports synchronized speech and video across 97 languages, while custom avatars require enterprise allowlisting. Those details can matter for reach and administration, but a face does not remove the need to show tool status, source evidence, and failures. Language coverage is also not proof that every workflow, policy, term, or escalation path has been localized correctly.
When a background action takes time, tell the user what is running and whether they can leave. When a tool fails, preserve the captured context and offer a recoverable next step. The assistant should not restart the conversation merely because one integration timed out or one surface changed.
Evaluate verified outcomes before expanding autonomy
Conversation volume is a weak success metric. A long conversation may indicate engagement, repeated misunderstanding, or an assistant that cannot finish the job. Measure whether useful work reached a verifiable state and how much human correction it required.
Model price should be treated the same way. Anthropic reports that Opus 5.5 costs 40 percent less than Opus 5 on typical workloads in its tests, combining lower token rates with efficiency gains. Its stated standard prices are $4 per million input tokens and $20 per million output tokens, with cheaper cached input. These vendor figures can inform an estimate, but they do not tell you how often a result is accepted, how much correction it needs, or what a failed action costs. The useful economic measure is cost per verified outcome, including model usage, tool calls, review time, retries, and remediation.
Build an evaluation around a recurring real task:
- Select a task with an observable starting state and a checkable final state.
- Freeze the test inputs, available tools, permission scope, and expected output before comparing models or interfaces.
- Define what counts as acceptable, what requires correction, and what constitutes an unsafe or unauthorized action.
- Require the assistant to preserve evidence and label anything it cannot verify.
- Inspect the evidence, action log, and final system state rather than grading only the wording of the response.
- Record correction effort, abandoned handoffs, failed tool calls, unauthorized-action attempts, and total cost for accepted results.
For a wearable, also check whether the interaction completes before the physical context is lost, whether the assistant captures more than the job requires, and whether corrections are possible without a complex spoken exchange. For an enterprise product, check target selection, field-level accuracy, policy compliance, approval quality, and whether the action can be traced and reversed.
Keep the assistant in suggestion, shadow, or draft mode while the evaluation exposes unresolved failure patterns. Promote a task to autonomous execution only when the action is narrow, the authority is explicit, the outcome is observable, and recovery works. Autonomy should be granted per job and per permission scope, not as a general property of the assistant.
Key takeaways
- Start with a triggering moment and a verifiable action, not a device, avatar, or general assistant mandate.
- Let wearables preserve fleeting physical context; let enterprise surfaces resolve records, policy, and approval.
- Separate sensing, interpretation, retrieval, proposal, execution, and memory into distinct permissions.
- Carry evidence, intent, status, and unresolved decisions across surfaces instead of transferring only a transcript.
- Measure accepted outcomes, correction effort, unsafe-action attempts, recovery, and total cost before expanding autonomy.
At your next roadmap review, require one sentence from every assistant proposal: when this trigger occurs, the assistant may use this context to perform this action under this approval rule, and success is verified this way. If the team cannot fill in every part, the product is not ready for more hardware, personality, or autonomy. If it can, build the smallest end-to-end loop and test where context, trust, or recovery breaks.
References






