
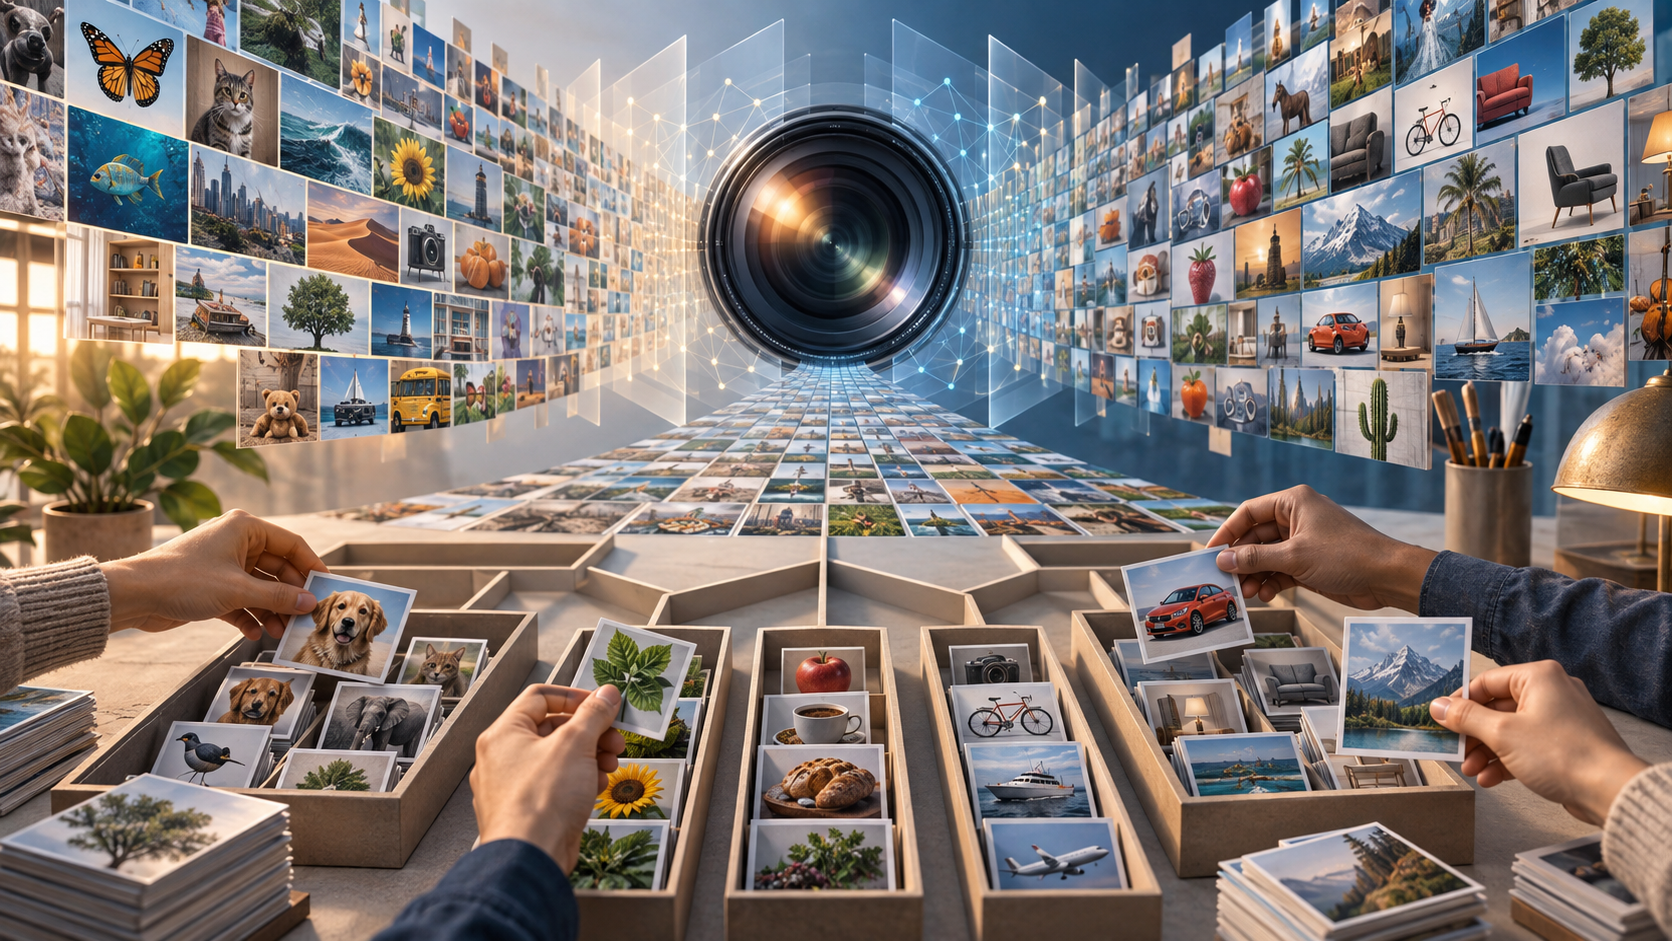
If you are deciding whether a computer-vision initiative needs a better model, more data, or more compute, do not begin with model selection. Begin by asking whether the system has been given a learnable version of the problem.
That is the practical lesson behind Fei-Fei Li’s work. ImageNet did more than supply pictures to an algorithm. It aligned a taxonomy, a large body of labeled examples, a shared evaluation mechanism, learning architectures, and sufficient computation. For an AI product leader, this is a blueprint for finding the real constraint before spending another quarter optimizing the wrong layer.
The first breakthrough was a better definition of the bottleneck
Recognizing an object sounds simple because people perform the task without consciously decomposing it. A dog remains a dog when its breed, size, position, lighting, background, and visibility change. A computer does not begin with that invariance. It must acquire it from examples and feedback.
Computer-vision researchers had already pursued object recognition for decades when Li focused on a basic constraint: a system exposed to only a small collection of pictures could not be expected to represent the visual variety of the world. The limiting factor might not be an insufficiently clever algorithm. It might be insufficient experience.
ImageNet turned that diagnosis into infrastructure. It was designed as a large image database organized around the WordNet hierarchy, with a goal of roughly a thousand images for each concept. It eventually contained millions of images spanning thousands of categories. The hierarchy mattered as much as the scale: the project had to specify what concepts existed before people could collect examples of them.
This is where many AI product plans go wrong. A team writes a broad objective such as “understand product images” or “detect unsafe activity,” then treats model development as the work. Those phrases hide several different products. Classification, object recognition, scene understanding, relationship inference, and action recommendation require different labels, evaluation sets, error policies, and levels of context.
Before comparing architectures or vendors, write a bottleneck brief with five decisions:
- Name the observable decision. Replace “understand quality” with something testable, such as assigning an image to a defined defect category or returning “uncertain.”
- Define the ontology. State which objects, attributes, relationships, and scene types the system must distinguish. If two reviewers cannot apply the categories consistently, the model specification is not ready.
- List the variation that must not change the answer. Include relevant differences in angle, lighting, scale, background, occlusion, device, environment, and object subtype.
- Mark legitimate ambiguity. Decide which cases have no reliable visual answer, which require more context, and which should be escalated to a person.
- Reserve an evaluation set before tuning begins. It should represent the conditions the product will encounter, including the difficult slices that a convenient training sample may miss.
This brief changes the investment conversation. If failures cluster around an underrepresented environment, more examples may matter more than a new architecture. If reviewers disagree about the target label, collecting more labels will reproduce the disagreement at greater scale. If the evaluation set omits the difficult condition, an improving headline metric may tell you nothing about readiness.
The 2012 result came from a system, not a solitary invention
ImageNet also created a common benchmark through the ImageNet Large Scale Visual Recognition Challenge. In 2012, AlexNet delivered a dramatic improvement in image classification. The pivotal result came from the convergence of ImageNet data, deep neural networks, and GPU computation; the neural network used two GPUs.
It is tempting to turn that moment into a model story. For product leaders, the more useful interpretation is that four complementary components became ready at the same time:
| Component | Role in the breakthrough | Product equivalent | Typical failure when it is missing |
|---|---|---|---|
| Structured data | Supplied varied, labeled examples across a defined hierarchy | A governed corpus tied to the product’s operating conditions | The demonstration works, but performance collapses outside a narrow sample |
| Learning architecture | Learned increasingly useful visual representations | A model suited to the required output and available evidence | More data produces little improvement because the method cannot use the signal well |
| Compute | Made large-scale neural-network training practical | Training capacity, inference budget, latency allowance, and an iteration environment | Experiments or production decisions are too slow or expensive to sustain |
| Evaluation | Allowed systems to be tested against a common challenge | A stable holdout set, slice-level metrics, and release criteria | Teams cannot tell whether a change improved the product or merely changed the demo |
The management implication is straightforward: do not approve an AI roadmap that names only the model. Ask who owns each row, what evidence says it is ready, and which row currently limits progress. A model upgrade cannot compensate for an undefined label. A larger dataset cannot repair an evaluation set that rewards the wrong behavior. More compute cannot resolve an ambiguous user decision.
This framing also clarifies build-versus-buy decisions. A general model can be purchased while the product-specific ontology, examples, evaluation suite, and feedback loop remain proprietary. If your differentiation depends on understanding a domain-specific distinction, outsourcing the model does not remove your responsibility to define and test that distinction.
ImageNet was initially difficult to champion because collecting, categorizing, and labeling images looked less intellectually prestigious than inventing an algorithm. Yet that labor created an asset on which many algorithms could be trained and compared. Inside a company, the analogous opportunity often appears as unglamorous shared work: a canonical taxonomy, a reusable evaluation harness, a carefully reviewed corpus, or a consistent failure-reporting system.
I would treat such an asset as a product, not as project residue. Give it an owner, version it, document intended uses, define quality checks, and measure how many teams can make better decisions because it exists. Otherwise every team will rebuild a smaller and incompatible version of the same foundation.
Your dataset is a product decision about the world
Data is not the world itself. It is a selected and organized representation of the world. Choosing categories determines what the system is allowed to notice. Choosing examples determines which forms of variation it can learn. Choosing annotators and instructions determines how ambiguity is resolved. Choosing a benchmark determines which errors become visible to leadership.
That means a dataset contains product policy even when nobody calls it policy. A category can collapse distinctions that matter to users. A sample can make one environment appear universal. A label can present a subjective judgment as objective truth. An aggregate score can conceal failure in a smaller but consequential group of cases.
ImageNet itself had to evolve in response to representation concerns. Its team worked on filtering and balancing images in categories involving people. The important product lesson is not that one cleanup makes a dataset neutral. It is that dataset stewardship continues after launch because categories, coverage, uses, and consequences can change.
Create a dataset decision record before approving collection or annotation. It should answer:
- What user decision is this dataset intended to support, and which uses are explicitly outside scope?
- Who defined the categories, and where are the boundaries between adjacent or ambiguous labels?
- Which people, objects, environments, devices, and operating conditions are represented or absent?
- How are annotator disagreements recorded? Forcing a single answer can erase genuine uncertainty that the product should preserve.
- Which evaluation slices must pass separately rather than disappearing inside one average?
- What happens when the model is uncertain, the input is unfamiliar, or a person disputes the result?
- Who can change the taxonomy, dataset, or acceptance threshold, and how will downstream teams learn that it changed?
This work belongs upstream. Adding a review after the system is built cannot recover distinctions that were never captured or test situations that were never represented. Li’s later role as a founding co-director of Stanford’s Human-Centered AI Institute reflects the broader requirement: technical design needs input from fields such as social science, ethics, medicine, and the humanities when those perspectives shape what a responsible system must perceive and how it should behave.
For a product team, human-centered design is therefore not a values statement attached to a release. It changes the ontology, sampling plan, success metrics, escalation path, interface, and boundaries of automation. Bring affected users and domain experts into those decisions while the dataset can still be changed.
Move from object recognition to the level of understanding the job requires
A useful mental model for vision is a hierarchy: simple visual signals contribute to shapes, shapes contribute to objects, and objects contribute to scenes. Li’s interests across computer vision, machine learning, cognitive and computational neuroscience, robotics, healthcare, and spatial intelligence reflect a persistent question beneath that hierarchy: how does perception become understanding?
The distinction matters because identifying an object is not the same as understanding its place in a situation. Recognizing a chair answers one question. Determining that the chair is beside a table, inside a room, near a person, and changing position over time requires relationships, space, movement, and context.
Li’s work has consequently moved beyond conventional classification toward robotic learning, spatial intelligence, ambient intelligence for healthcare, and generative AI through World Labs. That progression points to a demanding frontier: systems that do not merely name the contents of an image, but represent aspects of the world in which those contents exist.
Do not turn that frontier into an automatic requirement for every product. Specify the lowest rung of visual understanding that completes the user’s job:
- Classification: What category best describes the image or selected object?
- Localization: Where is the relevant object or region?
- Scene context: What else is present, and what surroundings affect interpretation?
- Relationships: How are objects and people positioned or connected?
- Temporal understanding: What changed, moved, appeared, or disappeared?
- Action support: What decision may the product make, recommend, or decline based on that understanding?
A visual search feature may need only the first two rungs. A system interacting with a physical environment may need several more. Buying a strong classifier for a job that depends on relationships and change is not a model-quality problem; it is a mismatch between the representation and the decision.
Write the required rung into the product requirement. Then define what the system must do when lower-level perception is confident but higher-level context is missing. It may ask for another view, disclose uncertainty, defer a decision, or route the case to a person. As AI moves from screens into physical settings, this boundary becomes part of the product’s safety and trust model, not merely an implementation detail.
Key takeaways for AI product leaders
- Diagnose the learning environment before selecting a model. Define the decision, ontology, important variation, ambiguity policy, and evaluation set.
- Manage data, architecture, compute, and evaluation as one system. Progress stalls at the weakest layer, regardless of how impressive another layer appears.
- Treat shared datasets and evaluation infrastructure as products with owners, versions, quality controls, and documented boundaries.
- Assume every dataset encodes choices. Review category design, coverage, annotation disagreement, slice-level performance, and recourse before deployment.
- Match the system’s level of visual understanding to the user’s actual job. Object labels are insufficient when the decision depends on space, relationships, movement, or context.
At your next vision-product review, put one sentence at the top of the page: “The system observes this input so that this person can make this decision under these conditions.” Then identify the missing foundation beneath that sentence. If the discussion jumps directly to model names, bring it back to the data, taxonomy, evaluation, compute, and level of understanding the job actually demands. That is where durable capability begins.
References






