Your AI prototype works. The harder question is whether it will still work after a long-running task, a model change, a failed tool call, a context compaction, or a retry against a system that charges a credit card or edits customer data.
That is the architecture problem in 2026. Coding agents can already scaffold a RAG pipeline, add API routes, write tests, and prepare a deployment from a natural-language request. Your advantage no longer comes from producing the first convincing demo. It comes from building a system whose state, decisions, side effects, and failures you can control.
Reliability belongs to the workflow, not the model
A better model may improve the average result. It does not remove the need for architecture. The model can still receive incomplete context, call a healthy tool with the wrong argument, repeat a side effect after a timeout, retrieve an outdated fact, or hand incomplete work to the next agent.
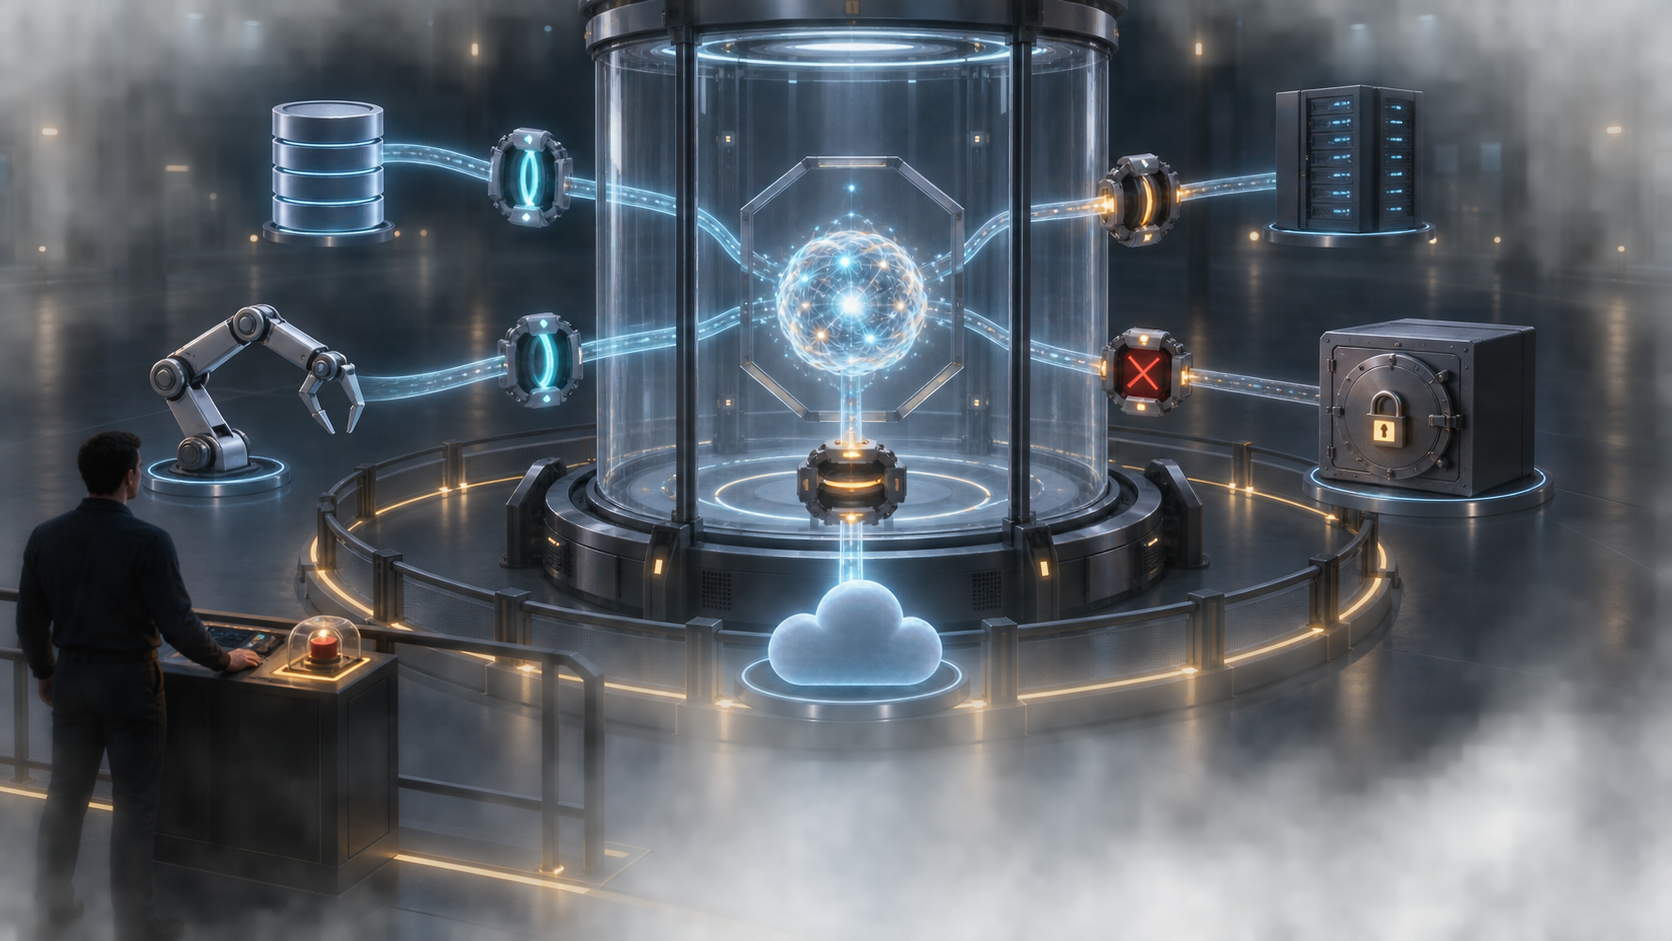
A reliable AI system does three things beyond producing a good answer: it keeps failures inside a limited boundary, exposes enough evidence to diagnose them, and can recover without replaying unsafe work. That definition shifts the architecture review away from a single model-quality score and toward the path an actual request follows.
Map the failure modes before choosing the framework:
- Outcome failure: The response is plausible but does not satisfy the user’s acceptance criteria.
- Context failure: A constraint, tool result, memory, or policy is missing, stale, or attached to the wrong entity.
- Orchestration failure: A required step is skipped, duplicated, executed out of order, or handed to the wrong agent.
- Tool failure: The selected tool is unavailable, receives an invalid input, times out, or returns a partial result.
- Side-effect failure: A retry creates a duplicate ticket, sends a message twice, changes the wrong record, or commits an action before approval.
- Operating failure: The run technically succeeds but violates its latency, cost, capacity, privacy, or retention constraints.
Each boundary needs a contract. Define the input schema, permitted actions, expected output, timeout behavior, retry policy, evidence to retain, and conditions for human review. A prompt is not that contract. Put authentication, entitlements, validation, rate limits, spend controls, approval requirements, and idempotency in deterministic code.
The most useful question in an architecture review is not, “How intelligent is the agent?” It is, “How far can one bad decision travel?” If the answer is unclear, the system has an uncontrolled blast radius.
Build a resumable execution spine around the agent
A chat transcript is not a durable execution system. It is a convenient interface to one. Once an agent can run for hours, invoke several tools, or survive beyond a user’s browser session, the work needs a persistent runtime and an explicit lifecycle. Long-running coding agents are already pushing toward persistent environments that retain state across sessions instead of depending on a laptop and an open terminal.
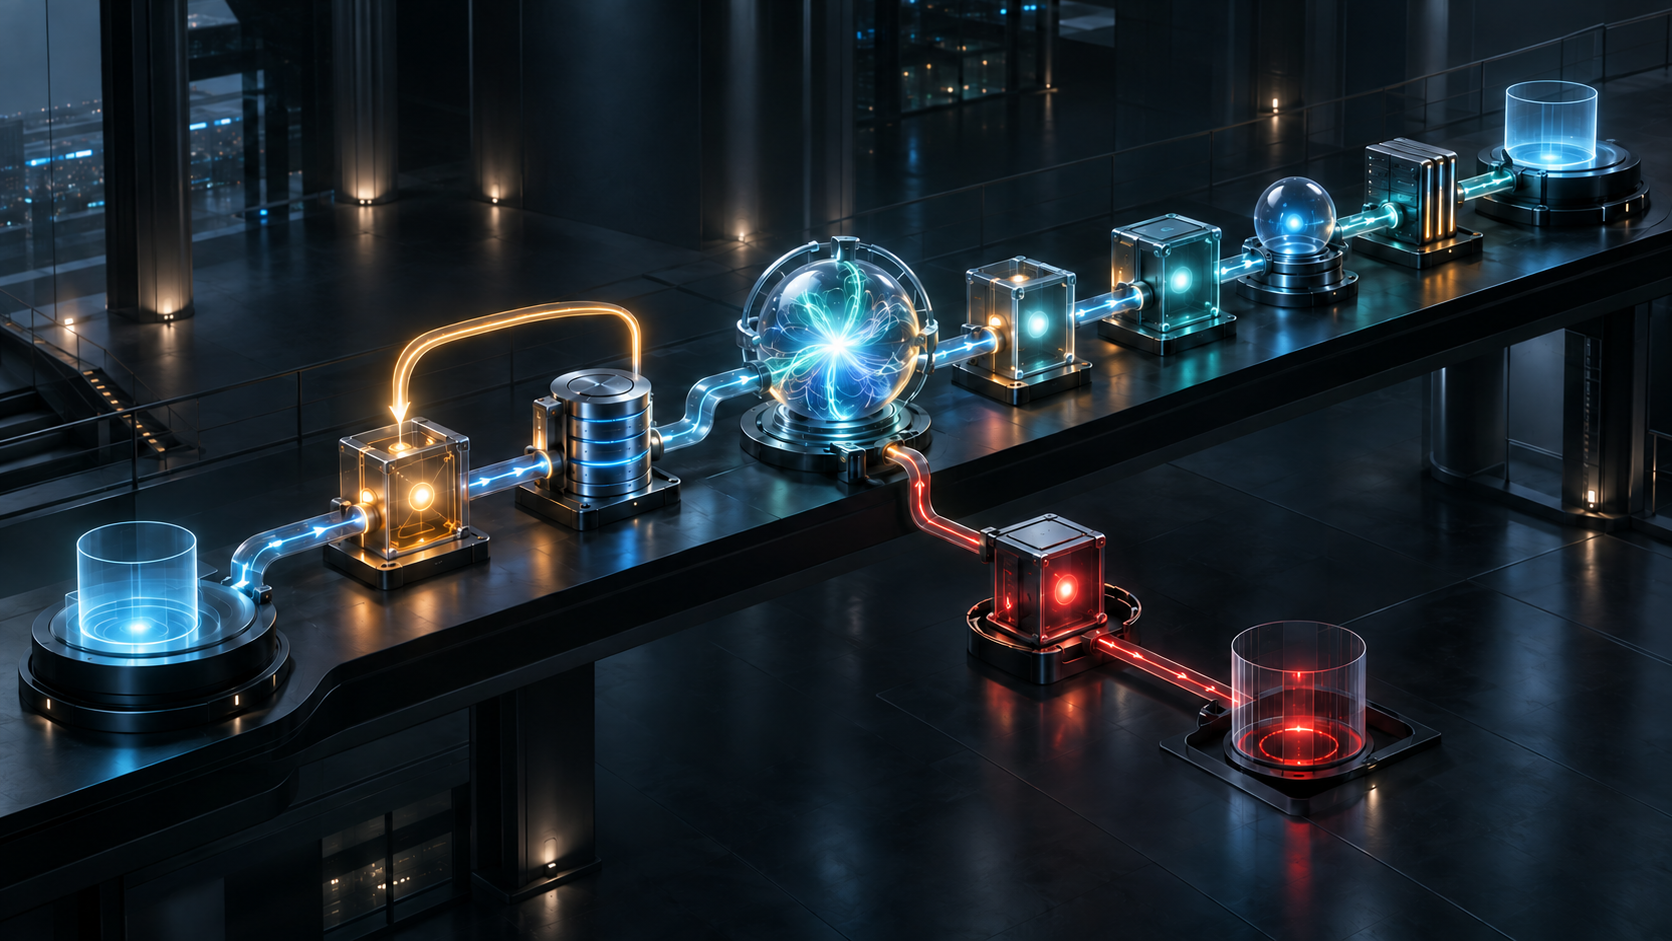
Model the run as a sequence of resumable steps:
- Accept: Validate the request, assign a run identifier, and persist the user, tenant, permissions, policy version, and acceptance criteria that apply to it.
- Plan: Produce a machine-readable plan. Store declared assumptions and the tools each step may use. Do not treat hidden chain-of-thought as your execution record.
- Act: Route tool calls through typed adapters. Validate arguments, enforce permissions, and attach an idempotency key to any operation that could create an external side effect.
- Checkpoint: Persist the completed step, relevant tool evidence, external object identifiers, and the next safe step. Checkpoint immediately after expensive or irreversible work.
- Verify: Test the result against explicit acceptance criteria. A successful API response proves that a tool ran; it does not prove that the user’s objective was met.
- Commit: Separate preparation from execution for consequential actions. Validate the proposed change, obtain any required approval, perform the mutation, and record its external identifier.
- Return: Report the outcome, unresolved work, evidence, and recovery state. A failed run should say where it stopped and whether resumption is safe.
The retry unit should be the smallest step that can be repeated safely, not the entire conversation. If a payment, CRM update, deployment, or outbound message has already succeeded, replaying the full run can turn a temporary timeout into a duplicate real-world action.
Keep the control plane outside the model
The model may propose what to do next. The orchestrator should decide whether that action is allowed and how it will be executed. A useful persisted record includes the run and step identifiers, current status, attempt number, model and prompt versions, policy version, memory references, tool request, tool result, idempotency key, cost, timing, and next permitted transition.
Use a small, explicit state vocabulary such as pending, running, awaiting approval, succeeded, failed, and cancelled. Transitions should be validated by code. This makes recovery predictable and prevents a free-form model response from silently becoming operational state.
Parallel agents need the same discipline. Shared records require version checks, locks, or another concurrency-control mechanism. Otherwise, two competent agents can overwrite each other’s work, act on different versions of a plan, or both conclude that a side effect has not yet happened.
Treat memory as governed product data
Context windows and durable memory solve different problems. A context window gives the model material for the current inference. Durable memory preserves selected state across steps, sessions, and compaction. Mixing the two encourages teams to store everything, retrieve it by similarity, and hope the model resolves conflicts.
That hope fails on long jobs. Earlier constraints and tool outputs can disappear when a coding session is compacted. One practical pattern captures important statements before compaction and retrieves them through a combination of vector search, keyword ranking, and reranking. The architectural lesson is capture before loss, preserve provenance, and retrieve selectively. The choice of database is secondary.
Start by separating memory into the distinct jobs it performs:
| Memory class | What belongs in it | Governance decision | Retrieval rule |
|---|---|---|---|
| Working checkpoints | Current plan, completed steps, tool evidence, unresolved work, and the resume cursor | Own it with the workflow runtime; expire it after completion and the required diagnostic or audit period | Load by run and step identity, not semantic similarity alone |
| Episodic outcomes | What happened in a prior run, whether it succeeded, and the evidence behind that outcome | Set retention by product need, privacy obligations, and audit requirements | Filter by tenant, actor, task, entity, and outcome before ranking relevance |
| Semantic facts | Stable facts about a user, account, product, or operating environment | Assign an authoritative owner; require freshness, correction, and deletion rules | Retrieve only within the permitted identity and tenant scope |
| Procedural lessons | Approved policies, playbooks, and reusable lessons about how work should be performed | Version changes and require review before an observed episode becomes a general rule | Select the version that applies to the current policy and workflow |
This separation matters because an incident is not automatically a policy, and a past user preference is not automatically a current fact. Reported results from TraceRetain and LoCoMo show the underlying risk: unbounded memory degrades under noisy writes while selective retention remains steadier. More stored text can create worse decisions when relevance, authority, and freshness are unresolved.
Every durable memory record should carry enough metadata to answer practical questions later:
- What claim, checkpoint, outcome, or procedure is being stored?
- Which user, tenant, entity, run, and workflow does it belong to?
- What evidence created it, and can that evidence still be inspected?
- Who or what is allowed to read, change, or delete it?
- When must it expire or be revalidated?
- Does it replace an older record, conflict with one, or merely add another observation?
- Was the write automatic, user-confirmed, or approved through a governance process?
Embedding similarity cannot answer those questions. It can help rank eligible records after identity, permission, type, freshness, and policy filters have narrowed the set.
Be particularly cautious with procedural memory. An agent that promotes every successful episode into a reusable instruction will learn from lucky outcomes, workarounds, and compromised inputs. Promotion should be a controlled change: inspect the evidence, define the scope, version the instruction, evaluate the affected workflow, and retain a rollback path.
Evaluate the production path, not a substitute output
An evaluation can score a polished answer and still miss the failure that matters. If the test bypasses retrieval, memory, handoffs, tools, or approval logic, it measures the evaluator’s sample rather than the system you plan to ship.
A research-and-writing workflow makes the distinction concrete. Generating finished text directly for a judge would test writing quality while hiding weak research, lost findings, or incomplete context transfer. A valid end-to-end evaluation instead starts with the same brief as a user, runs the research stage, passes saved findings into the writing stage, and scores the final result. A broken handoff then appears in the output that the judge examines.
Apply that pattern to your own product:
- Start with a real task shape. Use the same fields, permissions, attachments, ambiguity, and acceptance criteria the production workflow receives.
- Run every production stage. Include retrieval, memory selection, planning, tool execution, handoffs, validation, and approval logic. Stub an external dependency only when the stub reproduces its contract and failure behavior.
- Preserve intermediate evidence. Save retrieved records, tool calls, policy decisions, checkpoints, and handoff payloads. Without them, a low final score identifies a symptom but not the defective boundary.
- Score the outcome and the path. Check whether the task was completed, whether required evidence supports it, whether prohibited actions were blocked, and whether the run remained recoverable.
- Classify every failure. Route it to model behavior, retrieval, memory, orchestration, tool integration, policy enforcement, or evaluation quality. “The AI was wrong” is not an actionable defect category.
- Replay before release. Run saved scenarios against changes to models, prompts, retrieval, memory policy, tools, and orchestration. Compare failure classes, not only an average judge score.
Keep deterministic checks separate from model-based judgment. Schemas, permissions, required fields, citations, record identities, arithmetic constraints, and allowed state transitions should be verified by code. Use an LLM judge for qualities that genuinely require interpretation, and retain the rubric and evidence it saw.
Your release gate should reflect consequence. A customer-support draft and an autonomous account change do not need identical controls. The latter needs stronger authorization, side-effect isolation, audit evidence, and rollback behavior even if both use the same underlying model.
Operate for diagnosis, recovery, and sustainable cost
Observability is not a request to store every token forever. It is the ability to reconstruct the decisions and transitions that affected an outcome. Trace the boundaries where responsibility changes: user to orchestrator, orchestrator to model, model to tool, tool to external system, agent to agent, memory to context, and proposal to committed side effect.
For each run, retain the evidence needed to answer:
- Which workflow, model, prompt, tool, and policy versions were active?
- Which memory records and retrieved items entered the context?
- Which tool requests were attempted, retried, rejected, or committed?
- Where did time and cost accumulate?
- Which checkpoint is safe to resume from?
- Did a person approve, override, edit, or reject the result?
- Which evaluation or production rule declared the run successful?
Use different retention tiers. Keep lightweight operational metrics for broad trend detection, searchable structured events for diagnosis, and full payloads only where risk, privacy, and audit needs justify them. Redact secrets and sensitive fields before they enter the telemetry pipeline; access control added after collection cannot undo unnecessary exposure.
Do not confuse more infrastructure with a diagnosis
Capacity symptoms often hide a narrower constraint. A daily 2.1 TB Spark aggregation that failed at 85 percent was not fixed by treating raw heap as the problem. Memory overhead and skew were the relevant failure mechanisms, and adaptive skew-join splitting addressed the cause. The transferable lesson for AI platforms is to instrument queues, payload distributions, context growth, tool latency, retries, and per-workflow resource use before buying more capacity.
The same discipline applies to observability economics. One implementation reached 100,000 monthly LLM traces before managed pricing became painful enough to motivate self-hosting. That is an experience, not a universal crossover point. Self-hosting delivered data control immediately, but the economic case depended on scale and the production stack still needed TLS, SSO, queue monitoring, and managed operational discipline.
Compare the full operating models, not the subscription line item. Managed observability buys deployment, upgrades, backups, availability, and support. Self-hosting adds ownership of components such as Postgres, ClickHouse, Redis, and object storage, along with security, recovery, capacity planning, and on-call work. If your team cannot name the owner of those responsibilities, the apparent saving is being paid elsewhere.
Runtime isolation deserves the same clarity. Long-running agents should operate in bounded environments with least-privilege credentials, explicit network and tool access, resource limits, heartbeats, cancellation, checkpointing, and a way to revoke access while work is in progress. Running several agents in parallel also needs per-tenant quotas and concurrency control; parallelism can multiply rate-limit failures, cost, and conflicting side effects as easily as it multiplies throughput.
Key takeaways
- Design for a bounded blast radius. Deterministic controls should govern permissions, validation, retries, approvals, and side effects.
- Persist execution state outside the conversation so a long-running task can resume from the last safe checkpoint.
- Separate working, episodic, semantic, and procedural memory. Give each class an owner, retention policy, access scope, and write rule.
- Generate evaluation outputs through the same workflow you intend to ship. Otherwise, important failures remain outside the test.
- Trace decision boundaries and recovery state, then choose managed or self-hosted observability using full operating cost and data-control requirements.
At your next architecture review, choose one consequential user journey and draw its real execution path. Mark every durable checkpoint, memory read, memory write, tool boundary, irreversible action, approval, trace event, and evaluation case. If a step cannot be reconstructed or safely resumed, that is the next reliability investment. Do that before adding another agent or changing the model.
References