
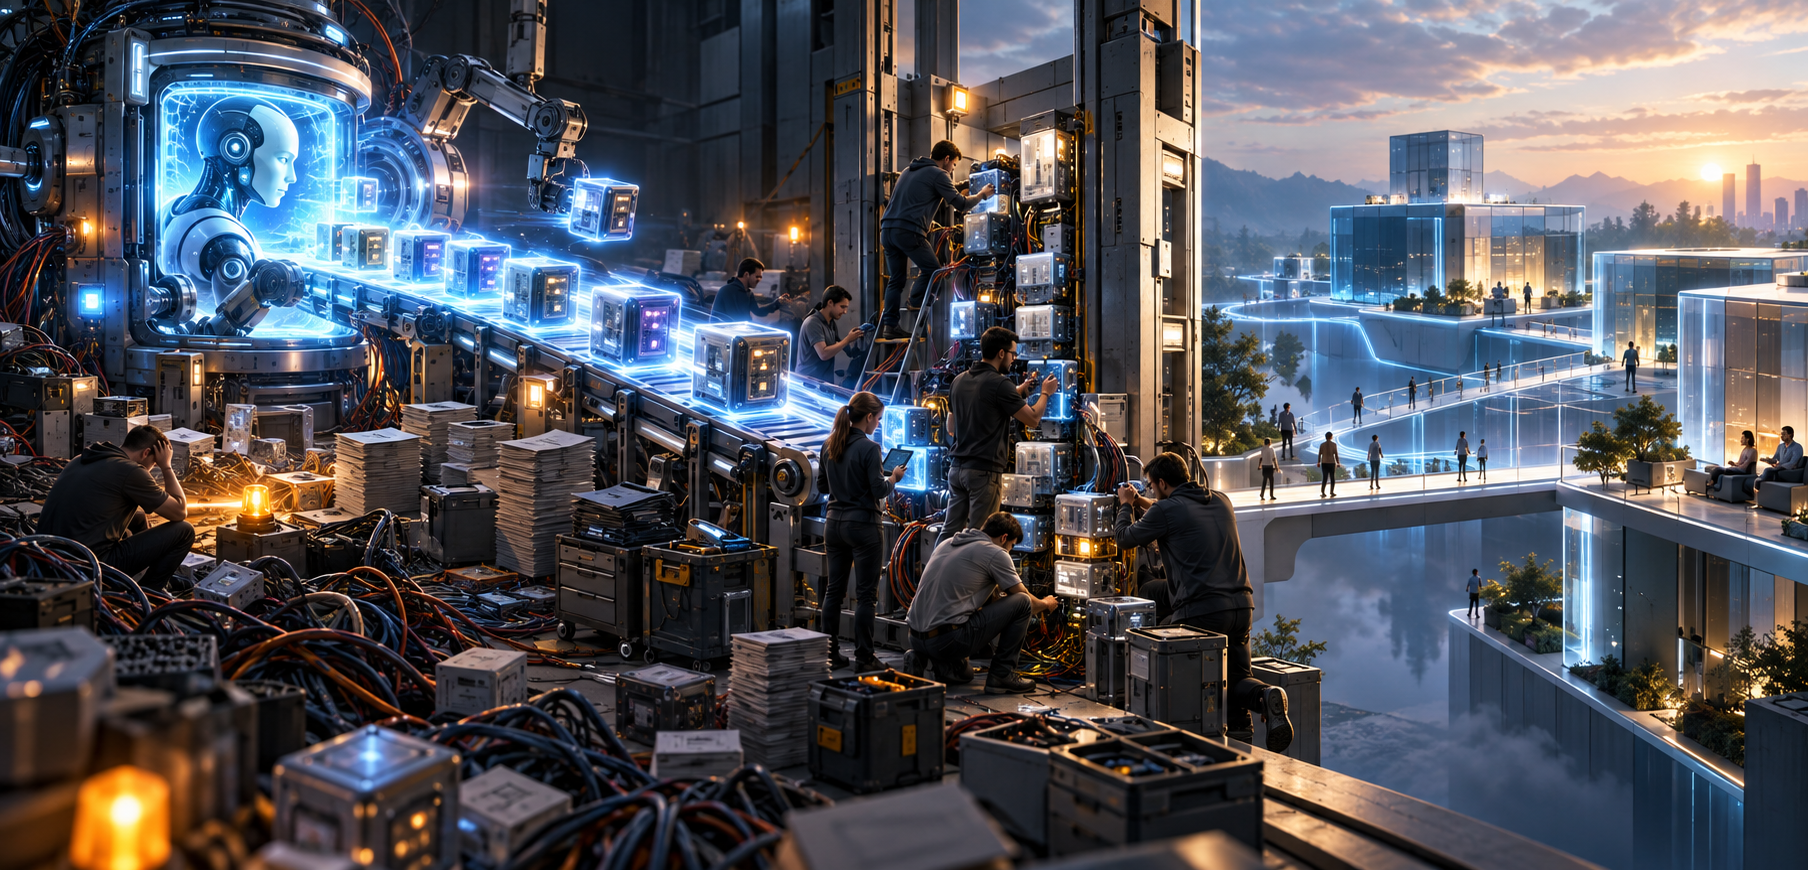
Your team can turn a backlog item into a working interface before the next planning meeting. The demo looks finished, so the roadmap expands, the launch date moves forward, and leadership expects the same acceleration everywhere. Then review queues grow, integrations break, quality work piles up, and engineers spend the next cycle repairing decisions made during the sprint.
If you are deciding how AI should change headcount, commitments, or operating cadence, do not ask only how much faster it can produce code. Ask what it costs to turn that code into a coherent product, earn customer trust, operate it safely, and change it six months later. That is the delivery bill that matters.
Your new bottleneck is system integrity, not code generation
AI has made the first implementation of many features cheaper. That is meaningful. It is not the same as making product delivery free.
The confusion comes from changing the unit of analysis. A generated function, screen, or workflow is one unit of code. A product is a connected system of data, permissions, interfaces, dependencies, operating procedures, and customer expectations. Lowering the cost of one unit can still increase total delivery cost if the organization responds by creating many more units.
The economics are straightforward: total cost depends on both the cost per change and the number of changes introduced. AI can lower the first while encouraging the second to rise. Integration, verification, and maintenance costs then grow with the product surface area, not with the amount of time originally spent typing the code.
This is how an apparently productive feature burst turns into duplicated logic, an incoherent data model, feature bloat, and degraded performance. Each local change may look reasonable. The system-level result does not. A coding agent can optimize the task in front of it without understanding which abstractions must remain stable across the entire product.
You can notice this problem before it becomes a rewrite. Watch for a widening gap between demo completion and production release, repeated implementations of the same rule, schema changes made for individual features, rising review queues, and engineers who need more time to understand generated code than to modify it. Those are not arguments against AI. They are evidence that the constraint has moved from code production to system stewardship.
My rule is simple: never convert faster code generation directly into a larger roadmap. First identify the constraint that follows coding. If architecture review, testing, domain validation, deployment, or operations cannot absorb more changes, adding features merely moves unfinished work downstream.
Cost the product lifecycle, not the generated diff
A credible estimate for AI-assisted delivery needs more than engineering effort attached to a backlog item. It should cover every layer required to turn an idea into maintained customer value.
| Delivery layer | What you are paying for | Question to ask before committing |
|---|---|---|
| Problem learning | Clarifying the customer problem, riskiest assumption, and evidence needed | What decision will this work help you make? |
| Prototype | Producing the smallest experience needed to test that assumption | Is this disposable, or is someone quietly expecting it to ship? |
| Production engineering | Creating maintainable code, coherent architecture, and durable data structures | Which engineer owns the system-level decisions? |
| Integration | Connecting identity, permissions, data, APIs, migrations, and existing workflows | What must remain compatible when this feature changes? |
| Verification | Testing behavior, security, performance, failure handling, and regression risk | What evidence must exist before release? |
| AI behavior quality | Error analysis, evaluation cases, judge design, prompt iteration, and orchestration changes | How will you detect a plausible but unacceptable answer? |
| Launch and adoption | Rollout controls, analytics, documentation, support readiness, and customer communication | Who must be ready besides the team that built it? |
| Operations and maintenance | Monitoring, incident response, rework, cleanup, and future modification | Who owns the feature after the launch milestone disappears? |
Use those layers as an estimation worksheet. For each one, name the owner, expected evidence, unresolved dependency, and exit condition. A blank row is not a zero-cost row. It is unpriced risk.
Do not apply one generic AI productivity multiplier to the full estimate. Faster code generation does not automatically shorten customer interviews, architectural decisions, security review, migration planning, domain evaluation, rollout coordination, or incident handling. Estimate the changed layer differently from the unchanged layers.
Also distinguish capacity from throughput. If AI helps an engineer implement a change sooner, the saved capacity can be used to strengthen verification, reduce technical debt, investigate another customer problem, or start another feature. Only the last option increases work in progress. Treating it as the automatic choice is how a local productivity gain becomes a portfolio-level maintenance liability.
Separate build-to-learn work from build-to-earn work
The most useful cost distinction is not between AI-written and human-written code. It is between building to learn and building to earn.
A build-to-learn artifact exists to answer a question. Can a model extract the information a customer cares about? Does a proposed interaction make sense? Will users trust the recommendation enough to act? AI makes these experiments much cheaper because the artifact only needs enough fidelity to produce valid evidence.
Cheap experimentation is valuable, but only when the team preserves the word experiment. Before work begins, write down four things:
- The uncertainty you are testing.
- The evidence that would change the product decision.
- The limitations participants must not mistake for product behavior.
- Whether the artifact will be discarded, isolated for further experiments, or evaluated separately for production use.
That last decision matters. A prototype can legitimately use mocked data, narrow scenarios, manual intervention, and fragile internal logic. Those shortcuts become defects when the artifact crosses into production without a new standard of review.
A build-to-earn system has a different job. It must create dependable value under real customer conditions. That means real permissions, representative data, understandable failure behavior, support procedures, analytics, performance expectations, maintainable architecture, and an accountable owner. AI can accelerate parts of that work, but it does not erase the obligations.
Do not let the phrase “we already built it” settle the decision. Ask whether the current artifact is a sound foundation for production. Sometimes it will be. Sometimes a clean implementation will be cheaper than preserving experimental shortcuts. A skilled engineer should make that call after reviewing the architecture, data model, dependencies, tests, and likely change paths.
The practical control is a visible label on every AI-assisted initiative: learn or earn. If it is learn, attach a decision and a disposal plan. If it is earn, attach production acceptance gates before anyone generates the first implementation. This prevents a polished interface from silently changing the standard of evidence.
AI products add a second reliability problem
AI-assisted software delivery and AI product delivery are related but different investments.
In the first case, AI helps create conventional software. The production behavior may still be deterministic: given the same valid state and inputs, the system follows defined rules. Existing engineering practices remain central, even if implementation becomes faster.
In the second case, model output becomes part of the customer experience. Now you must evaluate meaning, not just execution. A response can be syntactically valid, confident, and unusable at the same time. Traditional tests can confirm that the request completed, the schema was respected, and the service stayed available. They cannot, by themselves, establish that the answer was relevant, accurate enough for the use case, consistent with policy, or helpful to the customer.
Do not call the demo 70% done
A convincing AI prototype can make progress look more complete than it is. The first 60% to 70% may arrive quickly, while closing the remaining quality gap can take months or years. That is a warning about the shape of the work, not a universal schedule or a budgeting formula.
The early demo proves that the happy path is possible. It usually does not prove that the product handles the diversity, ambiguity, and edge cases present in real usage. The apparent final 30% contains error analysis, evaluation design, domain review, prompt and orchestration iteration, recovery behavior, and the operating loop that keeps quality visible after launch.
This is why percentage-complete reporting is especially misleading for AI initiatives. Report evidence instead. State which customer scenarios have been evaluated, which failure classes remain unacceptable, which user segments or inputs are underrepresented, and which release gates are still open.
Turn subjective quality into release gates
Before an AI feature enters production planning, require the team to define:
- The target task: the job the model-assisted experience must help the user complete.
- A failure taxonomy: the distinct ways an output can be wrong, misleading, irrelevant, unsafe, or operationally unusable.
- An evaluation set: representative cases that exercise normal scenarios, important variations, and known failure boundaries.
- A scoring method: explicit criteria for acceptable output, including where automated checks, an LLM-as-judge, domain experts, or human reviewers are appropriate.
- A release threshold: the documented quality bar and the failures that block launch regardless of the average score.
- A recovery path: what the customer can do when the model is uncertain or wrong.
- An iteration loop: how production feedback becomes new evaluation cases before prompts or orchestration are changed again.
Domain expertise is not optional in that loop. A technically fluent reviewer can see broken execution. A domain expert can see an answer that is coherent but conceptually wrong, misses a critical distinction, or would lead the user toward a poor decision. AI quality work becomes expensive when that expertise is introduced after the product has already been positioned as launch-ready.
Every material prompt, model, retrieval, or orchestration change should run through the relevant evaluation set before release. Otherwise the team is improving visible examples while remaining blind to regressions elsewhere. The cost of maintaining that evaluation discipline belongs in the delivery estimate, not in an unspecified post-launch bucket.
Use an operating model that rewards finished value
The management system around AI matters as much as the tool. If teams are rewarded for prototypes, pull requests, or feature counts, cheaper generation will produce more of those artifacts. It will not necessarily produce more customer value.
You can change the incentives without slowing useful experimentation. Apply the following controls at initiative and portfolio level:
- Baseline the whole flow. Track time to a credible learning result, time from production commitment to release, rework, escaped defects, incidents, and evidence of customer use. Code-generation speed is a contributing metric, not the outcome.
- Label learning and earning work. Do not compare a disposable prototype with a production release as though they represent the same unit of output.
- Make architecture ownership explicit. A named engineer should own cross-feature boundaries, data-model integrity, shared abstractions, and the decision to retain or replace generated code.
- Limit work to verification capacity. When review, evaluation, or integration queues grow, stop adding generated work. The queue is telling you where the new bottleneck lives.
- Reserve capacity for consolidation and deletion. Generated experiments, duplicated implementations, obsolete prompts, and unused features should not remain merely because their creation was cheap.
- Fund post-launch ownership. The roadmap estimate should name who monitors behavior, handles incidents, reviews feedback, maintains evaluations, and makes future changes.
- Review outcomes before expanding scope. Faster completion earns another investment decision; it does not automatically justify more features.
At a roadmap review, ask the team to show what became cheaper and what did not. If the first draft accelerated but evaluation, integration, or rollout did not, keep the original delivery commitment until those layers have evidence behind them. This is a more honest use of AI productivity than pulling every date forward.
The same logic should shape hiring. AI fluency is valuable, but it does not replace engineers who can reason about architecture, product managers who can separate evidence from demo appeal, designers who can expose uncertainty clearly, or domain experts who can recognize plausible errors. The strongest team is not the one that accepts the most generated output. It is the one that knows what to generate, what to verify, what to rebuild, and what to delete.
Key takeaways
- AI can reduce the cost of producing a feature draft without reducing the total cost of delivering and maintaining a product.
- Estimate discovery, productization, integration, verification, launch, operations, and maintenance separately; only some layers may have accelerated.
- Mark every prototype as build to learn or build to earn, then apply a different standard of evidence and engineering discipline to each.
- When model output is part of the experience, budget for error analysis, evaluation sets, domain review, release thresholds, and ongoing iteration.
- Do not turn saved coding time automatically into more roadmap scope. Invest it where the next delivery constraint actually sits.
At your next portfolio review, choose one AI-assisted initiative and re-estimate it across the full delivery lifecycle. If only the implementation layer became cheaper, do not pretend the entire product did. Use the leverage to remove uncertainty, strengthen the system, or shorten the path to a maintained customer outcome. That is how AI improves delivery economics without quietly expanding the bill.
References






