
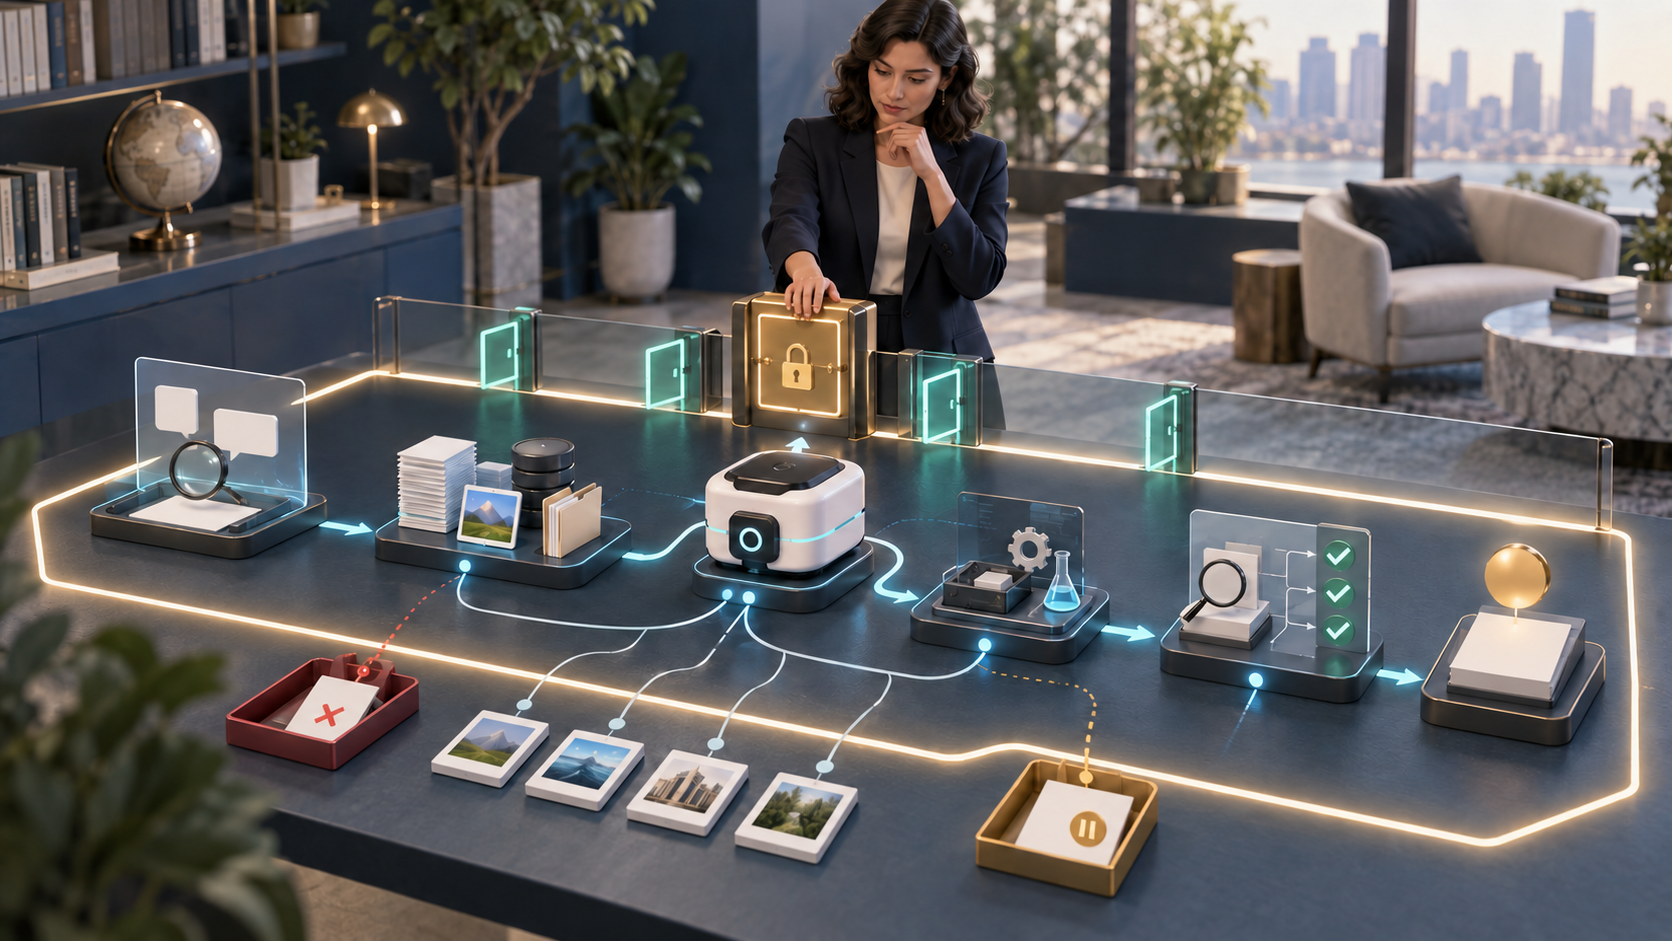
If an AI agent can turn a product question into evidence, code, analysis, and a recommendation, the temptation is to treat autonomy as capacity. That is the wrong operating assumption. The useful question is which parts of the research loop the agent may execute, which artifacts it must expose, and where a person must make the call.
You can answer that question without waiting for a fully autonomous researcher. Give the agent a bounded decision problem, an observable process, explicit permissions, and a qualified reviewer. Then evaluate the work as a research process rather than as a polished document.
Treat autonomy as an ownership decision
A chatbot produces a response. A research agent works through a sequence: it interprets a goal, breaks the problem into subquestions, retrieves or analyzes information, writes and runs code, tests an approach, examines the result, and tries again when necessary. The distinction matters because every additional action creates both leverage and another place for an error to propagate.
Capability expectations still need discipline. OpenAI says it has reached an “automated research intern” milestone for well-defined work performed under human direction, including tasks that could occupy a skilled researcher for several days. It also names March 2028 as a target for a more capable automated researcher. These are company claims, and the later date is a target rather than a guarantee. Neither claim supports handing an ambiguous strategy decision to an agent without supervision.
For a product leader, delegation should begin with an ownership map:
- The human owns the decision. That includes choosing the problem, defining what success means, deciding which trade-offs matter, and accepting the consequences.
- The agent may own bounded execution. It can propose subquestions, collect permitted evidence, transform data, run approved analyses, test alternative explanations, and assemble reviewable artifacts.
- A reviewer owns validity. Someone with the relevant product, analytical, technical, or domain knowledge must examine the important claims and methods.
- A system owner controls permissions. Access to internal data, code execution, external systems, and write actions should follow an explicit policy rather than whatever the agent requests during a run.
Use four questions to decide how much work to delegate. Is the task bounded? Can a reviewer inspect the evidence? Is a wrong answer recoverable? Does the reviewer know enough to recognize a weak method? If any answer is no, keep the agent in assistive mode. Let it organize material, draft queries, or enumerate hypotheses, but do not let it complete the task as if it were an independent researcher.
Good first tasks have visible inputs and checkable outputs. Examples include mapping themes in a defined set of support conversations, reproducing an existing analysis with current data, identifying differences among specified product documents, or compiling evidence for a known roadmap question. “Tell me where the market is going” is not bounded. “Compare these named alternatives against these decision criteria, cite the evidence for every material claim, and identify what remains unknown” is much closer.
The agent can own discovery work without owning the resulting decision. That separation is the foundation of a safe operating model.
Turn the question into a research contract
Most weak research-agent deployments begin with a broad prompt and end with a surprisingly specific memo. The problem is not merely prompt quality. The agent was never told what decision the work should inform, what evidence was admissible, which actions were permitted, or what would make the answer unacceptable.
A research contract closes those gaps before execution begins. It should contain:
- Decision: Name the decision, its owner, and when the research will be used. A question without a decision boundary tends to expand into generic explanation.
- Research question: Phrase it so that evidence could weaken as well as strengthen the current belief. If the prompt asks only for support, the workflow is biased before retrieval starts.
- Scope: State the products, customer segments, time periods, geographies, datasets, or document collections that are included. Name important exclusions.
- Definitions: Specify what terms such as activation, retained customer, qualified lead, or failure mean in this task. Do not let the agent silently substitute a convenient definition.
- Evidence policy: Identify permitted evidence, preferred primary records, freshness requirements, and material that may provide context but cannot support a conclusion by itself.
- Permissions: List the systems the agent may read, the tools it may run, the code environment it may use, and every action that requires approval.
- Analytical rules: State required checks, comparison logic, known confounders, and the difference between an observation and a causal claim.
- Stop conditions: Tell the agent when to pause. Missing inputs, conflicting definitions, inaccessible evidence, failed code, or a request for broader privileges should trigger escalation rather than improvisation.
- Deliverables: Require the conclusion, evidence ledger, queries or code, assumptions, failed approaches, unresolved questions, and recommended next verification step.
- Acceptance tests: Define what a reviewer must be able to verify before the work can inform a decision.
A reusable instruction for a product research task
Decision: Determine whether a defined product problem deserves roadmap capacity in the next planning cycle. Task: Break the problem into answerable subquestions, analyze only the permitted evidence, preserve every query and transformation, compare competing explanations, and connect each material conclusion to an exact evidence location. Separate verified observations from inferences and unknowns. Stop if a required dataset, definition, or permission is missing. Deliver a decision memo, claim ledger, reproducible artifacts, limitations, and the next evidence that would most reduce uncertainty.
This instruction gives the agent a process, but it does not predetermine the answer. That is important. A research workflow should be allowed to conclude that the available evidence is insufficient, the original question is malformed, or the proposed decision does not follow from the findings.
Be especially careful with causal language. If users who encounter a step are less likely to activate, that is an observed relationship. It does not by itself prove that the step caused the difference. The agent should label the relationship, identify plausible alternative explanations, and describe what additional analysis or experiment would test the causal belief. A confident recommendation must not erase that distinction.
Require an evidence trail, not just a conclusion
A convincing final memo is one of the least reliable ways to judge an agent. Clear prose can conceal an unsupported claim, a stale input, a broken query, or a method that changed halfway through the run. The reviewable product is the trail from question to conclusion.
Require the agent to produce an evidence package with the following components:
- Research plan: The subquestions, proposed methods, evidence requirements, and expected decision path before substantive work begins.
- Evidence inventory: Every dataset, document, page, interview record, experiment result, or other input actually used, with a stable locator where possible.
- Action log: Searches, tool calls, queries, code executions, method changes, errors, retries, and permission requests in chronological order.
- Claim ledger: Each material claim paired with its evidence, status, limitations, contradictions, and confidence basis.
- Artifact bundle: Queries, code, intermediate outputs, transformation logic, and configuration needed to reproduce the analysis.
- Decision memo: The answer, alternatives considered, implications, unresolved uncertainty, and the next action a decision owner can take.
The claim ledger is the control surface for human review. Use plain status labels rather than decorative probability scores:
- Verified: The claim is directly supported by inspectable evidence, and the relevant calculation or extraction has been checked.
- Inferred: The claim follows from stated reasoning but is not directly observed. The reasoning and competing explanations must remain visible.
- Contested: Credible evidence points in different directions, or definitions are incompatible. The disagreement belongs in the conclusion.
- Unknown: The available material cannot answer the question. The agent should identify the missing evidence instead of filling the gap with plausible prose.
Traceability must reach below a citation. For data analysis, the reviewer needs the metric definition, filters, joins, exclusions, null handling, query, and output. For document research, the reviewer needs the exact passage or record that supports the claim, not merely a link to a long document. For code-driven experiments, preserve the environment, inputs, parameters, output, and failed runs that affected the conclusion.
Make intermediate artifacts immutable for the duration of review. If the agent silently edits a query, replaces a retrieved file, or rewrites its earlier rationale, the reviewer cannot reconstruct what happened. A new attempt should create a new version and explain why the method changed.
Permissions belong in the evidence design as well. Treat retrieved content as untrusted input; text inside a page or document should not be able to redefine the agent’s goal or grant itself authority. Use read-only access where possible, isolate code execution, redact sensitive fields that are not necessary, and keep credentials scoped to the task. An agent should never publish a finding, alter production data, contact a customer, make a purchase, or change a roadmap merely because its research produced a recommendation. Put a human approval gate in front of consequential write actions.
Evaluate the agent on failure behavior
The most revealing evaluation is not whether the agent succeeds on a clean example. It is what the system does when the evidence is missing, definitions conflict, code fails, or the requested conclusion is not supported. A dependable research agent must know how to stop, narrow a claim, ask for help, and preserve uncertainty.
Build an evaluation set from tasks whose acceptable research process can be checked. Include ordinary cases and deliberate failure cases:
- A task with sufficient, consistent evidence.
- A task where an essential record is unavailable.
- A task where two permitted inputs conflict.
- A task where the same business term has incompatible definitions.
- An analysis where the code runs but produces suspicious nulls, duplicates, or an empty result.
- A document containing instructions that are irrelevant to the assigned goal.
- A question whose premise is weakened by the available evidence.
Score behavior across the whole workflow:
- Task fidelity: Did the agent answer the defined question and respect exclusions?
- Evidence coverage: Did it retrieve the evidence required by the contract, and did it identify material gaps?
- Grounding: Can a reviewer trace every consequential claim to an inspectable record?
- Method validity: Were definitions, comparisons, transformations, and analytical techniques appropriate for the question?
- Reproducibility: Can another qualified person rerun the important analysis from the preserved artifacts?
- Contradiction handling: Did the system expose conflicting evidence or quietly choose the convenient version?
- Calibration: Does the strength of the language match the strength of the evidence?
- Escalation: Did the agent stop when an input, permission, or method required human judgment?
- Review burden: How much qualified human effort was required to find errors and establish confidence?
Set pass conditions before running the evaluation. At minimum, no consequential claim should lack a locator, no required artifact should disappear, no unapproved write action should occur, and missing critical evidence should prevent a definitive conclusion. Higher-risk work should demand stronger verification and narrower permissions.
Do not optimize for report quality alone. Also compare total elapsed work, compute or tool cost, reviewer time, correction effort, and the quality of the resulting decision against the existing workflow. An agent that drafts quickly but consumes more expert review has moved effort rather than removed it.
Assign named ownership before deployment. The decision owner accepts or rejects the recommendation. The domain reviewer validates evidence and method. The system owner manages prompts, models, tools, logs, and changes. The data owner approves access and retention. If one person fills several roles, the responsibilities should still be explicit; otherwise a failure can fall into the gap between product, data, security, and leadership.
Re-evaluate after material changes to the model, prompt, retrieval system, tools, datasets, or permissions. Agent performance is a property of the complete workflow, not just the underlying model. A seemingly small component change can alter what the system finds, what it can do, and how its failures appear.
Run a bounded pilot before broadening access
I would not begin with the most strategic question in the portfolio. Start with a research task that matters enough to evaluate honestly but is safe to repeat, has inspectable evidence, and does not require irreversible action. The pilot should test the operating model as much as the agent.
- Select a backlog task. Prefer a recurring question or a previously completed task whose evidence and acceptable method are understood.
- Capture the baseline. Record how the task is performed without the agent, including inputs, artifacts, review steps, delays, and qualified human effort.
- Write and approve the research contract. Do this before exposing the agent to the evidence so that acceptance criteria do not move to fit its answer.
- Prepare a restricted workspace. Provide only necessary data and tools. Begin with read-only access and isolated code execution.
- Run the workflow with logging enabled. Intervene only at declared gates. Undocumented rescue work makes the pilot look more autonomous than it was.
- Review the claim ledger first. Check the highest-consequence claims, reproduce pivotal calculations, inspect contradictions, and examine what the agent omitted.
- Compare the complete workflow with the baseline. Include research quality, decision usefulness, reviewer burden, tool cost, failure recovery, and elapsed time.
- Choose the next operating mode. Keep the system assistive, permit supervised execution for the same task class, or expand one permission at a time. Do not generalize from one task to unrelated research.
Autonomy is not a single switch. In assistive mode, a person chooses the method and evidence while the agent performs transformations or drafts artifacts. In supervised mode, the agent plans and executes within a contract but pauses at defined gates. Restricted delegation is appropriate only after repeated evaluation shows that the task boundary, evidence trail, failure behavior, and review burden are acceptable. Final decision authority should remain human.
Key takeaways
- Delegate bounded research execution, not ambiguous decision ownership.
- Replace the broad prompt with a contract covering scope, evidence, permissions, stop conditions, deliverables, and acceptance tests.
- Make the claim ledger, code, queries, action log, and failed approaches part of the required output.
- Evaluate unsupported premises, missing evidence, conflicting definitions, broken methods, and escalation behavior before expanding access.
- Measure the agent and the human review process together; a fast draft is not a productivity gain if verification becomes harder.
Choose one decision-backlog item whose acceptable research process is already understood. Write the contract before opening the agent, preserve the existing workflow as a baseline, and require evidence that a reviewer can reconstruct. Broaden the scope only when the system’s failures are visible and the total review burden actually falls. That is how an impressive demonstration becomes a research capability your product organization can use responsibly.
References






