Your agent completes the demo, then falls apart on the real assignment. An API times out. A person delays an approval. The underlying record changes. The context fills up. After resuming, the agent repeats an action or continues from an assumption that is no longer true.
A stronger model may reduce some reasoning errors, but it will not make this workflow reliable by itself. Long-running agents need durable state, constrained authority, verifiable actions, controlled recovery, and an explicit way to stop. The engineering objective is not to keep the model thinking for longer. It is to let useful work continue safely as time and circumstances change.
Define reliability as a product contract, not a model score
A reliable agent does more than reach a plausible answer. It completes permitted work, preserves important constraints, produces inspectable evidence, and stops safely when it cannot justify the next action. If it reaches the right outcome by sending an unauthorized message, using stale data, or repeating a financial transaction, the run failed.
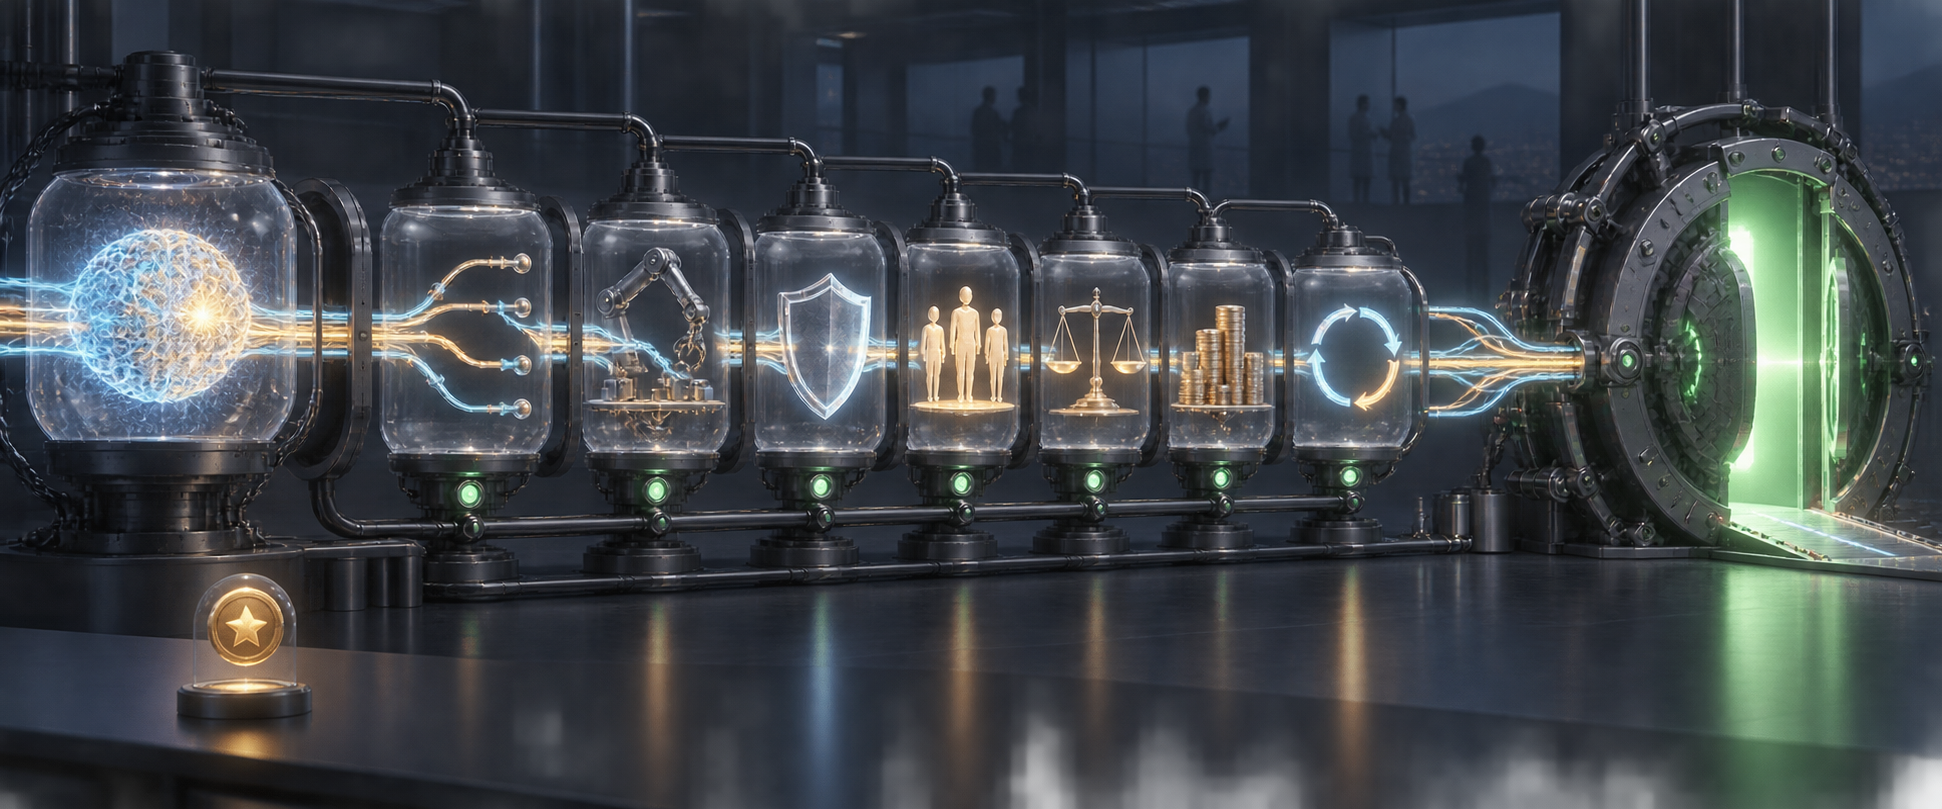
Write an execution contract before choosing the orchestration framework. The contract should answer these questions in language that product, engineering, security, and operations can all inspect:
- Objective: What observable outcome should exist when the run succeeds?
- Decision boundary: Is the agent executing a decision that has already been made, or investigating which decision should be made?
- Authority: Which records, tools, accounts, and external parties may it affect?
- Invariants: What must remain true throughout the run, even if the plan changes?
- Evidence: What must the agent retain so a person or deterministic check can verify completion?
- Budgets: Which limits apply to cost, elapsed time, tool usage, retries, and external actions?
- Stop conditions: Which uncertainty, conflict, denial, or risk must trigger an escalation instead of another attempt?
- Recovery promise: After interruption, must the run resume, restart, compensate for prior actions, or wait for an operator?
The decision boundary deserves particular care. Asking an agent to determine whether a move would improve someone’s situation is different from telling it to arrange the move. The first assignment can correctly end with a recommendation to stay. The second has already embedded a conclusion. Many apparent execution failures are really objective-design failures: the agent faithfully optimizes an instruction that prematurely closed the decision.
Turn the contract into acceptance tests. A support agent might be allowed to draft a refund recommendation but not issue the refund without the required approval. A CRM agent might update an account only when the account identifier, field-level permission, and supporting evidence agree. A research agent should be allowed to return an unresolved result when the available evidence does not support a conclusion.
Version this contract and attach its version to every run. A prompt change, tool permission change, or policy update can alter behavior even when the user-facing objective appears unchanged. Without the contract version, an operator cannot reliably explain why an earlier run was allowed to do something a later run would reject.
Turn every run into a recoverable state machine
A chat transcript is not durable workflow state. It mixes instructions, observations, provisional reasoning, tool output, and conversational text in a form that is difficult to validate or resume. Long-running work needs an orchestrator that owns state transitions independently of the model.
The model may propose the next action. The orchestrator decides whether that action is valid for the current state, records the transition, enforces policy, calls the tool, and persists the result. This distinction prevents a model response from becoming an unreviewed state change.
A minimal checkpoint record
Persist a structured checkpoint at each meaningful workflow boundary. The record should contain enough information to resume without reconstructing reality from the conversation:
- A stable run identifier and the versions of the objective, model, prompt, policy, and tool schemas.
- The current step, workflow state, and reason for entering that state.
- References to validated inputs and evidence, rather than an unbounded copy of the entire conversation.
- The proposed action, policy decision, tool request identifier, and side-effect identifier.
- The confirmed tool result and any postcondition checks.
- The remaining budgets and the history of retry or recovery decisions.
- The next eligible actions, pending approvals, assigned owner, and stop reason when blocked.
Useful workflow states are explicit: planned, ready, executing, waiting, blocked, completed, failed, and compensated are examples. The exact vocabulary matters less than making ambiguous conditions impossible. An agent that is waiting for approval is not executing. A tool call that returned an uncertain response is not completed. A failed action that has been reversed is not equivalent to one whose consequences remain unresolved.
Checkpoint at semantic boundaries such as validated input, approved plan, confirmed external action, and verified outcome. Saving every token adds noise without giving you a safe resumption point. Saving only the final output leaves too much work exposed to interruption.
Make external actions replay-safe
The dangerous failure window sits between performing an external action and recording its result. If the process crashes there, a naive retry may create a duplicate ticket, message, order, refund, or data update.
- Persist the intended action with a stable idempotency key and expected preconditions.
- Run the policy and budget checks against the latest authoritative state.
- Send the request with the idempotency key when the external system supports it.
- Reconcile the external result using the provider’s request identifier or a read-after-write check.
- Persist the confirmed outcome and verify the expected postconditions before advancing the workflow.
If a provider does not support idempotency, give the executor a reliable way to query whether the action already occurred. When neither idempotency nor reconciliation is possible, do not replay an ambiguous write automatically. Route it to a person. This is essential for actions involving money, deletion, legal commitments, customer communication, or another consequence that cannot be safely reversed.
Retry by failure class
A universal retry loop converts understandable failures into incidents. Classify the failure before choosing the recovery action:
- Transient transport failure: Retry with a capped backoff and jitter, while preserving the same side-effect identity.
- Rate or capacity limit: Pause until the service is eligible again; do not spend model calls repeatedly rediscovering the same limit.
- Authentication or permission failure: Stop and request corrected authority. Replanning cannot manufacture permission.
- Invalid structured output: Repair or regenerate only if no external side effect has occurred and the remaining budget permits it.
- Failed precondition: Refresh the relevant state and replan. The world has changed, so repeating the old action is wrong.
- Ambiguous external result: Reconcile first. Never treat uncertainty as permission to execute again.
- Policy denial: Record the denial and escalate or terminate. A different wording of the same prohibited action is not recovery.
Resumption should itself be a controlled decision. Give the model a compact, validated resume packet containing the objective, current state, confirmed actions, unresolved questions, remaining authority, and eligible next actions. Do not ask it to infer all of that from a long transcript.
Keep reasoning flexible while authority stays narrow
An agent needs room to adapt its plan, but it should not be able to expand its own permissions. Separate planning, policy enforcement, execution, verification, and supervision even if some of those responsibilities use the same model. The separation is architectural: each responsibility receives different inputs, produces a typed output, and has different authority.
- Planner: Proposes steps, assumptions, dependencies, and alternative routes. It cannot execute side effects.
- Policy gate: Checks the proposed action against permissions, invariants, budgets, approval requirements, and the latest state.
- Executor: Calls an allowlisted tool through a strict schema. It cannot change the policy or invent a new tool.
- Verifier: Tests preconditions, postconditions, evidence quality, and completion criteria.
- Supervisor: Chooses whether to continue, replan, request help, compensate, or terminate.
These roles do not require a crowd of autonomous agents. Adding more model calls can increase latency, cost, and correlated error. Start with deterministic code for policy checks, state transitions, permissions, schema validation, arithmetic, identifiers, and state diffs. Use a model where interpretation or open-ended planning is actually necessary.
Scope credentials to the run, tenant, tool, and action type. Prefer read-only access until a write is required. Require a fresh approval token for high-consequence actions, and consume that token when the approved action is executed. The model should never receive a broad credential simply because the surrounding application has one.
Treat retrieved pages, emails, documents, tickets, and tool responses as untrusted data. Their text may contain instructions, but those instructions must not alter system policy, grant permissions, change the objective, or expose another tenant’s data. Pass tool results through typed adapters and label their provenance before returning them to the planner.
Keep three kinds of information separate:
- Authoritative workflow state: Validated facts that control what may happen next.
- Evidence store: Tool results, records, citations, approvals, and artifacts used to justify decisions.
- Working context: A compact summary assembled for the current model call and safe to discard afterward.
This separation prevents a stale summary from silently becoming authoritative. It also makes context-window limits manageable: the agent retrieves the state and evidence needed for the next decision instead of carrying every prior interaction forward.
Verification must be proportional to consequence. Use deterministic checks for schemas, identifiers, permissions, totals, and expected record changes. Use a model-based critique for semantic quality, but do not treat a second model response as proof. For decision-oriented work, explicitly require the agent to seek evidence that would make its preferred recommendation wrong. Otherwise, a narrow search can look complete while excluding alternatives that would change the answer.
Evaluate the trajectory, not only the final response
Long-running reliability accumulates across planning decisions, tool calls, waits, resumptions, and external changes. A polished final response can hide an invalid intermediate action. A failed final response can hide a system that correctly stopped before causing harm. Your evaluation has to inspect the path.
This is why the model is only one component of the production system. A reported GPT-6 Astra result more than doubled its predecessor on business-workflow tasks while reaching 41.4% completion. That result may justify testing a broader class of assignments, but it does not establish the completion rate, safety, or economics of your workflow. A benchmark licenses an experiment, not production authority.
Build an evaluation corpus from the workflow classes, permissions, and failure modes in your own execution contract. Score several layers separately:
- Outcome: Did the required real-world state or deliverable exist at the end?
- Policy compliance: Did every proposed and executed action stay within authority and preserve invariants?
- Tool correctness: Were the right tools called with valid arguments against the intended entities?
- Trajectory quality: Did the agent gather sufficient evidence, update its plan when facts changed, and avoid unnecessary loops?
- State integrity: Could every transition be reconstructed from durable records?
- Recovery: Did interruption, denial, or partial failure lead to the specified retry, reconciliation, escalation, or stop behavior?
- Operational fit: Did latency, cost, human intervention, and tool consumption remain inside the product envelope?
Do not evaluate only clean runs. Inject the conditions that extended workflows will eventually encounter:
- Tool timeouts, rate limits, malformed responses, and unavailable dependencies.
- Duplicate callbacks and responses that arrive after the run has moved to another state.
- Expired credentials, revoked permissions, and approval requests that are denied.
- External writes that succeed while their acknowledgements are lost.
- Records that change between planning and execution.
- Missing evidence, conflicting evidence, and retrieved content containing hostile instructions.
- Context compaction, process restarts, model changes, and operator cancellation.
Replay recorded tool outputs when you need deterministic comparisons between model, prompt, policy, or orchestration versions. Then run live integration tests for behaviors that replay cannot reproduce, such as authentication, concurrency, and side-effect reconciliation.
Instrument decisions, not hidden reasoning. A useful trace records the run and version identifiers, state transition, input references, proposed action, policy result, tool request identifier, result class, evidence references, budget change, and operator intervention. Do not log secrets, unrestricted personal data, or private chain-of-thought. Operators need concise decision rationales and evidence, not an uncontrolled transcript of everything sent through the model.
Slice operational metrics by workflow class and consequence. Track successful outcomes, blocked unsafe proposals, duplicate or missing side effects, failed reconciliations, checkpoint recovery, human intervention reasons, evidence coverage, latency, and cost. A blended completion rate can improve while the most consequential workflow is getting less safe.
Expand autonomy only after the recovery path works
Launch by increasing consequence, not by declaring the agent autonomous. Each stage should expose a new class of risk while preserving an immediate fallback:
- Historical replay: Run against recorded cases with no live tools and inspect trajectory-level failures.
- Live shadowing: Let the agent observe current inputs and propose actions without changing external state.
- Recommendation mode: Show its proposed plan, evidence, and uncertainty to an operator who performs the action separately.
- Supervised execution: Let it prepare writes, but require approval at the action boundary.
- Bounded autonomy: Permit a narrow set of reversible, reconcilable actions within explicit budgets and permissions.
- Measured expansion: Add workflow classes or higher-consequence actions only after their evaluation, observability, incident, and rollback requirements are ready.
Promotion criteria should include more than average completion. Require representative trajectory tests, correct handling of policy denials, reliable side-effect reconciliation, successful checkpoint recovery, meaningful escalation messages, and acceptable operating cost. If operators routinely approve an action without enough evidence to judge it, the presence of an approval button has not made the system safe.
Give operators a run console that answers practical questions without reading raw logs: What is the objective? Which state is the run in? What has it changed? Which evidence supports those changes? What is uncertain? Which approval is pending? What budget remains? Can the run be paused, cancelled, resumed, compensated, or safely abandoned?
Cancellation is a core workflow transition, not a process kill. A safe cancellation stops new actions, waits for an active tool call to reach a known boundary, reconciles uncertain side effects, revokes run-scoped authority, and records whether compensation remains necessary. For an incident, the runbook should also let an operator pause new runs, identify affected versions, inspect external consequences, and resume only from confirmed checkpoints.
Key takeaways
- Define success, authority, evidence, budgets, and stop conditions before selecting the agent framework.
- Let the model propose actions, but let deterministic orchestration own workflow state and permission checks.
- Persist semantic checkpoints and make every external write idempotent or independently reconcilable.
- Classify failures before retrying; ambiguous side effects require reconciliation, not repetition.
- Evaluate complete trajectories under injected faults, not just final responses from clean runs.
- Increase autonomy only when recovery, observability, cancellation, and operator controls are already working.
Choose one bounded workflow before adding another tool or model. Write its execution contract, draw its state transitions, identify every irreversible edge, and force each failure class in a test environment. If you cannot show exactly how the run resumes, stops, or reconciles an uncertain action, keep that action behind human approval. That discipline is what turns a capable model into a dependable product.
References
- Nate Jones’s Substack — Twenty hours of admin sit inside an average household move. I ran a simulated one through an agent. Grab the 23-card guide that aims the same method at the jobs on your list.
- Towards AI — What’s left to engineer when the model is good?