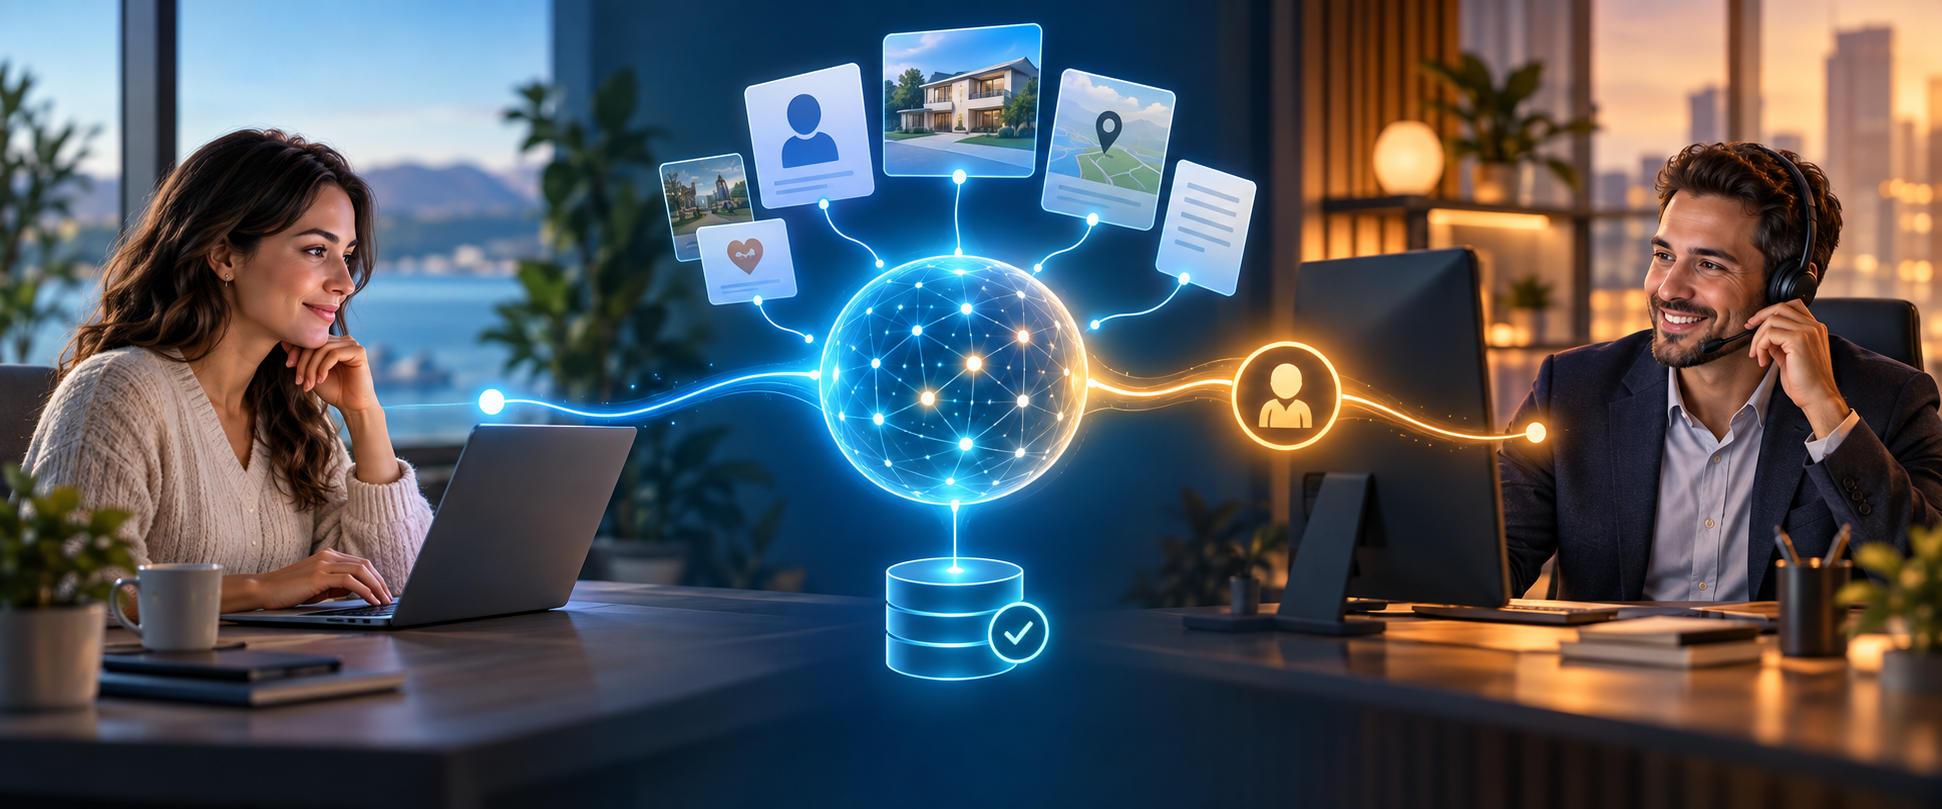
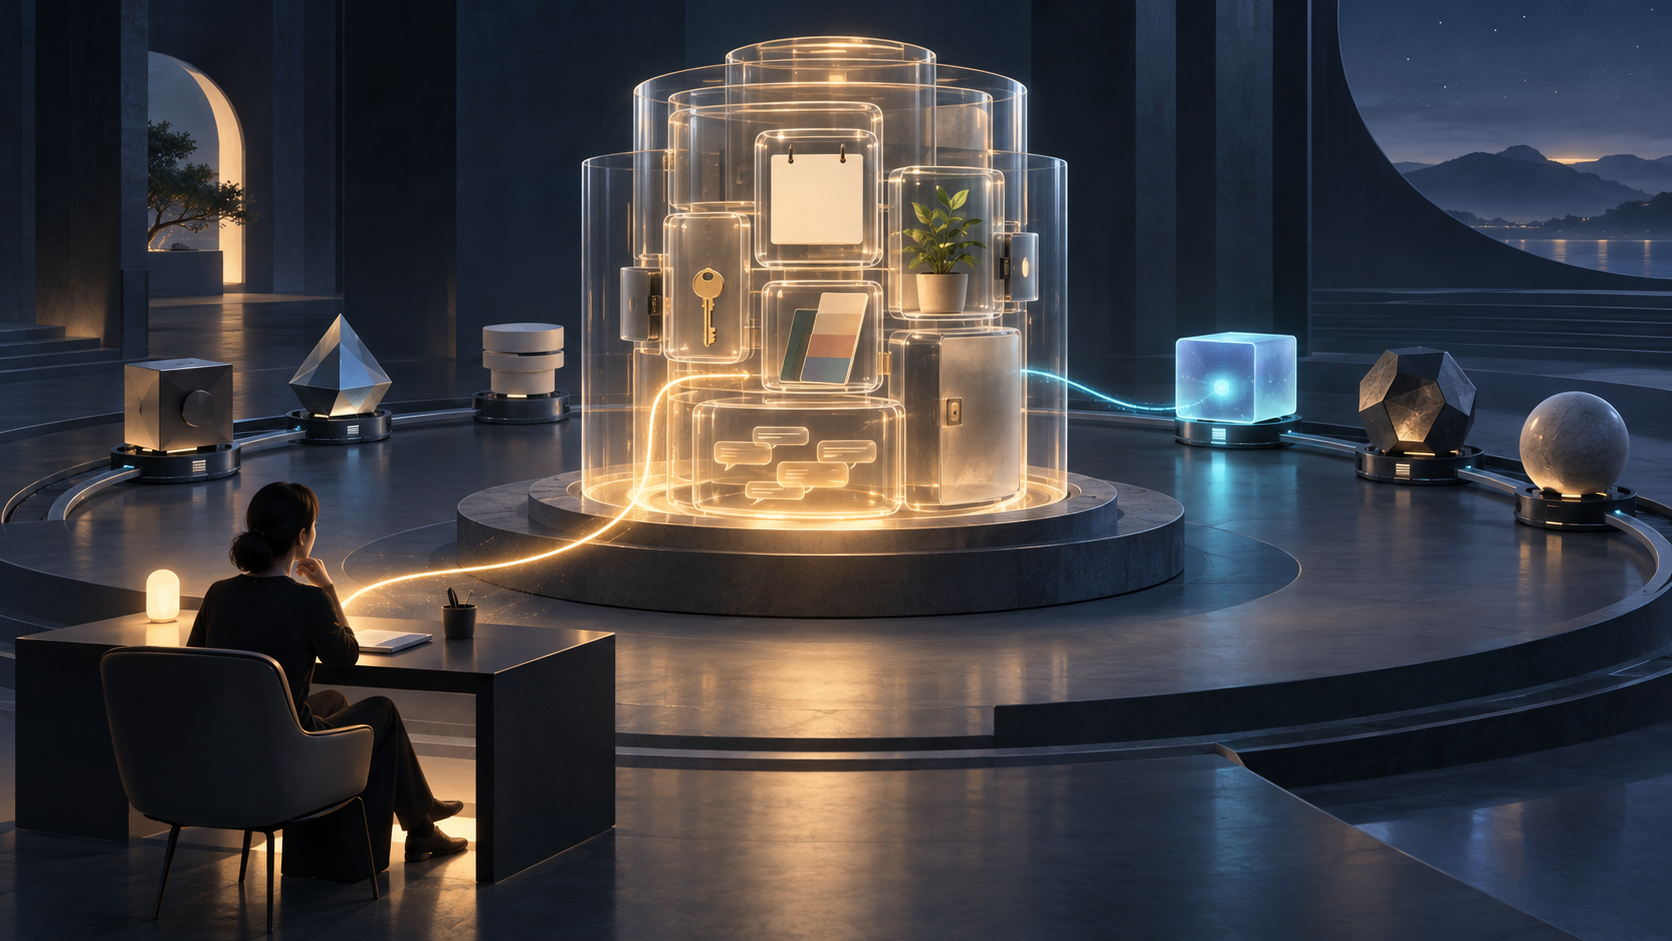
If your roadmap debate has collapsed into a choice between a better model and better memory, you are asking the wrong question. Your users do not experience a model in isolation. They experience whether the assistant remembers the right context, respects boundaries, and becomes more useful without making them repeat themselves.
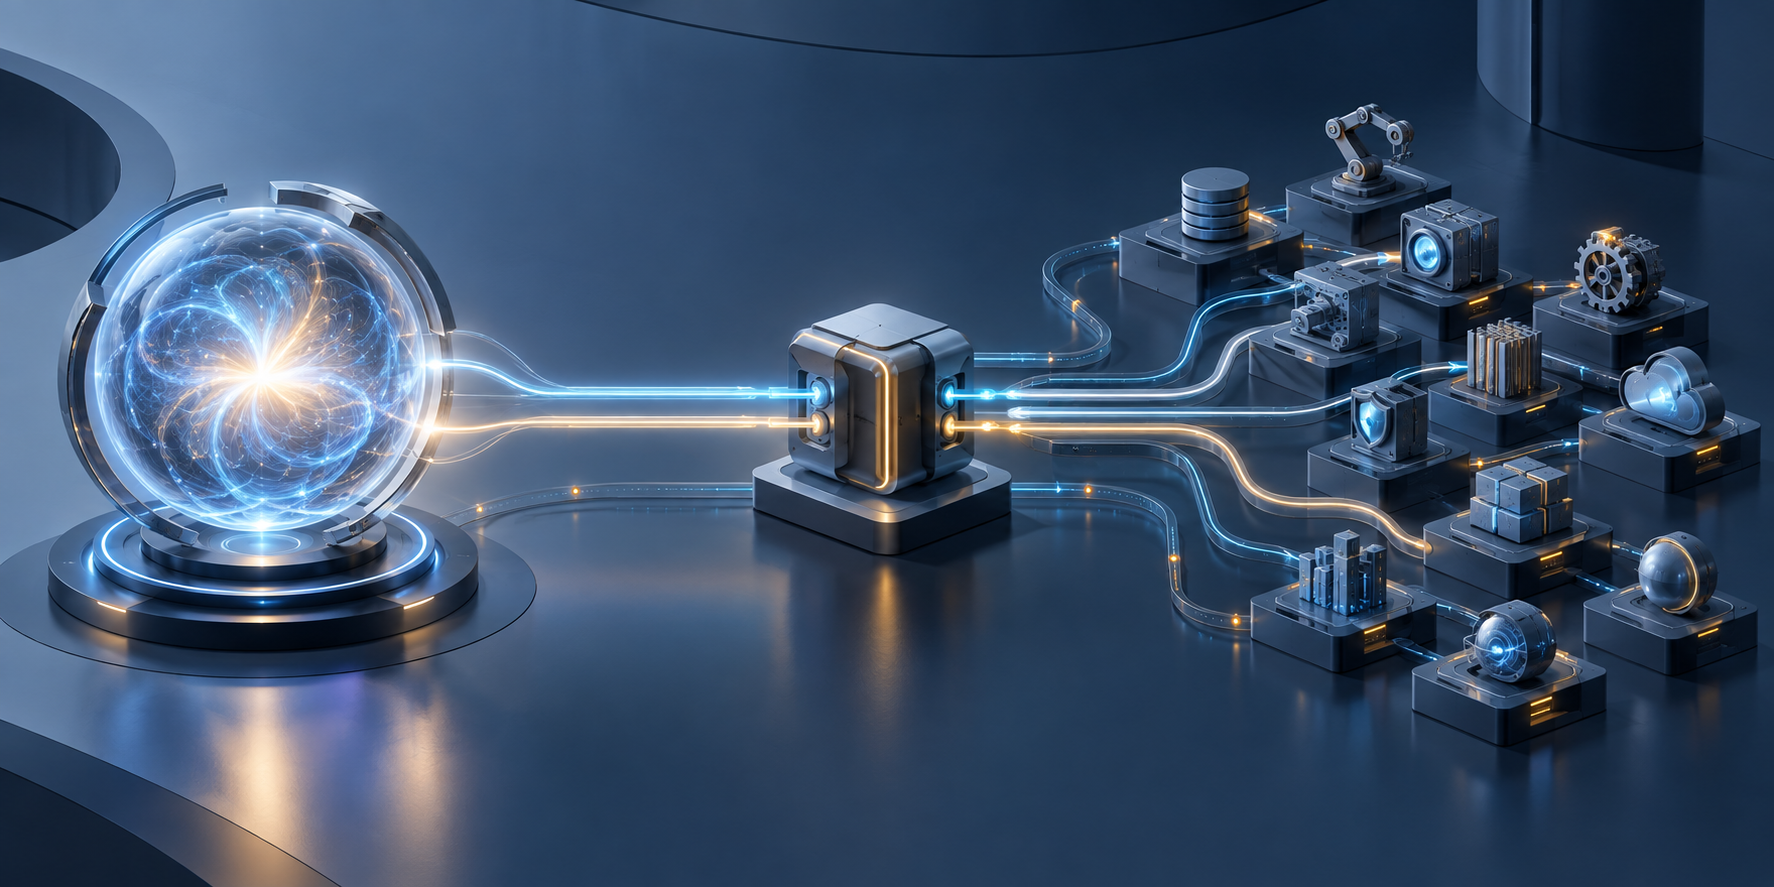
The practical strategy is to treat models as replaceable capability providers and memory as a governed product subsystem. That lets you benefit from open-model competition without handing the user relationship to whichever model vendor happens to lead this quarter.
Continuity is becoming a product, not a model feature
A model supplies reasoning and generation for the current interaction. Memory supplies continuity across interactions. The distinction matters because a model can produce an excellent answer while the assistant around it remains frustratingly forgetful.
The size of the strategic bet is becoming visible. Tab emerged from stealth at a $300 million valuation with a memory-first proposition, although it did not disclose the exact financing details. That valuation is not evidence that users will adopt or trust persistent memory. It is evidence that continuity is now important enough to be treated as a potential product category rather than a minor chat feature.
The real test is repeated use. Does the assistant eliminate work on the tenth interaction that it could not eliminate on the first? Can it retain a decision without retaining an entire sensitive conversation? Does it know when an old preference has expired? Can a user correct it once and trust that the correction will propagate?
At the same time, open-weight competition is giving product teams more options below the application layer. That does not make models interchangeable. It does mean that a temporary lead in model quality is a fragile foundation for a durable product position.
An assistant has at least four separable sources of value: model capability, continuity, execution, and governance. Model capability determines what it can understand or generate. Continuity determines what it can carry forward. Execution determines whether it can complete work rather than merely discuss it. Governance determines what it is allowed to remember and do. If all four are bundled into one vendor’s chat history, changing the model can mean rebuilding the product relationship from scratch.
Your moat is therefore unlikely to be memory in the abstract. Storing transcripts is easy. The defensible layer is the memory contract: which context your product earns the right to retain, how accurately it retrieves that context, and how visibly the user can control it.
Define the memory contract before selecting the stack
Memory design starts as a product and policy decision, not a database decision. Before evaluating vector stores, context windows, or model providers, decide what the word remember means in your product.
| Memory class | Typical content | Sensible default | Main failure to prevent |
|---|---|---|---|
| Working context | The current conversation, task state, and temporary files | Use for the active task and expire when the task ends | Temporary or sensitive material becoming permanent |
| Durable profile | User-stated preferences, role, locale, and recurring constraints | Save explicit choices; confirm consequential inferences | A wrong or stale assumption shaping every later response |
| Episodic memory | Past decisions, completed work, and unresolved threads | Store a concise record with a date and provenance | The assistant inventing or misrepresenting what happened |
| Connected knowledge | Documents, CRM records, tickets, and other authorized systems | Retrieve under current permissions rather than copying everything into a permanent profile | Permission changes failing to propagate to retrieval |
| Commitments and actions | Reminders, approvals, delegated work, and planned external actions | Track state explicitly and require confirmation where consequences are material | Treating remembered intent as permission to act |
The most dangerous category is inferred durable memory. An explicit instruction such as remember that I prefer concise status reports has a clear origin. An inference such as this person always wants short answers may be useful, but it can also be wrong, situational, or outdated. Repeated behavior is evidence for a candidate memory; it is not automatic permission to create one.
Every durable memory object should answer several questions without reconstructing a transcript: who or what it concerns, what claim is being stored, where the claim came from, when it was created, when it should expire, which scope it belongs to, whether the user explicitly approved it, and what newer record supersedes it. Confidence is useful for ranking, but it should never substitute for provenance.
Give the user an inspect, correct, forget, and pause path. A delete button that removes a visible profile field but leaves derived summaries or retrieval indexes intact is not meaningful control. The deletion path has to cover the canonical record, derived representations, and future retrieval.
Keep memory permission separate from action authority. Knowing that a user previously approved a campaign does not authorize the assistant to approve the next one. The same principle is appearing in capability access: Anthropic expanded access to advanced cyber capabilities through a verification program for qualifying security professionals. The useful product pattern is a credentialed lane with explicit eligibility, not a universal switch that silently grants everyone the same capability.
Build memory as a model-independent service
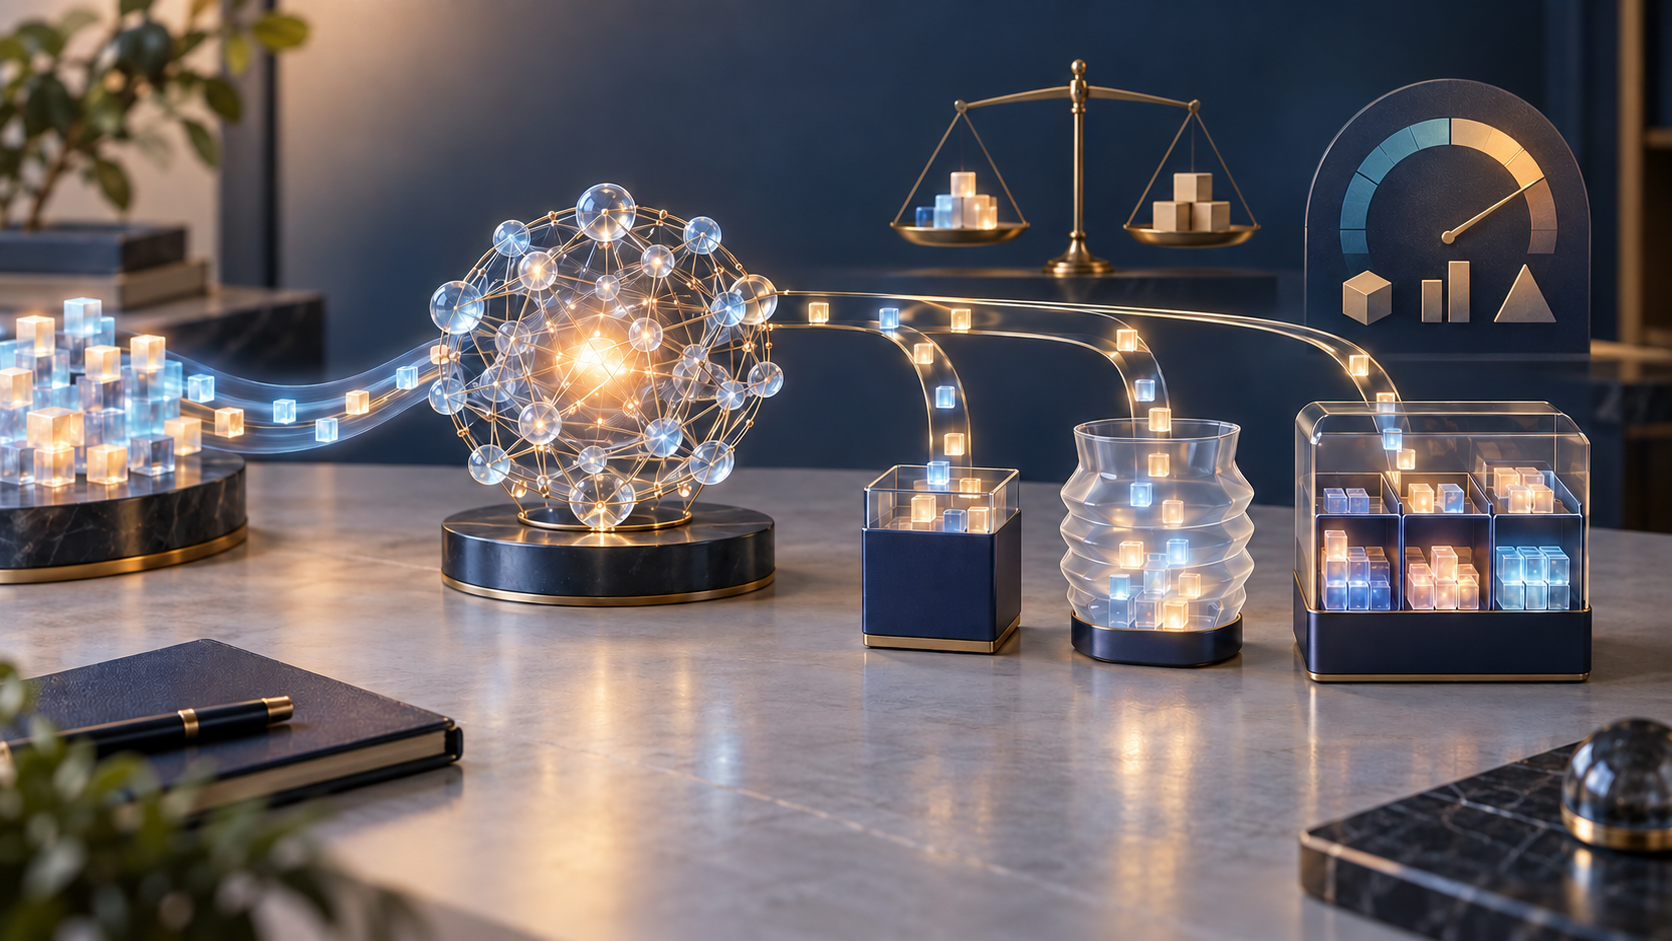
A longer context window is not the same thing as memory. A context window transports information into one model call. Retrieval chooses information relevant to a task. Memory governs what persists, why it persists, and how it may be reused. Treating these as the same layer produces large prompts, unclear consent, and behavior that changes unpredictably when the underlying model changes.
A robust memory pipeline has a deliberate sequence:
- Detect a candidate memory from an explicit user request, an interaction, or an authorized system.
- Classify it by type, sensitivity, scope, and expected lifetime.
- Apply write policy, including confirmation when an inference is consequential or private.
- Store a canonical record with provenance, timestamps, permissions, and supersession rules.
- Retrieve under the user’s current authorization and the current task’s purpose.
- Assemble only the relevant items into model context.
- Record which memory influenced the response, along with corrections and user feedback.
This design gives you two audit trails. The write trail explains why an item became durable. The read trail explains why it appeared in a particular response. You need both. A system can have perfectly accurate stored information and still fail because retrieval surfaced the wrong item, combined two identities, or exposed data outside its intended scope.
Keep the canonical memory in a portable structured form, even if you also create embeddings or model-generated summaries. Embeddings are retrieval aids, not the record of truth. If the only representation lives inside a vendor-specific index, switching embedding models or retrieval infrastructure becomes a data migration problem with no reliable ground truth.
Put provider-specific behavior behind adapters. The application should request capabilities such as extraction, retrieval ranking, summarization, reasoning, or tool selection. It should not depend on a particular provider’s chat-history format to recover durable state. Version the prompts and models used to extract memories so you can trace a bad record back to the write process that created it.
Model portability also needs an evaluation, not just an API abstraction. Run the same memory cases through a replacement model and check whether it selects the same relevant facts, obeys scope boundaries, handles contradictions, and declines to use restricted items. A successful response in a generic model benchmark cannot tell you whether the assistant preserved its relationship with the user.
Use open-weight models for leverage, not ideology
Open-weight does not necessarily mean fully open source. Access to weights does not automatically provide training data, unrestricted licensing, or a low-cost production system. It does, however, create more deployment and customization choices than a product that can call only one closed endpoint.
The competitive field is expanding. Reflection introduced Beam, while Mistral previewed a flagship nicknamed Le Chonk and described it as a one-trillion-parameter model. The parameter count is notable, but it does not answer the questions that matter for your product: task quality, tool reliability, latency, operating cost, deployment complexity, or behavior under your memory policies.
Evaluate each model against the assistant you are actually building. Start with representative tasks drawn from your intended workflows. Include cases with correct memories, stale memories, conflicting memories, missing context, revoked permissions, and malicious instructions inside retrieved content. Score the resulting behavior at the system level rather than grading eloquence alone.
Your model decision should cover six dimensions:
- Quality on your own task and memory evaluations, including refusal and contradiction handling.
- Reliability when producing structured output and calling tools.
- End-to-end latency and cost, including retrieval, reranking, retries, hosting, and observability.
- Deployment and data-control requirements for each customer or workload.
- License terms and the freedom to modify, redistribute, or offer the model through your product.
- Operational maturity, including serving infrastructure, security work, upgrades, and incident response.
This usually leads to a portfolio rather than a single permanent winner. A hosted model may be appropriate for a complex, low-volume task where capability is changing quickly. A managed or self-operated open-weight model may fit a stable, repeated workload where deployment control or unit economics justifies the operational burden. Neither choice should require redesigning the memory system.
Put a capability gateway between the product and model providers. Route by task, risk, customer requirement, and observed performance. Maintain a fallback for critical paths. Use shadow evaluation before moving live traffic, then compare memory-policy behavior as well as answer quality. This converts model competition into negotiating and architectural leverage instead of recurring migration work.
The boundary worth defending is straightforward: own the memory contract, canonical records, permission model, and evaluation set. Rent or operate inference according to the economics and controls of each workload. Open-weight competition creates option value only when your application is capable of exercising the option.
Prove that memory improves the relationship before scaling it
Start with the most reversible form of memory. Let users pin a preference or decision. Make the saved item visible. Add correction and deletion. Then introduce retrieval into a narrow recurring workflow. Only after those controls work should you infer durable memories automatically or let remembered context influence external actions.
This sequence separates two questions that teams often blur: can the system remember, and should it remember? Technical storage proves the first. User benefit, accuracy, and control determine the second.
Use a scorecard that can identify where the system failed:
- Memory precision: of the remembered items surfaced during a task, how many were correct and applicable?
- Retrieval coverage: when a task genuinely required prior context, how often did the system retrieve the relevant item?
- Correction burden: how often did users have to fix, restate, or delete remembered information?
- Cross-session completion: did memory help users finish recurring work without reconstructing prior decisions?
- Policy violations: did the system retain, reveal, or apply information outside its permitted purpose or scope?
- Portability delta: when the model changed, how much did memory selection, policy compliance, and task success change?
Measure severe errors separately from averages. One cross-account disclosure or unauthorized action can matter more than many convenient recollections. Retention is a useful lagging signal, but it cannot tell you whether people return because memory is valuable, because switching is painful, or because the product has made their data difficult to move.
An A/B test can establish whether memory improves completion or reduces repeated input. It should not be used to weaken consent, deletion, or access controls in pursuit of engagement. Those are product requirements and risk boundaries, not experimental variables.
Key takeaways
- Treat persistent memory as a governed product layer, not as a larger prompt or permanent transcript.
- Separate explicit memories, inferred memories, connected knowledge, and action authority because each requires different controls.
- Keep canonical memory records and permissions independent of any model, embedding provider, or chat-history format.
- Choose open-weight and hosted models with task-specific system evaluations, not parameter counts or ideology.
- Track memory accuracy, correction burden, policy failures, cross-session outcomes, and model portability before optimizing retention.
For your next roadmap review, choose one recurring user workflow and write down five things: what the assistant should remember, why it has permission, when the memory expires, how the user can remove it, and how you will verify that the workflow still works after a model swap. If those answers are unclear, the next investment should be in the memory contract and evaluation harness, not another model integration.
References