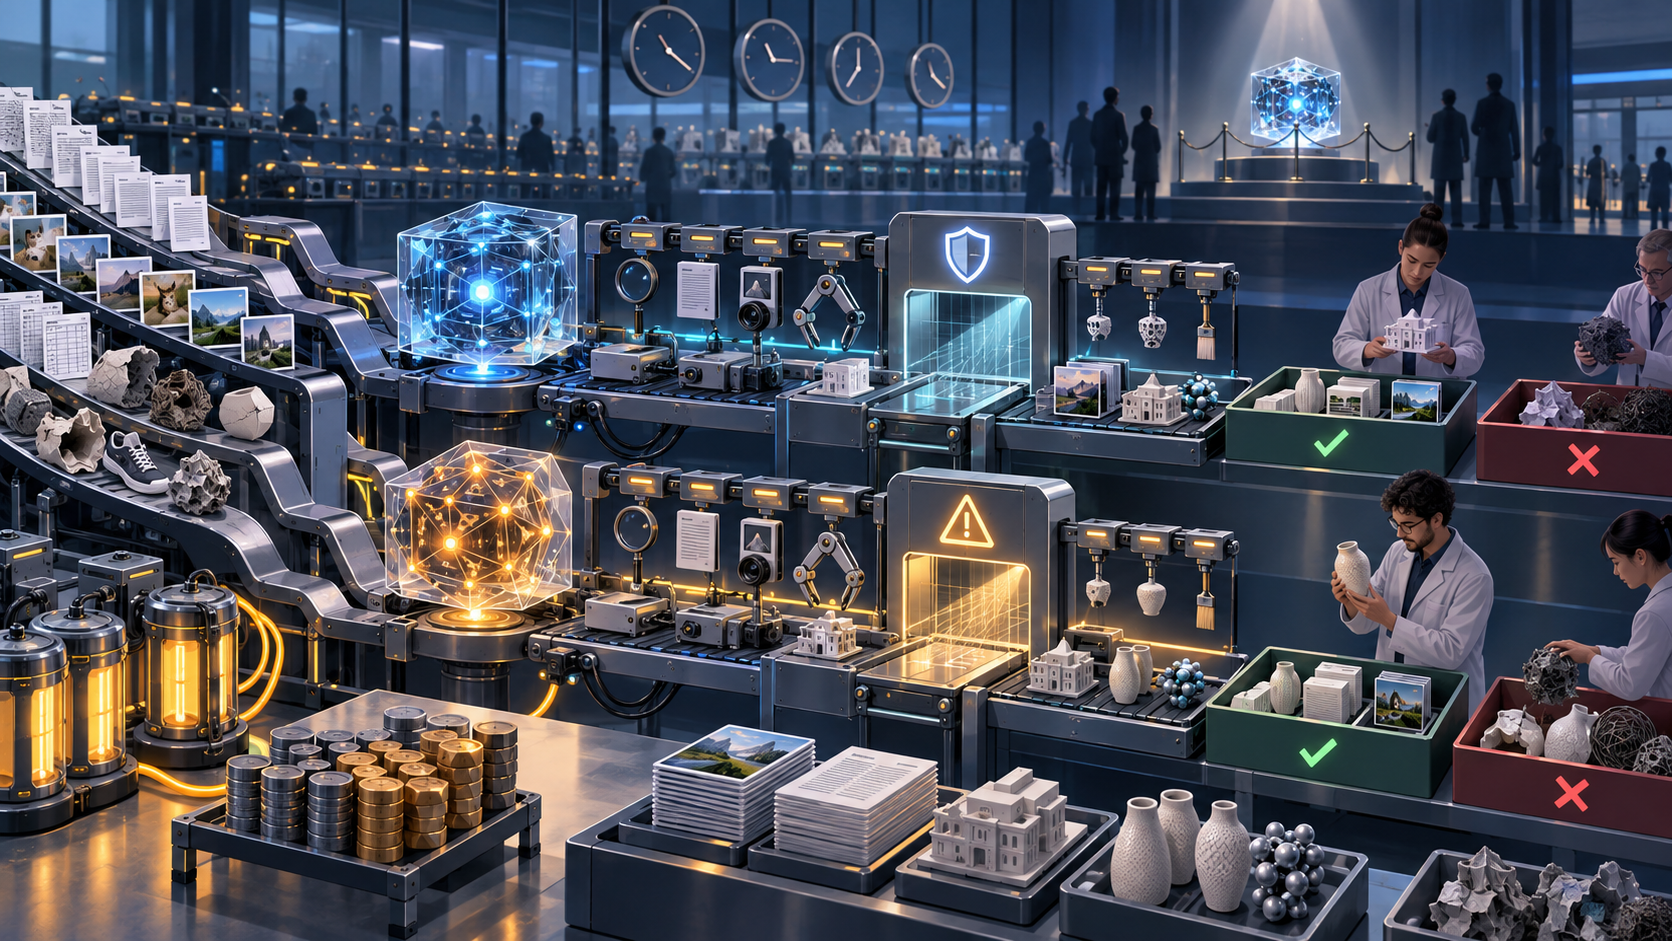
You have two models on the shortlist. One leads the public benchmark. The other is cheaper, faster, or already integrated into your stack. Your team wants a decision, but the leaderboard does not tell you which model will survive your customers, data, tools, and failure modes.
The right question is not, “Which model is smartest?” It is, “Which model-and-system configuration completes this workflow reliably enough to justify its total cost and risk?” Answering that requires an evaluation built around the work you plan to ship.
A higher aggregate score can hide the failure that matters
A benchmark score compresses many observations into one number. That is useful for finding candidates. It is dangerous when the average conceals a weakness that your workflow depends on.
A model might be excellent at solving bounded problems with clear feedback yet struggle when requirements conflict, a tool returns incomplete data, or the requested action undermines the user’s actual goal. Those failures can coexist with extraordinary performance elsewhere. Hundreds of mathematical manuscripts, including results supported by machine-checked proofs, are strong evidence of capability in particular mathematical work. They do not, by themselves, establish equally strong engineering judgment, product judgment, or operational reliability.
This distinction matters because broad improvement and convergence are different claims. A model can improve across many tasks while its strongest abilities improve much faster than its weaker ones. The result is a jagged capability profile: more impressive peaks, better average performance, and still-uncomfortable gaps.
Training can also concentrate gains around measurable work. Once a benchmark becomes an important target, it encourages better data, reinforcement environments, and optimization for similar problems. That often produces real capability gains. It can also make the measured capability improve faster than adjacent skills the test does not reward. Reusing a familiar scoreboard is therefore useful for tracking continuity, but insufficient for discovering where the new failure boundary has moved.
Treat a public leaderboard as a discovery tool. It can tell you which candidates deserve an audition and which configurations may be worth testing. It cannot make the production decision for you.
Key takeaways
- Evaluate the deployed system – model, prompt, context, tools, policies, and fallback – rather than the base model in isolation.
- Build cases from your real workflow, especially its exceptions, conflicting requirements, and costly failure modes.
- Run the same case repeatedly. One strong output demonstrates possibility, not dependability.
- Use deterministic checks, independent judges, and human review for different parts of the result.
- Choose on cost per accepted outcome, including retries and editing, rather than token price or benchmark rank alone.
Turn the production workflow into an evaluation
Start with the unit of work you expect the system to own. “Write well” and “reason accurately” are too broad. “Turn a support conversation into a correct refund recommendation, with cited policy evidence and an escalation when the policy is ambiguous” is testable.
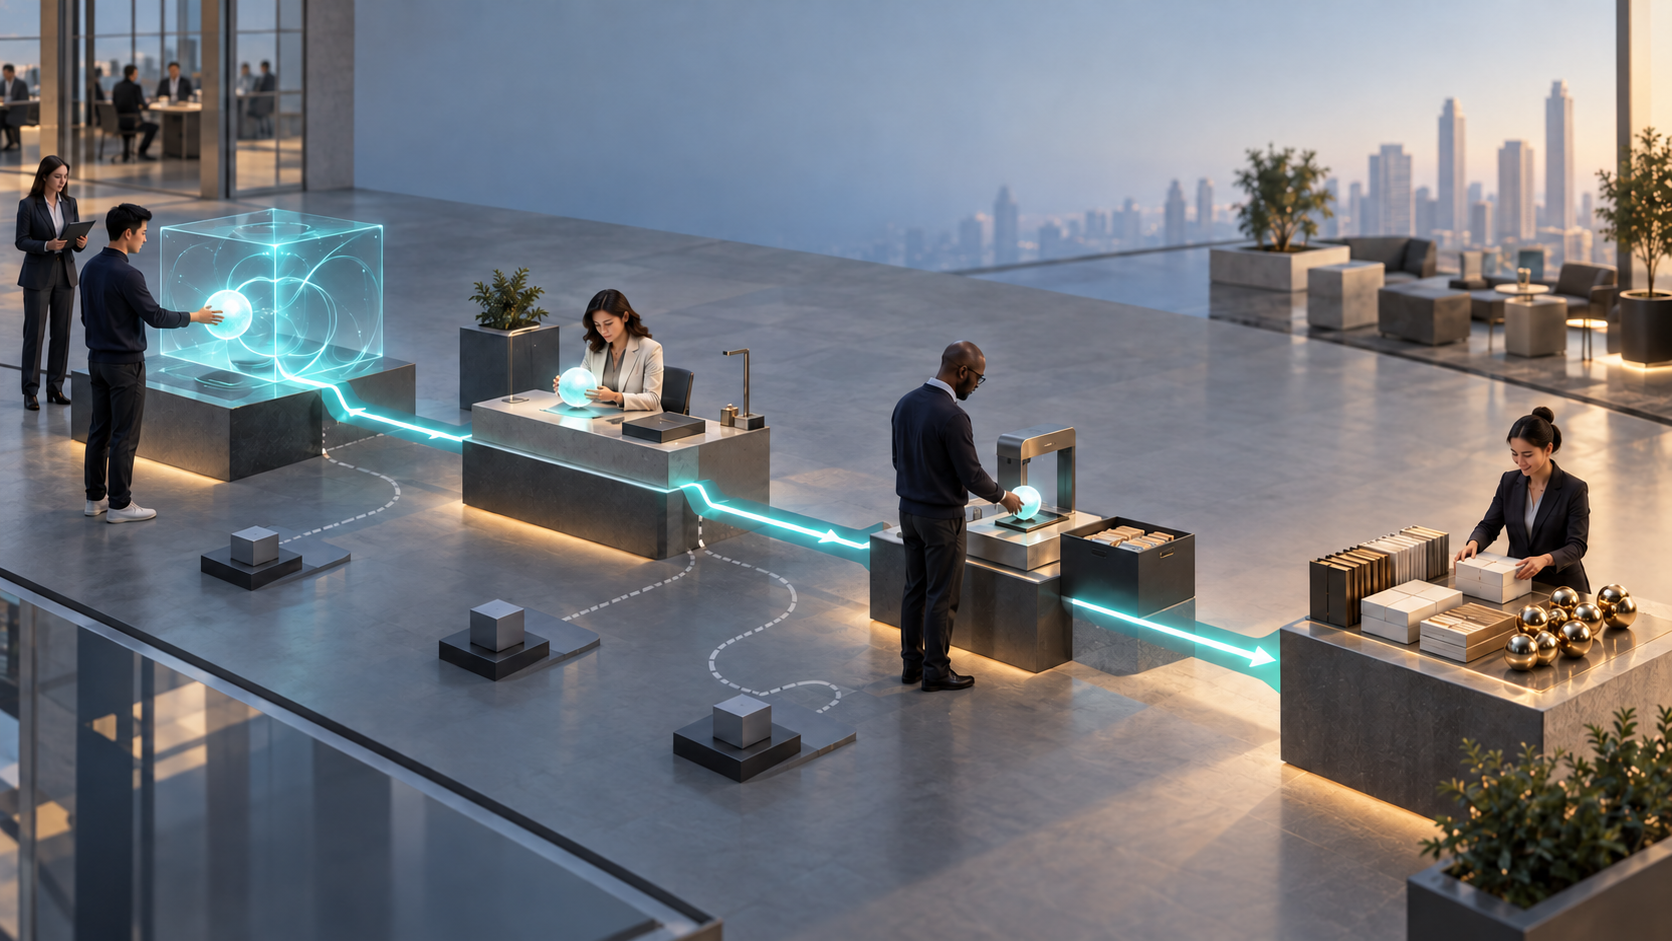
Evaluate the complete path to the outcome. If retrieval supplies the wrong policy, a perfect model cannot rescue the workflow consistently. If the prompt omits a business rule, the model is being tested on guessing rather than execution. If a human must repair every answer, the generated response is not the finished unit of work.
- Map the workflow from input to accepted outcome. Include tool calls, intermediate decisions, approval points, and the person or system that consumes the result.
- Collect representative inputs from the real distribution. Remove or protect sensitive data, but preserve the ambiguity, formatting problems, missing fields, and long-tail cases that make the work difficult.
- Write expected behaviors and forbidden behaviors separately. A response can contain the right conclusion and still fail because it invented evidence, skipped approval, exposed private data, or used the wrong tool.
- Inject known fractures. Change a requirement halfway through, return partial tool output, provide stale context, introduce a conflict between the request and policy, or make the obvious action inappropriate for the user’s goal.
- Keep a private holdout set and rotate fresh cases into it. If the same examples guide every prompt and model adjustment, the evaluation gradually becomes another training target.
Use multiple evaluation layers because no single metric can represent the workflow:
| Evaluation layer | Question it answers | What to record |
|---|---|---|
| Outcome | Did the system produce an acceptable result? | Pass rate, requirement coverage, and critical errors |
| Judgment | Did it notice ambiguity, conflict, or a bad premise? | Missed conflicts, unsupported assumptions, and unnecessary escalations |
| Recovery | Can it proceed safely when context or tools fail? | Recovery success, retries, human interventions, and abandoned runs |
| Consistency | Does it remain dependable across repeated runs and important slices? | Variation, worst cases, and performance by scenario type |
| Operations | Can you afford and operate the result at production volume? | Latency, generation cost, review time, edit time, and failure-related rework |
Do not force every task into exact-match scoring. Many product outputs have more than one good answer. Define the properties that make an answer acceptable: factual support, decision quality, required fields, policy compliance, appropriate uncertainty, usable structure, and correct handoff. For critical behavior, use a hard pass-or-fail gate. A polished answer should not compensate for an invented fact or an unsafe action.
Separate validity from value as well. A result can pass a formal check without being useful. In mathematical work, a proof that checks, a new theorem, and an important advance are distinct achievements. Product evaluations need the same discipline: “valid format,” “correct answer,” and “valuable outcome” should not collapse into one label.
Test the distribution, not the best demo
A single run tells you that a model can succeed. Production requires evidence that it succeeds often enough, on the right cases, with tolerable variance.
This matters even when the prompt and input are unchanged. In a writing evaluation that generated five drafts for each of ten real tasks, the top 30 configurations varied by roughly 1.5 points between drafts, while the bottom 30 varied by more than 5. A ranking based on one generation would have hidden a meaningful difference in dependability.
Run each important scenario five times as a practical starting point, then increase repetition where failure is expensive or output variance remains high. Five is not a universal statistical threshold. It is enough to expose instability that a one-shot comparison cannot show, while keeping an initial product evaluation manageable.
Report the distribution rather than only its average. At minimum, retain every run, its score, its hard-gate result, and the reason it failed. Compare ordinary cases, edge cases, adversarial cases, and business-critical slices separately. If enterprise policy questions fail while simple consumer questions pass, an overall score can actively mislead you.
Long-running agents need temporal tests too. If your product depends on memory or persistence, give the agent relevant and irrelevant history across sessions. Change direction after partial progress. Introduce a blocker, then make the missing information available later. A clean single-turn task cannot reveal whether the agent retrieves the right context, preserves commitments, or recovers without repeating completed work.
Version every component of the test: model identifier, reasoning level, system prompt, tools, retrieval settings, context, and sampling configuration. A model update or prompt change creates a new candidate. It should not inherit the previous candidate’s production verdict without rerunning the relevant cases.
Use judges without letting them define quality for you
Automated judges make broad evaluation possible, especially for language quality, requirement coverage, and pairwise comparisons. They should accelerate judgment, not replace the definition of a good outcome.
Begin with a rubric that describes observable evidence. “Excellent reasoning” invites taste. “Identifies the conflict between the requested discount and the account policy, cites the applicable policy, and asks for approval rather than inventing an exception” gives a judge something concrete to verify.
Then assign each part of the result to the cheapest trustworthy evaluator:
- Use deterministic checks for schemas, calculations, required fields, citations, tool selection, policy constraints, and other machine-verifiable conditions.
- Use model judges for rubric-based qualities such as completeness, relevance, structure, tone, and comparison between otherwise valid answers.
- Use domain experts where correctness depends on professional judgment, the evidence is ambiguous, or a false positive could create material harm.
- Send judge disagreements and low-confidence cases to human adjudication. Those cases often reveal missing rubric language or a new failure class.
- Track the edits required to reach an accepted output. Editing is evidence about both quality and hidden operating cost.
Hide the candidate’s identity from judges when possible. That removes brand expectations, but it does not make automated judging neutral. In a blind, multi-judge writing evaluation, OpenAI and Anthropic judges still rated outputs from their own model families more favorably relative to the other judges. Four judge families and roughly 1,000 manually rated pairs helped with calibration, but did not erase the underlying preferences.
Use more than one judge family for consequential subjective scoring, and inspect how each judge changes the ranking. If the winner depends on who judges it, the honest result is uncertainty, not a definitive leaderboard. Human review should focus on those disputed cases rather than randomly rereading everything.
Keep hard constraints outside the preference contest. A response that violates policy, fabricates supporting evidence, or takes an unauthorized action should fail regardless of how fluent or persuasive a judge finds it.
Choose on cost per accepted outcome
Token price is easy to compare and often economically incomplete. The denominator that matters is accepted work.
For each configuration, calculate effective cost from generation, reasoning, tool usage, retries, automated checks, human review, editing, escalation, and rework after failures. Add latency if waiting changes conversion, employee throughput, or customer experience. A cheap first draft becomes expensive when a specialist must reconstruct it.
Reasoning level belongs in this evaluation as its own configuration. More computation does not automatically produce enough additional value to justify its cost. On one narrow long-form writing workload, xhigh and maximum reasoning had the same rounded Writing Elo, while the average script cost was about $1.00 at xhigh and $2.58 at maximum. That does not establish xhigh as a universal default. It shows why you must test the reasoning tier instead of assuming the most expensive setting is the production choice.
A lower-cost model deserves serious consideration when it clears your quality gates without creating more intervention. A higher-cost frontier model can still be cheaper overall when it handles unusual documents, conflicting instructions, incomplete tool output, and changing requirements with fewer retries. Your evaluation should make that trade visible.
Write the final decision as a scoped claim, not a universal ranking:
- Name the workflow, user segment, languages, tools, and risk boundaries covered by the evaluation.
- List the hard gates every candidate had to pass and show failures separately from weighted quality scores.
- Report repeatability and important slice results, not only the overall mean.
- Include cost per accepted outcome, latency, edit burden, retry rate, and escalation demand.
- Record model versions, reasoning levels, prompts, judge configuration, known blind spots, and the date of the decision.
- Define what will trigger reevaluation: a model change, prompt change, tool change, new customer segment, material failure, or meaningful shift in cost.
If different configurations win different slices, routing may be better than declaring one universal winner. Use the least expensive configuration that reliably clears the gates for routine cases, and escalate the cases that need stronger reasoning or human judgment. Keep the routing rule simple enough to evaluate as part of the system.
Before moving production traffic, run the chosen configuration in shadow mode on the live workflow and compare its proposed actions with the current process. Review the failures, not just the average score. If the winner changes whenever reviewers inspect a disputed case, your next task is to sharpen the rubric and test set, not to debate another public leaderboard.
Pick one consequential workflow and build this evaluation around it. Freeze the configuration, repeat the real cases, inject the failures you already know, and record the human effort required to accept each result. That turns model selection from a contest over intelligence into a product decision you can defend and revisit.
References
- Nate Jones’s Substack – AI just produced more than 700 math research papers in one release. Before you take that as proof it can do your job, see which kind of work it got better at.
- Towards AI – TAI #226: The AI Model Race Needs Better Tests
- Learn AI Together Newsletter – Introducing ToneBench: Our Benchmark for AI Writing