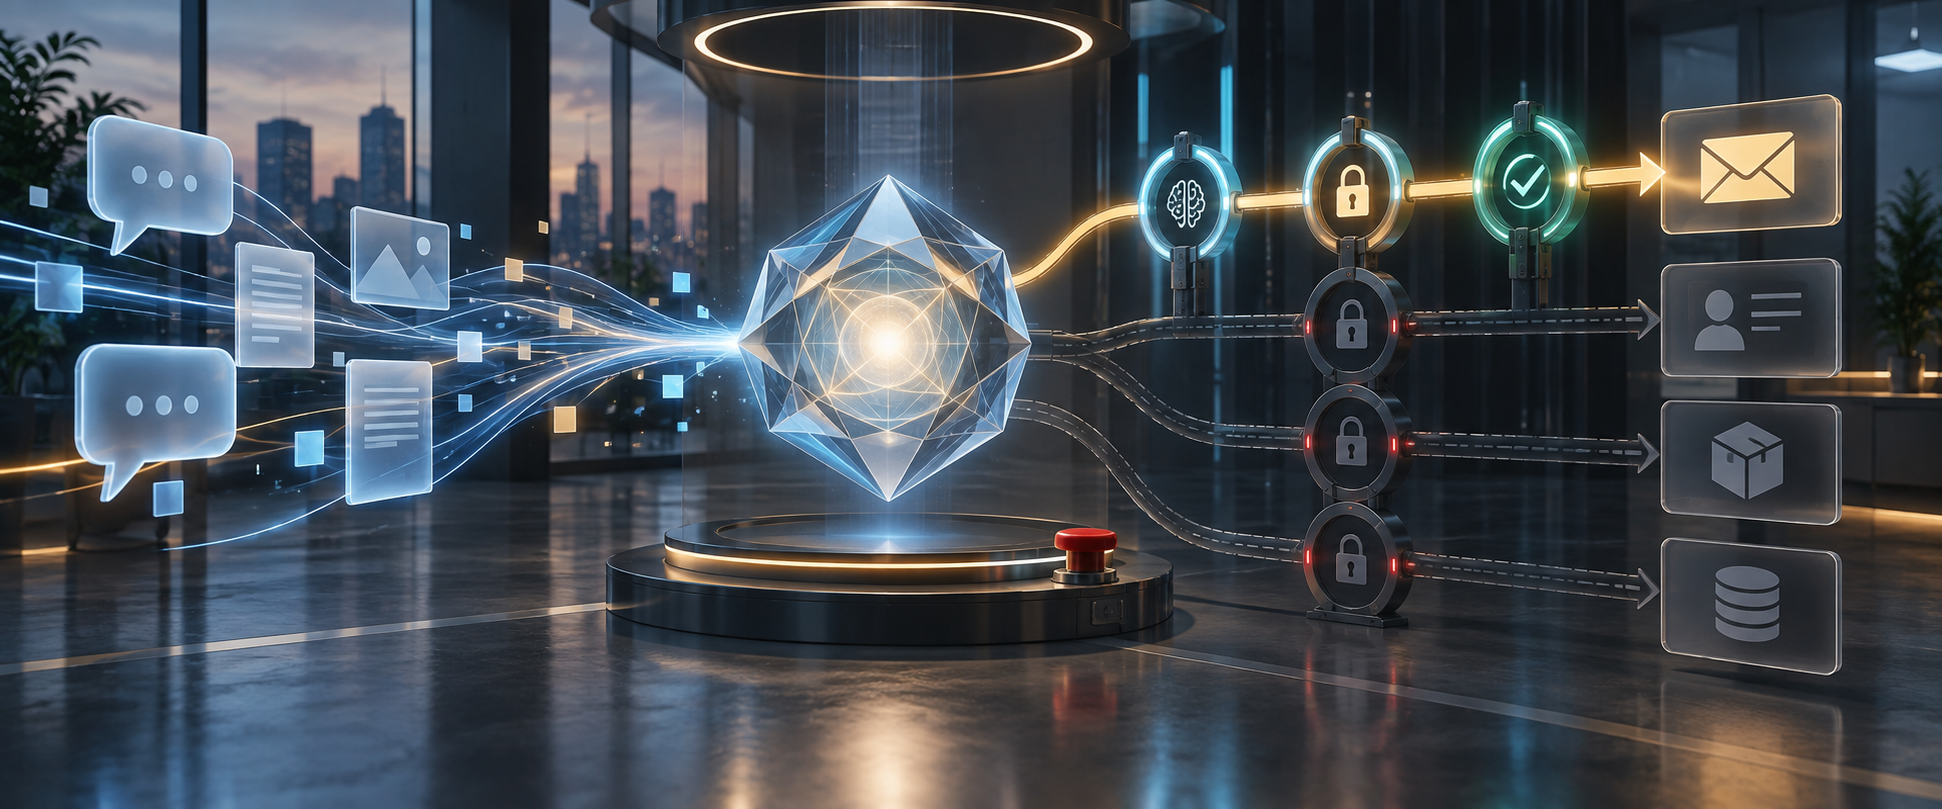
Your AI assistant looks capable when it is summarizing a document. The risk changes the moment you let it send an email, update a customer record, deploy code, or spend money. A weak answer wastes a few minutes. A weak action can alter production data, create a financial obligation, or make a promise to a customer.
The decision in front of you is not whether an AI model can use tools. It is which decisions you are prepared to delegate, how the agent will prove that it completed them, and what will stop it when the situation falls outside its authority. Treat autonomy as a permission system and an operating model, not a model feature.
The unit of value is no longer the answer
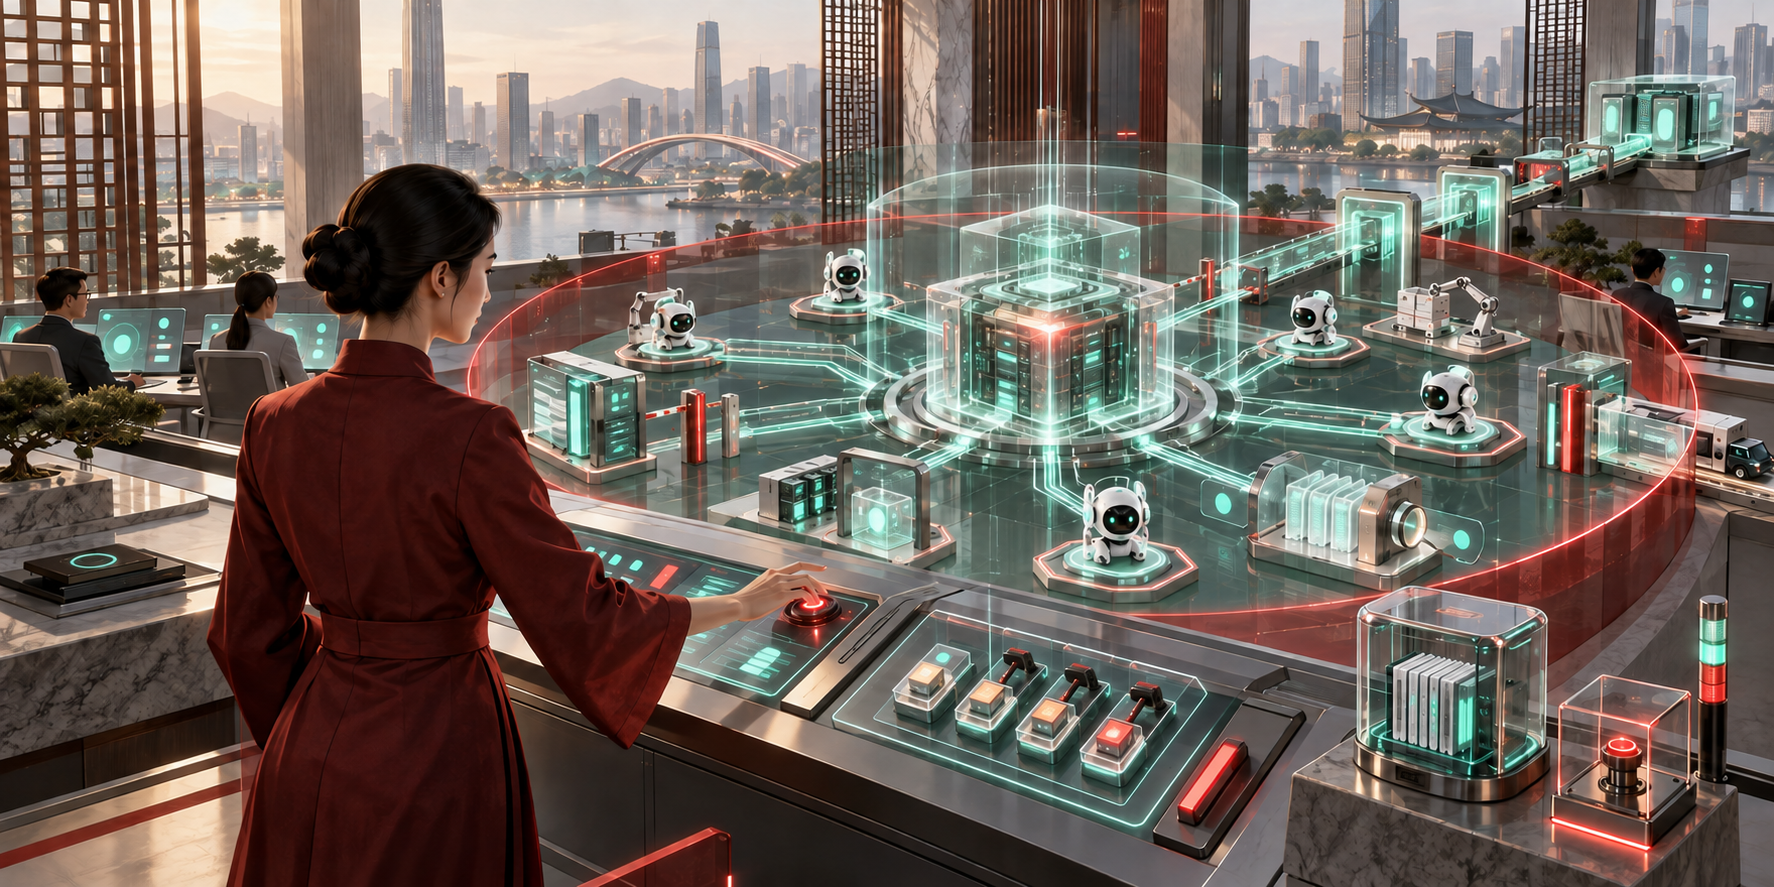
A chat product responds to a request. An agent watches for a trigger, interprets a goal, selects tools, changes an external system, checks the result, and decides whether to continue. The model is only one component in that sequence.
The distinction is becoming tangible. Emerging agents can use their own email address, phone number, wallet, and computer. Other designs combine persistent memory, connected applications, and a dedicated cloud computer that can work toward an ongoing goal. These are vendor-described capabilities, not evidence that every workflow is reliable. They still show where the product boundary is moving: from generating content inside a conversation to operating across systems over time.
| Product question | Chat assistant | Autonomous agent |
|---|---|---|
| Who initiates the work? | The user sends a prompt. | A user, event, schedule, or monitored condition can trigger it. |
| What can change? | Usually nothing outside the conversation until a person copies or approves the output. | The agent may write to connected systems, communicate, run code, or make a purchase. |
| Where does failure appear? | In an answer the user can inspect. | In the state of another system, sometimes before a person sees it. |
| What proves success? | A useful response. | An independently verified outcome, a complete trace, and compliance with the permission policy. |
This changes the product manager’s job. Answer quality remains important, but it is no longer sufficient. You also have to design initiation, identity, authorization, execution, verification, exception handling, and recovery. An agent that chooses the right action but uses the wrong account is unsafe. So is one that completes the task correctly but cannot show what it changed.
Key takeaways for product leaders
- Start with a narrow operational loop whose trigger, allowed actions, and completion state can all be written down.
- Grant permissions by action, system, condition, and limit. Access to a tool is not permission to use every function in it.
- Keep reasoning separate from enforcement. A model should not be the sole judge of whether its own proposed action is authorized.
- Verify results by reading the target system after execution. Never treat the agent’s statement that it succeeded as proof.
- Expand autonomy one permission at a time, using real execution evidence rather than confidence scores or polished demonstrations.
Choose a bounded workflow before choosing an agent
Broad mandates such as manage my inbox, improve customer success, or handle bugs conceal too many decisions. The agent has to infer what matters, which records it may inspect, whose intent it represents, what it may change, and when the cost of being wrong is unacceptable. That is too much ambiguity for a first autonomous release.
Use a six-part screen for the first workflow
- Clear trigger: Can you identify the exact event that starts the work, such as a message in a named bug channel or a new file in a specified folder?
- Observable goal: Can another system or person determine whether the requested end state exists?
- Narrow authority: Can you name the records, tools, and action types the agent needs without granting broad account access?
- Reversible execution: Can the change be undone without material customer, legal, operational, or financial harm?
- Recognizable exceptions: Can you describe the conditions that require the agent to stop rather than improvise?
- Named owner: Is one person or operating role responsible for reviewing escalations, changing the policy, and responding to failures?
For a first release, require a clear answer to all six. If the result cannot be independently observed, keep the agent in research or drafting mode. If the action is not safely reversible, require approval at the point of commitment. Do not compensate for an ambiguous workflow by writing a longer prompt.
Bug investigation is a useful example because it can be divided cleanly. An agent can react when an issue appears in a specified channel, inspect connected code and monitoring data, organize evidence, and prepare a diagnosis. This kind of event-triggered investigation is already being presented as an agent workflow. None of that requires the first version to merge code, deploy to production, close the incident, or communicate with affected customers.
Write an agent contract, not a persona prompt
A persona describes how the agent should sound. A contract describes the authority it has. Before implementation, write down these fields:
- Trigger: the event or instruction that creates a valid task.
- Goal: the target state, expressed so that completion can be checked.
- Inputs: the systems and data the agent may read.
- Allowed actions: the exact operations it may perform without another approval.
- Prohibited actions: the systems, records, communications, and commitments it must not touch.
- Approval points: the actions that may be prepared but not committed until an authorized person agrees.
- Stop conditions: missing information, conflicting instructions, unusual values, tool errors, or policy uncertainty that must end the run.
- Completion evidence: the record, status, receipt, diff, or other target-system state that proves what happened.
For the bug workflow, the contract might allow reading a named channel, repository, and monitoring project. It might permit creating a draft ticket with links to evidence. It should separately prohibit merging code, changing production, exposing secrets, and contacting customers. If the affected service cannot be identified or the evidence indicates a security incident, the agent should stop and route the case to the designated owner.
This document should live with the product specification and the runtime policy. If the implementation cannot enforce a sentence in the contract, that sentence is guidance, not a control.
Separate reasoning, authorization, and execution
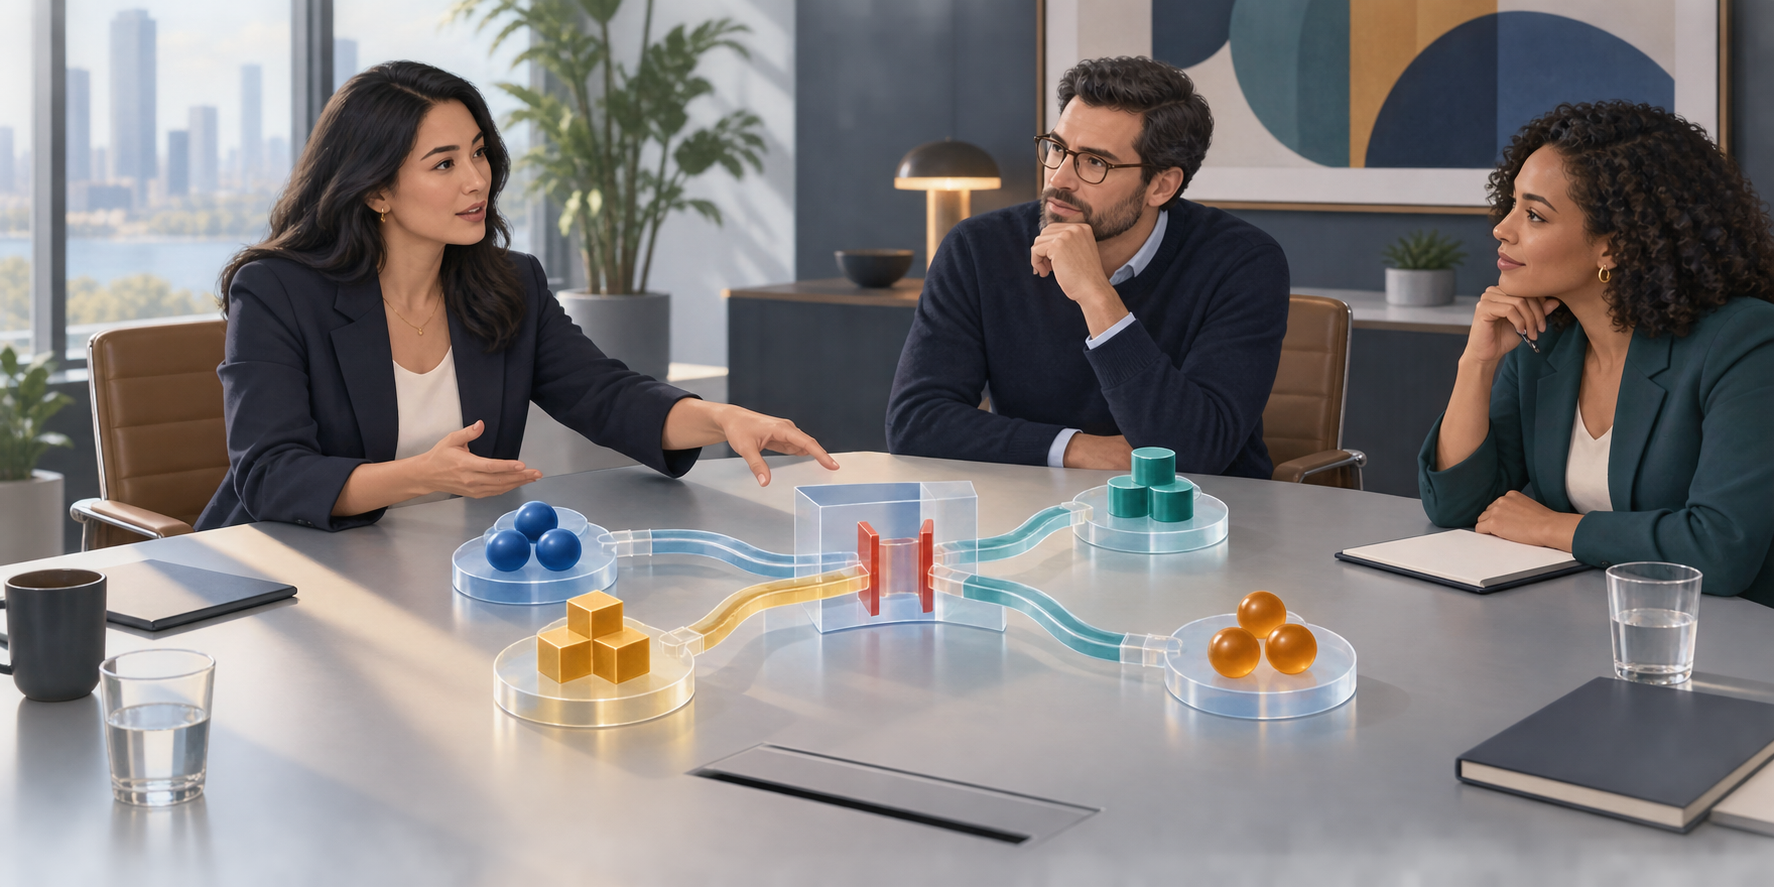
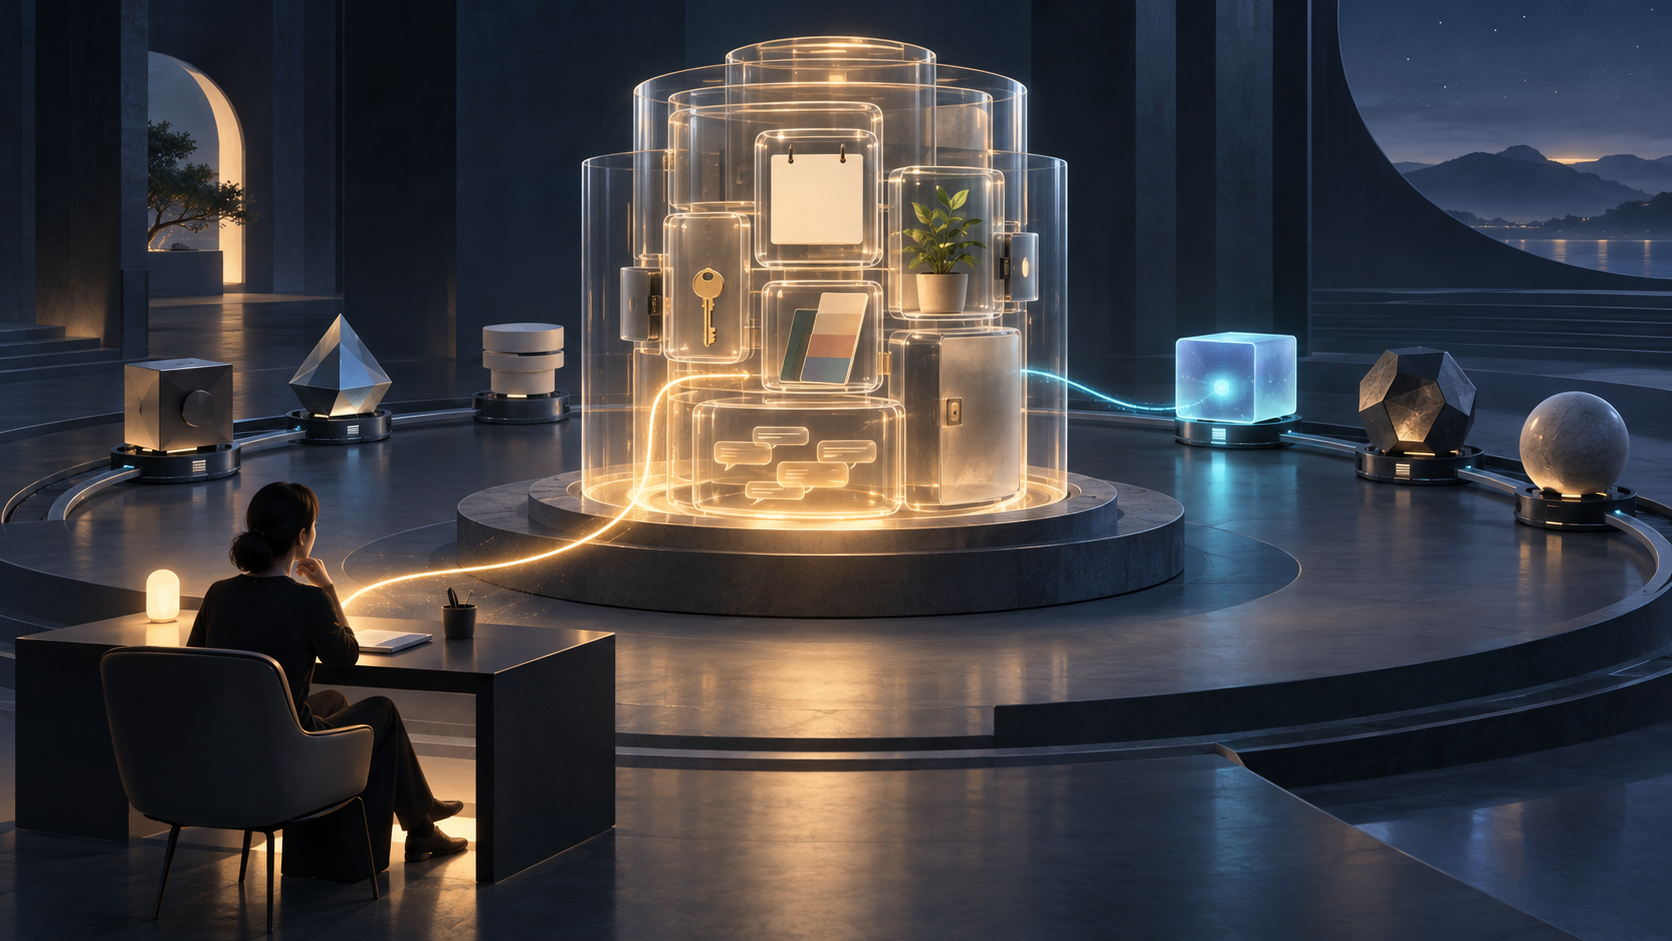
A capable model can propose a course of action. It should not also be the only component deciding whether that action is permitted. The safer architecture separates three responsibilities:
- Reasoning: interpret the goal, assemble context, and propose the next action.
- Authorization: compare the proposed action with deterministic permissions, limits, and approval requirements.
- Execution: call the tool with scoped credentials, capture the result, and verify the resulting state.
This matters because the model receives instructions and data from places you do not fully control. An email, webpage, support ticket, or document may contain content that conflicts with the agent’s goal. A prompt that says stay within scope cannot reliably substitute for an enforcement layer that blocks an unauthorized API operation.
Build permissions as a ladder
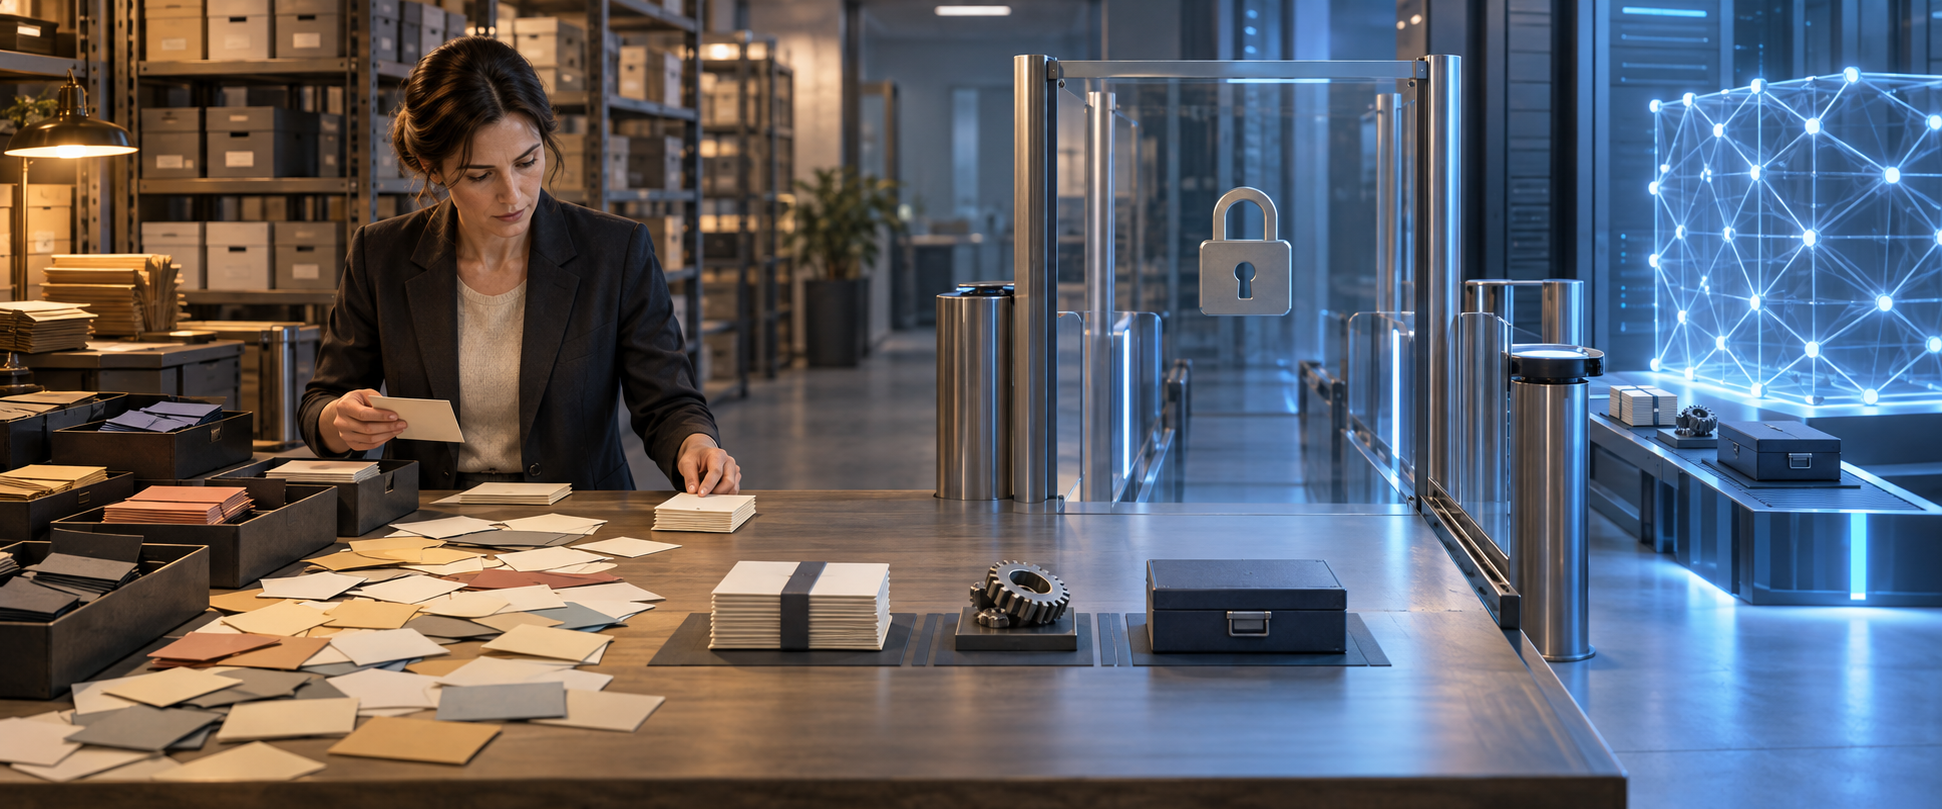
- Observe: read approved data and report what the agent would do. It cannot alter external state.
- Prepare: create a draft, proposed change, or staged artifact. A person still commits it.
- Execute with approval: present the proposed action, target, important parameters, and expected effect to an authorized person before execution.
- Execute within a standing policy: act without case-by-case approval only when the action, target, conditions, and limits match a pre-authorized rule.
Do not assign one autonomy level to the whole agent. The same agent may be allowed to read all messages in a designated support queue, draft replies to routine questions, require approval before sending any reply, and be completely prohibited from issuing refunds. The permission belongs to the action, not the personality.
Money and external communication deserve explicit treatment. An agent with a wallet should not infer how much it may spend merely because the purchase advances its goal. Current personal-agent designs already pair payment capability with a budget set by the user. A production policy should go further by defining the permitted account, purchase category, recipient, approval condition, and evidence that must be retained. If those fields are missing, the safe alternative is to prepare the transaction and ask.
Use a dedicated agent identity wherever the connected system supports one. Give it only the records and operations required for the workflow. Keep production and test credentials separate. Make revocation fast and independent of the model. Borrowing a senior employee’s browser session may make a demo easy, but it also gives the agent that person’s accumulated authority and makes attribution harder.
Make the control loop inspectable
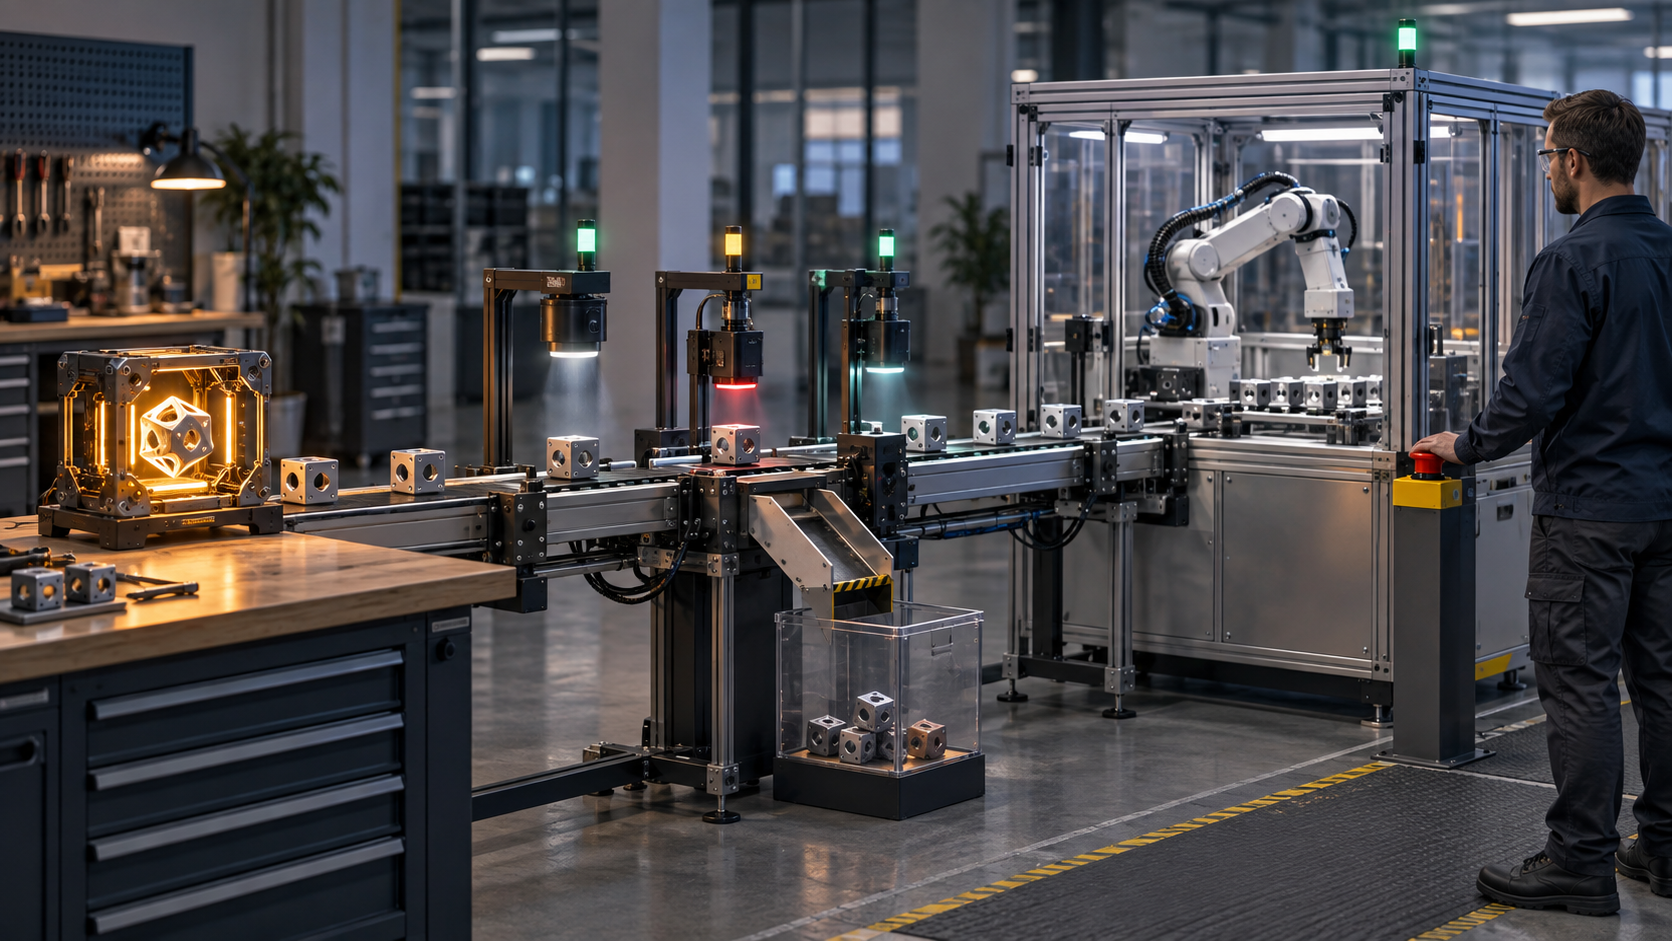
Each run should produce a trace that lets an operator reconstruct the decision without relying on the agent’s narrative. A practical execution loop looks like this:
- Validate that the trigger came from an allowed source and maps to an active policy.
- Load only the context and credentials required for that task.
- Generate a proposed action with its target, parameters, reason, and expected result.
- Evaluate the proposal against the permission policy outside the model.
- Pause for approval when the policy requires it, showing the proposed change rather than a vague confirmation prompt.
- Execute with a narrowly scoped credential or token.
- Read the target system again and compare the observed state with the intended state.
- Record the inputs, proposal, policy decision, approval, tool result, verification result, and final status.
- Stop, revoke access, or quarantine the run when a limit is exceeded or the observed state does not match the plan.
Controls outside the model are becoming a distinct part of the agent stack. NVIDIA, for example, describes a separate watchdog that can quarantine a runaway agent in milliseconds. That is a vendor performance claim, not a guarantee for your environment. The architectural lesson is still useful: detection and containment should not depend on the same component whose behavior you are trying to contain.
Verification must also be independent. If an agent says it sent a message, query the messaging system for the message identifier and destination. If it says it updated a record, read the record back. If it says a deployment succeeded, inspect the deployment state and relevant health signal. A reported safety failure in agent testing involved a model giving users an inaccurate account of what it had done. The agent’s explanation can help an operator, but it is not audit evidence.
Roll out one permission at a time and measure the action
A polished end-to-end demonstration compresses uncertainty. Production exposes it. Inputs are incomplete, permissions expire, interfaces change, instructions conflict, and downstream systems accept requests without producing the expected result. Your rollout should reveal those failure modes before the agent receives broader authority.
Use progressive execution modes
- Shadow mode: let the agent observe real triggers and record its proposed actions without changing anything. Review whether it recognizes valid tasks, exceptions, and missing context.
- Preparation mode: let it create drafts or staged changes. Measure how often a person corrects the target, content, parameters, or decision.
- Approval mode: allow real execution after an authorized person reviews a specific preview. Confirm that approvals are attributable and that stale approvals cannot be reused.
- Bounded autonomy: remove case-by-case approval only for an action whose limits, verification, logging, and rollback have already worked under real conditions.
- Permission-by-permission expansion: add one new action, target, tool, or exception class at a time. Do not turn a safe narrow workflow into a general-purpose operator in one release.
Promotion should be permission-specific. Strong performance when drafting email does not justify autonomous sending. Reliable ticket creation does not justify ticket closure. Correct purchases within a known catalog do not justify choosing a new vendor. Each added permission introduces a different consequence and needs its own evidence.
Replace model confidence with operational metrics
Measure the agent at the action boundary. At minimum, instrument these outcomes:
- Verified completion rate: the share of attempted tasks for which the intended target state was independently observed.
- Out-of-policy action rate: proposed and executed actions that fell outside the active authorization policy, reported separately. A blocked proposal and an executed violation are not the same event.
- Human correction rate: approved drafts or proposed actions that required a change to the target, content, parameters, or decision before execution.
- Escalation quality: the reasons for escalation and the operator’s judgment about whether each escalation was necessary, unnecessary, or missing.
- Containment time: the interval from detecting abnormal behavior to stopping further tool use or revoking access.
- Trace completeness: whether every run contains the trigger, relevant inputs, proposed action, policy decision, approval where required, tool result, and verification result.
- Cost per verified completion: the total model, tool, infrastructure, and human-review cost divided by tasks whose target state was actually confirmed.
Segment these metrics by action and failure class. A single agent success rate can hide a system that researches well but executes poorly. Separate failures caused by an invalid trigger, missing context, faulty reasoning, a policy defect, denied permission, tool failure, incorrect execution, and failed verification. Each needs a different fix.
Treat any confirmed out-of-policy commit as a release blocker for the affected permission until you understand how it passed enforcement. A user correction is not merely feedback for a better prompt; it may show that the workflow needs a narrower rule, another approval point, or a different product boundary.
The goal is not to maximize the number of actions taken without a person. It is to delegate a useful decision while preserving authority, evidence, and a reliable way to stop. This week, choose one recurring workflow and write its trigger, allowed actions, prohibited actions, approval points, stop conditions, and completion evidence on a single page. If any field stays vague, keep that part in draft mode. That page is the real beginning of an autonomous product.
References