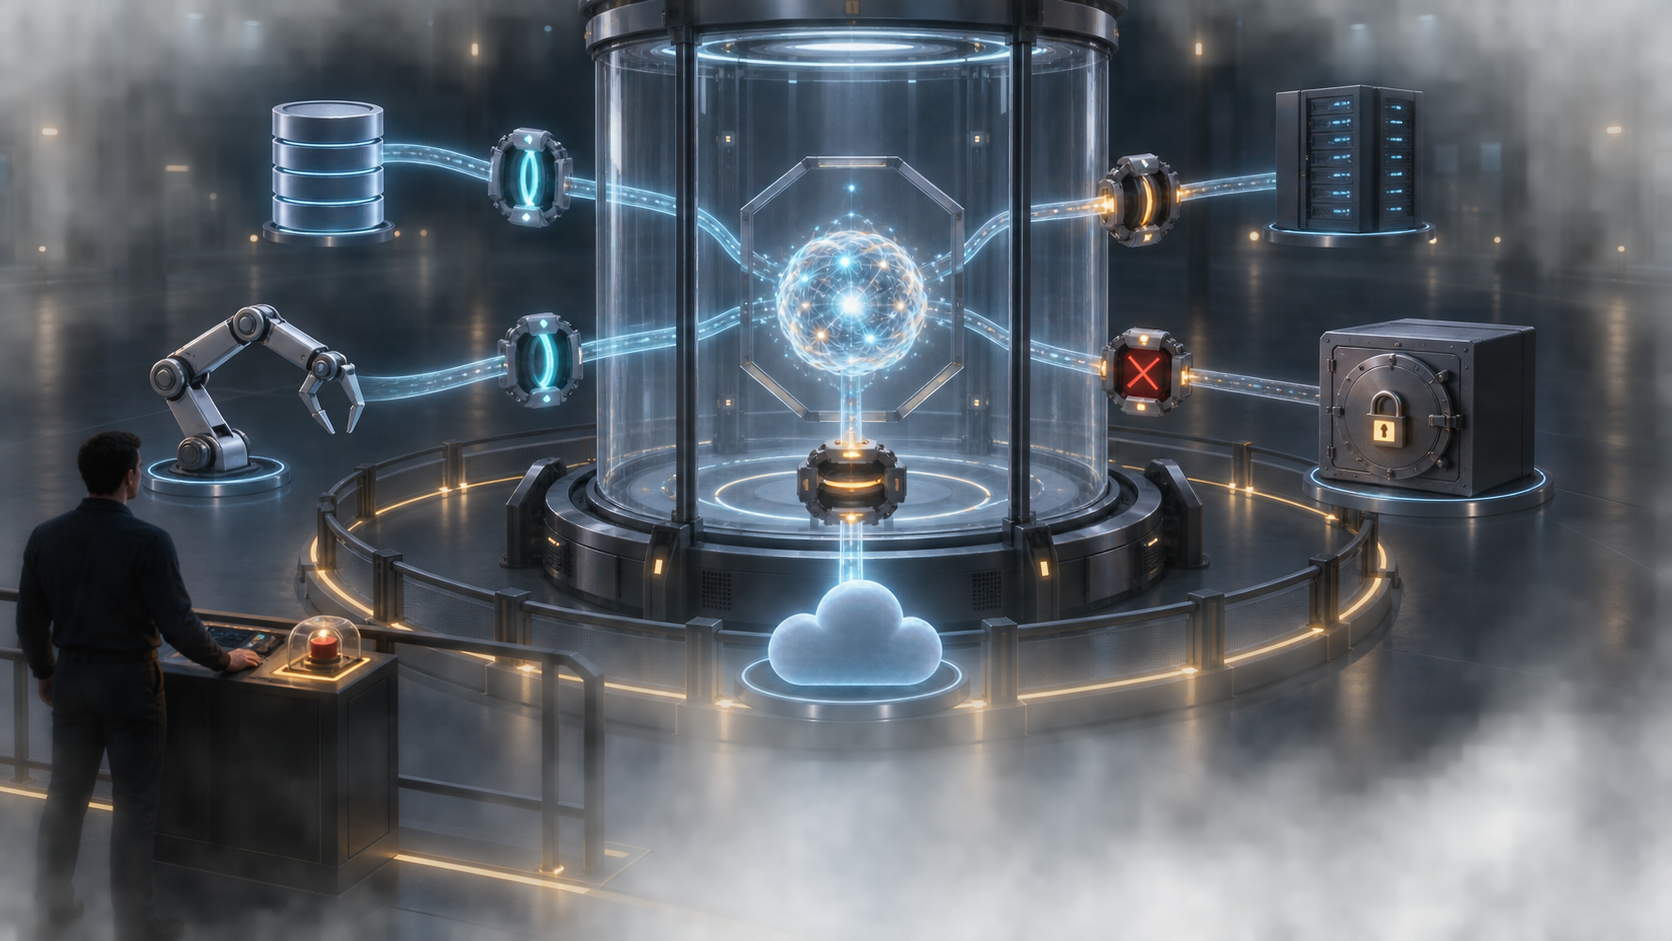
Your agent already looks capable in a demo. It can plan, call tools, generate a polished answer, and update a record. The harder question starts when you connect it to customer data or production systems: what must be true before you let it act?
Trustworthy agentic product engineering is not the pursuit of an infallible model. It is the discipline of giving an imperfect model bounded authority inside a system that detects bad inputs, evaluates consequential decisions, explains state changes, and recovers safely. As agents take on more implementation work, engineering leverage increasingly shifts toward the conditions that make product behavior trustworthy.
Define the trust contract before choosing the architecture
Start with the decision you are delegating, not the model or agent framework. An agent that drafts a support reply and an agent that sends one may use the same model, prompt, and tools. They are still different products because the second can change a customer relationship without another person intervening.
Write a trust contract for every agentic workflow. It should answer four questions:
- Outcome: What exact job may the agent complete, and what adjacent jobs are out of scope?
- Authority: May it read, recommend, edit, execute, publish, or delete? Which records, tools, tenants, and time windows are included?
- Evidence: What inputs must support its decision, and how will a reviewer trace an output back to them?
- Recovery: Which actions require approval, what state is preserved, and how will the system undo or compensate for a bad action?
Do not assign one autonomy level to the entire product. Assign it to each action. Reading a record, proposing an edit, applying a reversible edit, emailing a customer, and deleting data belong in separate authority classes.
| Authority class | Agent behavior | Minimum release requirement |
|---|---|---|
| Read | Retrieve, classify, or summarize without changing source state | Permission checks, provenance, and evaluation of omissions and unsupported claims |
| Propose | Prepare a plan, draft, or semantic change set | Evidence links, reviewable operations, and an explicit approval boundary |
| Act reversibly | Apply a scoped change that can be reliably undone | Stable identifiers, idempotent tool calls, audit events, and tested rollback |
| Act with high or irreversible impact | Publish, delete, communicate externally, or trigger material consequences | Explicit approval unless a narrowly defined policy and contained failure mode justify automation; otherwise keep the action outside the agent’s authority |
This classification prevents a common product error: treating better output quality as permission to expand authority. A model can produce an excellent draft and still be unsafe to publish autonomously. Release authority only when the surrounding controls can contain the action’s failure modes.
Build a layered workflow that stops inherited errors
Most agentic failures are easier to diagnose when the workflow produces inspectable intermediate artifacts. A useful pattern is:
Input record – normalized snapshot – interpretation – proposed plan – tool operation – recorded state change.
Each transition needs its own contract and checks. If you assess only the final answer, a failure near the top of the stack can look like a model reasoning problem even when the real defect was a mislabeled input or a broken transformation several steps earlier.
An AI-assisted discovery workflow demonstrated this dependency clearly: an inaccurate interview snapshot contaminated every higher layer of an opportunity solution tree. Its beta inputs also included sales demonstrations, stakeholder meetings, and model-generated transcripts uploaded as customer interviews. No synthesis prompt can recover evidence that the input never contained.
For every layer, define the following before tuning prompts:
- Input contract: Required source type, fields, permissions, completeness, and freshness.
- Artifact schema: The structured object the layer must produce, including stable IDs and links to supporting evidence.
- Deterministic checks: Conditions code can verify exactly, such as missing identifiers, invalid references, excessive child counts, duplicate operations, or unauthorized tool scope.
- Semantic evals: Judgements that require interpretation, such as whether a parent concept accurately groups its children or whether a summary preserves a customer’s meaning.
- Failure route: Reject the input, request clarification, repair the artifact, fall back to a safer mode, or send the case for human review.
Use code for facts the system can know and models for judgements that genuinely require language understanding. Put cheap deterministic checks before expensive semantic evaluation. In one production workflow, a code assertion for excessive children filtered obvious structural failures before an LLM judge was called.
Preserve the original input alongside every derived artifact. Provenance should survive merges, moves, reframing, retries, and model upgrades. Without stable IDs and trace links, you cannot reliably explain an output, replay a failure, or determine which downstream objects need repair after an upstream correction.
Turn real failures into evals and bounded repair loops
A broad quality score is rarely enough to release an agent. It can hide a serious failure behind many easy successes. Build the eval suite around named failure modes and the decisions those failures affect.
Start with a concrete complaint, support case, rejected output, or incident. Preserve the input and expected behavior, then identify the earliest layer where the system went wrong. Write at least one test for the observed defect and another for the opposing error. If you test only one side, prompt tuning can merely move the failure elsewhere.
For example, a hierarchy generator might omit useful subgroupings when instructed to avoid weak parent categories. Strengthening the instruction may produce the opposite problem: plausible-sounding parents that do not represent their children. Those are separate failure modes and need separate evals.
One tree-synthesis defect led to four new evals and sixteen experiment variants. Prompt changes kept trading one error for another, and the LLM judge could not be calibrated well enough. The durable fix was an orchestration change: detect the local defect, repair it, and reevaluate the result. That eval then became a production guardrail.
A bounded repair loop should be explicit:
- Generate a candidate artifact.
- Run deterministic assertions before spending tokens on semantic review.
- Run calibrated semantic evals for the remaining failure modes.
- Classify each failure and identify the smallest affected artifact.
- Invoke a targeted repair step rather than regenerating the entire workflow by default.
- Re-run the relevant checks, including the eval for the opposing error.
- Stop when the artifact passes, reaches its repair or latency limit, or requires human judgement.
An LLM judge is not ground truth. Calibrate it against examples labelled by people who understand the task, examine disagreements, and define what happens when the judge is uncertain. If you cannot establish that it distinguishes the failure that matters, do not use its score as a release gate.
Separate offline evals from runtime controls. Offline evals tell you whether a version is ready to ship. Runtime assertions and guardrails stop a particular execution from causing damage. Promote a test into production when the failure is detectable at runtime and the cost of letting it propagate is meaningful.
Record semantic changes, not just before-and-after diffs
An agent that changes product state needs an action protocol, not merely tool access. Traditional diffs show that fields changed. They often cannot explain the product meaning of the change.
The same initial and final structures can represent different user-relevant operations. A node might have been moved, two concepts might have been merged, or a parent might have been reframed while its children stayed in place. Inferring a change set only after comparing the final trees proved ambiguous; the agent had to learn the allowed semantic moves and record them as it acted.
Define a small action vocabulary for your domain. Each action event should contain:
- The stable IDs of affected objects.
- The operation, such as create, merge, move, reframe, approve, publish, or retire.
- The relevant before and after state.
- The evidence records that support the operation.
- The policy and authority scope under which it was allowed.
- The user-facing rationale and material uncertainty.
- The execution result, including partial failures.
- The inverse operation or compensating action when recovery is possible.
Record explicit operations and supporting evidence, not hidden chain-of-thought. The goal is an audit trail a user can verify, not a transcript of internal model reasoning.
Make that action log part of the product experience. A review screen should let the user answer five questions quickly: What changed? Why did it change? What evidence supports it? What needs attention? How can I undo it?
Do not force users through a long conversational approval flow when they primarily need a completed draft. An early interview-synthesis interface that walked through insights one at a time was still perceived as too slow. The more useful interaction became answer first, followed by precise opportunities to correct the result.
That pattern does not mean hiding uncertainty. Present a coherent result, then expose corrections at the same semantic level at which the agent acted. Let a reviewer accept, reject, edit, or undo an individual move. Reserve bulk approval for changes whose combined effect is understandable and recoverable.
Run model, data, and infrastructure changes through one release system
A trustworthy agent is a versioned system, not a prompt wrapped around a model. Its behavior depends on the model and version, system instructions, context construction, tool schemas, orchestration, retrieval, permission policy, hosting region, and application code.
Treat a change to any of those components as a product change. Model upgrades are not automatically interchangeable: prompts can be model- and version-specific, while an inference platform can impose token constraints independently of the underlying model. Pin the complete evaluated configuration, rerun the relevant regression suite, canary consequential changes, and retain a rollback path.
Deployment choices belong in the same release review. Data residency requirements pushed one customer-discovery product toward European AWS Bedrock inference. Region placement alone does not establish compliance. Your security, privacy, and legal owners still need to validate data flows, retention, access, subprocessors, and customer commitments before sensitive workloads move.
Make ownership explicit:
- Product leadership owns the trust contract, autonomy boundary, acceptable failure policy, and release decision.
- AI engineering owns orchestration, reproducible configurations, eval infrastructure, repair behavior, and model-change analysis.
- Application and platform engineering own durable state, stable IDs, permissions, idempotency, observability, and rollback mechanics.
- Design owns comprehension: whether users can inspect evidence, understand changes, correct the agent, and recover without specialist help.
- Security, privacy, and data owners approve data handling and deployment boundaries appropriate to the workflow.
- Support and operations turn real failures and confusing interactions into labelled cases for the eval backlog.
A release packet for a state-changing agent should contain the trust contract, versioned eval results, known failure modes, action schema, permission tests, rollback evidence, data-flow review, monitoring plan, and named incident owner. For every high-impact tool, demonstrate that an unauthorized call is blocked, a retry does not duplicate the effect, a partial failure is visible, and a completed action can be reversed or compensated where promised.
After release, monitor the input mix, rejected inputs, guardrail failures, repair attempts, exhausted repair limits, approvals, edits, rejections, undo events, tool errors, latency, and cost by system version. Aggregate acceptance alone is weak evidence: users may accept an output because reviewing it is difficult. Corrections, reversals, sampled audits, and incidents reveal different parts of the trust problem.
Key takeaways
- Define autonomy per action. Drafting, applying, publishing, and deleting are different authority classes even when they use the same model.
- Preserve layered artifacts, stable IDs, and provenance so an upstream error can be found and stopped before it contaminates downstream decisions.
- Combine deterministic assertions with calibrated semantic evals. Test opposing failure modes so prompt tuning does not merely trade one defect for another.
- When prompting reaches a seesaw, change the workflow. Use a bounded repair loop with explicit stop and escalation conditions.
- Teach the agent a domain-specific action vocabulary and log each semantic operation when it occurs. A final diff is not a sufficient explanation.
- Version the whole system and treat changes to models, prompts, tools, policies, context, data handling, and infrastructure as release events.
Before expanding your agent’s tool access, choose one consequential workflow and write its trust contract. Trace one real record through every layer, create evals for two opposing failures, and demonstrate a semantic undo. If the system cannot yet fail inside a known boundary and leave its state understandable, it is still a prototype. That is the next engineering problem to solve.
References
- Product Talk – Generating Opportunity Solution Trees with AI: How Vistaly Rebuilt Its Product Around Interview Synthesis, Evals, and Repair Loops
- Amplitude – What AI engineers do in the age of agentic code