
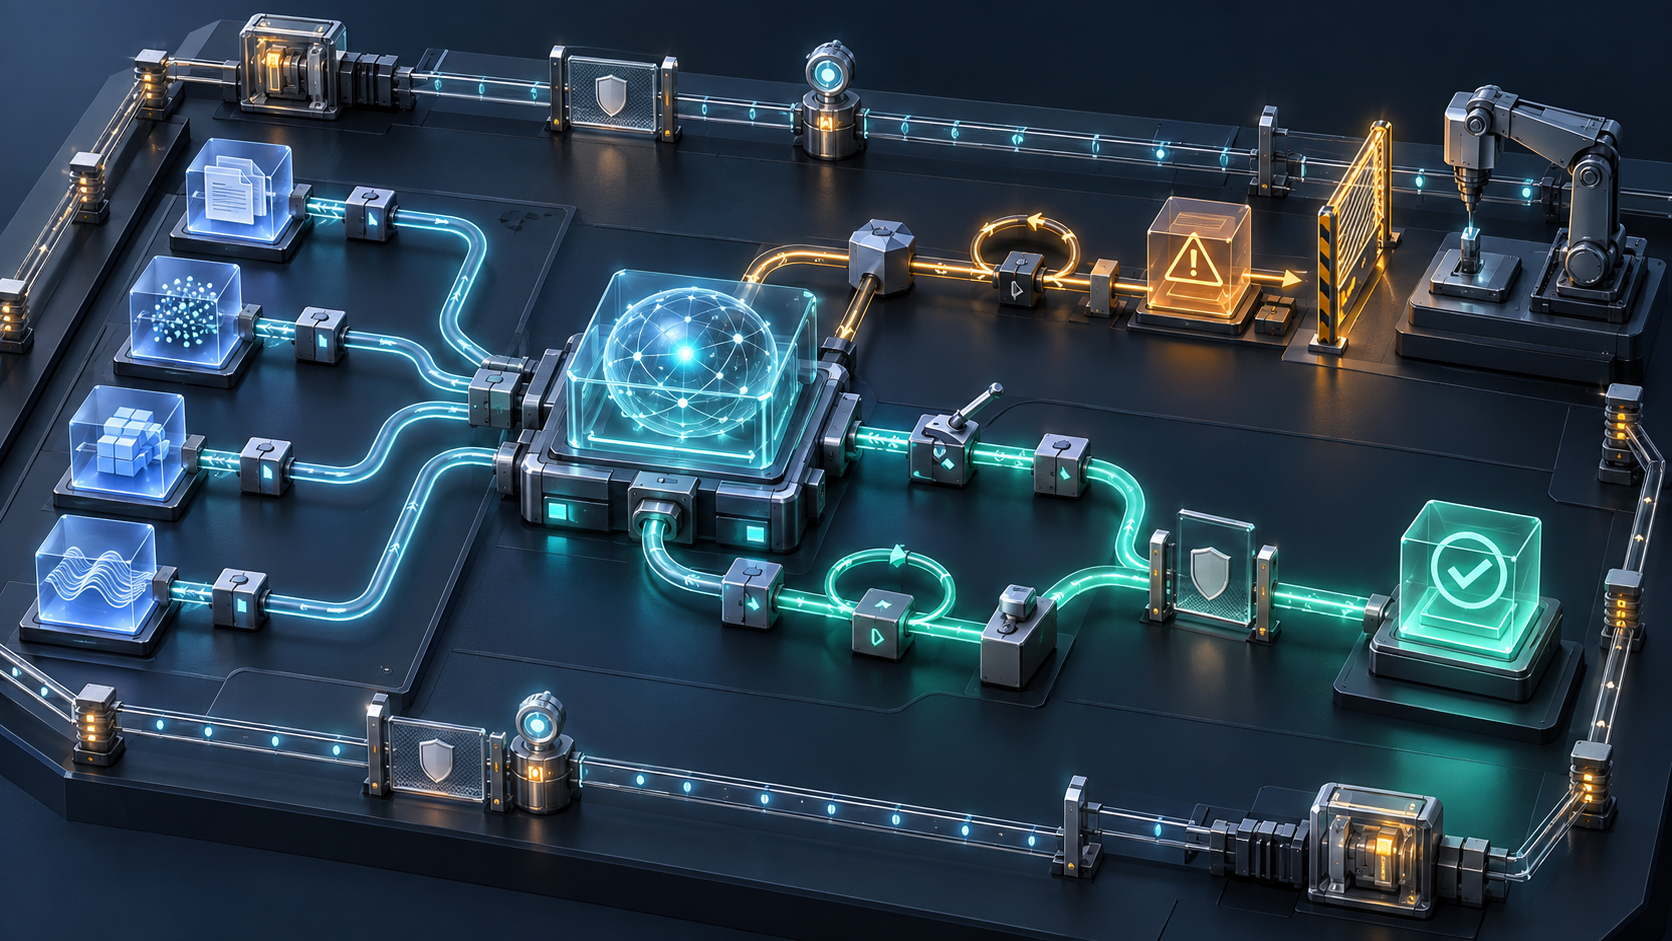
Your agent can ace a demo and still break at the seams in production. A router chooses the wrong specialist. Retrieval supplies relevant-looking but unsuitable context. A timed-out tool call is retried and creates a duplicate side effect. A planner keeps working after the useful path has disappeared. Another prompt revision will not fix these failures as a class.
Reliable orchestration does not mean the agent always succeeds. It means the full workflow is designed to recognize uncertainty, contain failure, expose what happened, and recover safely. That gives you a product users can trust and a system your team can operate.
Define the reliability contract before choosing an architecture
Your first design artifact should not be an agent diagram. It should be an operational contract for one narrowly defined workflow. If the team cannot agree on what counts as success, what the agent may change, and when it must stop, adding planners and specialists only distributes the ambiguity.
Write the task contract in product language
A useful contract answers questions that can be tested rather than debated after an incident:
- Intended outcome: What observable state should exist when the task is complete?
- Required inputs: Which fields, permissions, and evidence must be present before work begins?
- Allowed evidence: Which knowledge sources are authoritative, and what should happen when they conflict or return nothing?
- Authorized tools: Which tools may this workflow call, with which operations and scopes?
- Side-effect boundary: May the agent only recommend and draft, or may it send, edit, purchase, refund, delete, or publish?
- Completion proof: What postcondition demonstrates that the intended result actually occurred?
- Abstention conditions: Which missing inputs, policy conflicts, validation failures, or uncertain outcomes require the agent to stop?
- Escalation path: Who receives the case, and what context must accompany it so the human does not restart the investigation?
- Execution budget: What limits apply to elapsed time, model usage, tool calls, replanning, and spend?
Suppose the workflow drafts a customer-support response. Generate a helpful answer is too vague to serve as its contract. A testable outcome is an evidence-backed draft that addresses the identified issue, cites approved knowledge, makes no account changes, and routes the case to a person when the available guidance is missing or contradictory. That definition determines the retrieval policy, permissions, eval rubric, and user experience.
Separate automation from correctness when you classify outcomes. Otherwise, a team can make automation look safer by escalating nearly everything, or make completion look better by allowing the model to guess.
| Outcome | What it means | How to treat it |
|---|---|---|
| Correct autonomous completion | The intended outcome and every required postcondition were satisfied without human intervention. | Count it toward task success and automation. |
| Correct completion through fallback | A deterministic path or approved human action produced the intended result. | Count the outcome as successful, but report the fallback separately. |
| Correct escalation | The workflow encountered a defined abstention condition and transferred a complete case safely. | Measure it as correct handling, not autonomous completion. |
| Contained failure | The task could not finish, but no unauthorized or misleading result reached the user. | Investigate availability or coverage without confusing it with harmful completion. |
| Incorrect or unauthorized completion | The workflow claimed success incorrectly, used unsuitable evidence, or crossed its action boundary. | Treat it as a reliability failure regardless of latency or user-visible fluency. |
This outcome model also clarifies an important product decision: abstention is not automatically a defect. When the contract requires escalation, a well-supported refusal can be the correct behavior. The defect is failing to recognize the condition, escalating without useful context, or pretending the task succeeded.
Match the orchestration pattern to the uncertainty
Do not start with a multi-agent system because the workflow sounds sophisticated. Start by locating the uncertainty. Is the agent missing authoritative knowledge, deciding which capability applies, or discovering a variable sequence of actions? The answer points to the simplest useful topology.
| Pattern | Use it when | Main failure to control | Essential guardrail |
|---|---|---|---|
| Retrieval-first pipeline | The result depends on approved, current, or workflow-specific knowledge. | Missing, stale, irrelevant, or conflicting evidence. | Validate retrieval before generation and abstain when the evidence policy is not satisfied. |
| Router-specialist | Requests span distinct skills, policies, tools, or data domains. | Misrouting or giving a specialist access outside its purpose. | Use a typed routing decision, a closed set of destinations, and permissions scoped to each route. |
| Planner-executor | The task genuinely requires a variable sequence of dependent steps. | Invalid plans, unbounded loops, premature actions, or compounding errors. | Validate plans and preconditions, enforce budgets, and verify each result before continuing. |
These retrieval-first, router-specialist, and planner-executor patterns can be combined, but combination should follow a demonstrated need. If deterministic code can choose a specialist from a known request type, a model-based router adds uncertainty without adding value. If a workflow always performs the same approved sequence, a planner is unnecessary.
Use a visible state machine, even when a model proposes the next step
The model may recommend a route or plan, but the orchestrator should control the state transition. A practical workflow looks like this:
- Admit: Validate the request, identity, permissions, required fields, and task budget.
- Ground: Retrieve permitted context and record the evidence references used for the task.
- Select: Choose an approved specialist or produce a bounded plan.
- Validate: Check the route, plan, arguments, policy, and action preconditions before execution.
- Execute: Call the tool through a typed interface with timeout and idempotency controls.
- Verify: Confirm the tool result and the business postcondition rather than trusting a success-shaped response.
- Resolve: Complete, fall back, abstain, or escalate with an explicit final disposition.
This structure prevents conversational fluency from becoming operational authority. A planner can propose an account update, for example, but only the control layer can determine that the account exists, the user has permission, the payload is valid, approval is present, and the action remains within budget.
Treat context as an allocated resource
More context is not automatically better context. Long transcripts, unrelated memory, and loosely matched documents can obscure the evidence that matters. Give each step only the context needed for its decision:
- Prefer retrieval from authoritative stores over relying on model recall.
- Keep retrieved passages semantically focused and retain their evidence identifiers.
- Check that a retrieved passage answers the actual question, not merely that it is the nearest match.
- Summarize long-running threads deliberately instead of carrying every prior token forward.
- Give memory an explicit scope and time-to-live so stale state does not silently become policy.
- Isolate specialist context so one route does not inherit data or instructions intended for another.
The retrieval result itself needs evaluation. If the correct evidence was never supplied, scoring only the final wording sends the team toward prompt changes when the real defect sits upstream.
Put deterministic controls around every probabilistic step
The model should handle interpretation and generation where those capabilities are useful. Deterministic software should control types, permissions, budgets, retries, state changes, and release exposure. This division does not eliminate uncertainty; it stops uncertainty from propagating unchecked.
Make every boundary typed and versioned
Free-form text is a poor contract between agents and tools. Require structured outputs and validate them before another component consumes them. A useful envelope can include:
task_id,trace_id, andschema_versionso the event can be located and interpreted.- A closed
statusvalue such as proposed, approved, completed, abstained, or failed. - The intended action and typed arguments, separate from the model’s explanatory text.
- Evidence references and the policy basis for the proposed step.
- The expected postcondition that will be checked after execution.
- A structured error or escalation reason when the step cannot continue.
- The remaining execution budget and the permitted next states.
Reject unknown fields where they could alter behavior. Validate enumerations, required properties, identifiers, and ranges. Version schemas and tool signatures so a deployment cannot silently change the meaning of a field while an older planner or queued task is still using it.
A repair attempt can be appropriate for a malformed, non-executed proposal. It should not happen after a side effect unless the system knows whether that effect occurred. The distinction is operationally critical.
Design retries for unknown outcomes, not just explicit failures
A timeout does not prove that an action failed. The remote system may have completed the action before the response was lost. Blindly retrying a message send, invoice creation, refund, or record update can duplicate the result.
Assign an idempotency key to each side-effecting intent before execution, and persist the relationship between that key, the requested action, and its observed status. When the response is uncertain, reconcile against the downstream system before retrying. If reconciliation is unavailable and duplication would be harmful, stop and escalate instead of gambling on another call.
Typed interfaces, idempotency controls, timeouts, circuit breakers, backpressure, rate limits, and dead-letter handling solve different parts of the failure problem:
| Condition | Safe system response | What to avoid |
|---|---|---|
| Invalid model output | Reject it before execution; attempt a bounded repair or use the defined fallback. | Coercing ambiguous text into tool arguments. |
| Rate limit or capacity pressure | Apply backpressure, queue within the task deadline, or degrade to a supported path. | Launching parallel retries that increase load. |
| Repeated downstream failure | Open a circuit breaker, stop new calls, and direct work to fallback or escalation. | Allowing every task to rediscover the same outage. |
| Tool response is missing after a side-effecting call | Treat the outcome as unknown and reconcile by idempotency key or downstream state. | Assuming timeout means failure and retrying blindly. |
| Evidence is missing or contradictory | Abstain, request the missing information, or escalate with the evidence gap attached. | Using eloquence as a substitute for grounding. |
| Partial multi-step completion | Record completed steps, block dependent actions, and run an approved recovery or compensation path. | Reporting overall success because one tool returned successfully. |
| Budget is exhausted | Move to a defined terminal state with the work completed and remaining gap recorded. | Letting the planner extend its own limits. |
Move safety checks in front of the action
A post-hoc alert cannot reverse every side effect. Put policy enforcement between the proposal and the tool call. Redact unnecessary personal information before it enters model context or telemetry. Maintain allow and deny rules for tools and data. Give each connector the least privilege required for its workflow.
Scope privilege to the action, not to the impressive breadth of the agent. A drafting workflow does not need permission to send. A reporting workflow does not need permission to edit the source system. A specialist that reads billing data does not automatically need the ability to issue a refund.
Sensitive or irreversible operations need a real approval boundary. The reviewer should see the exact target, proposed payload, supporting evidence, policy checks, and current downstream state. Approval should authorize that specific action, not grant the agent a reusable blank cheque. If the system cannot establish what will change, it should not present the action as ready for approval.
Encode these rules as policy rather than scattering them across prompts. Prompts can explain what the agent should propose. The enforcement layer decides what the product will permit.
Make every release observable, evaluable, and reversible
A chat transcript is not enough to operate an agent system. It shows the final conversation but can hide the retrieval choice, routing decision, prompt version, tool arguments, retries, policy checks, and partial state changes that produced it. You need lineage across the whole task.
Trace the decision chain, not just the final answer
Create one trace for the user task and a span for every material decision or operation. Capture enough structured metadata to reconstruct the path:
- Workflow, model, prompt, schema, policy, and tool versions.
- The selected route or plan, including rejected or revised steps where they affected execution.
- Retrieved evidence identifiers and the step that consumed them.
- Tool name, sanitized arguments, response status, duration, retry state, and idempotency key.
- Validator results, policy decisions, approvals, and circuit-breaker state.
- Token usage, elapsed time, and cost across the full chain and its spans.
- Final disposition: autonomous completion, fallback, escalation, contained failure, or incorrect completion.
- User correction, human override, or recovery action when one occurs.
Apply the same privacy rules to telemetry that you apply to model context. An observability system should help diagnose sensitive workflows without becoming an uncontrolled copy of their raw data.
The dashboard should connect technical behavior to product outcomes. Track task success by workflow and route, correct escalation, incorrect completion, p50 and p95 latency, tool failure rates, cost per completed task, and user-level satisfaction or correction signals. Break the aggregate down far enough to expose a weak specialist or connector. A healthy overall average can conceal a failing path with low traffic.
Each metric should answer a decision. Task success tells you whether the workflow produced its intended outcome. p95 latency exposes the slow tail users experience. Tool failure rate separates connector problems from model behavior. Cost per completed task prevents cheap failed attempts from looking efficient. Corrections and satisfaction signals catch results that passed a machine validator but did not solve the user’s problem.
Turn every important failure into an eval case
Build a golden dataset around the task contract. Include ordinary successful cases, ambiguous requests, missing evidence, conflicting evidence, tool failures, permission boundaries, and high-consequence edge cases. Score the dimensions separately: routing, retrieval, plan validity, tool selection, argument correctness, policy compliance, final outcome, and escalation quality.
An LLM judge can increase evaluation coverage, but it should not be treated as an unquestioned oracle. Calibrate its rubric and agreement against human ratings, especially for subjective quality and risk-sensitive decisions. Preserve the failing trace and expected behavior so a production defect becomes a permanent regression test rather than a one-time prompt patch.
Run evaluations by risk, not only by traffic. A rare unauthorized action deserves more scrutiny than a common cosmetic wording issue. This is why a single blended score is a weak release gate: it allows abundant easy cases to hide a small set of unacceptable failures.
Use a release ladder with a fast stop mechanism
Eval-driven development, automated checks, feature flags, shadow traffic, and canary releases let you learn without exposing every user to the first version of a change. A disciplined promotion path is:
- Continuous integration: Lint prompts, validate schemas and tool signatures, check policies, and simulate critical paths.
- Offline evaluation: Run the versioned golden set and compare each rubric dimension, not only the aggregate score.
- Shadow execution: Observe proposed routes, plans, and tool calls with side effects suppressed.
- Canary exposure: Enable the change for a constrained workflow or segment behind a feature flag.
- Measured expansion: Increase exposure only while outcome, safety, latency, tool reliability, and cost remain inside the targets defined by the task contract.
- Rollback or containment: Disable the affected route, tool, or version when a guardrail is breached, while preserving traces needed for diagnosis.
Run an A/B test only after both variants satisfy the non-negotiable reliability and safety gates. Plan the minimum detectable effect before interpreting the result. Otherwise, normal variation can turn an inconclusive experiment into a confident product decision.
A weekly eval review creates a practical operating rhythm. Add new failure cases, inspect regressions by component, compare automated judges with human ratings, assign owners to unresolved risks, and decide whether exposure should expand, hold, or contract. Keep prompt, model, retrieval, policy, and tool changes versioned so the team can identify what moved.
Agent operations also need ordinary production discipline: an on-call owner, a feature-flag kill path, runbooks for known failure modes, and incident reviews that distinguish the initiating error from the control that failed to contain it. DORA metrics and deployment frequency can show how effectively the team ships and recovers, but they do not tell you whether the agent completed the user’s task correctly. Keep delivery health and agent outcome quality visible side by side.
Key takeaways for your next agent release
- Define success, permitted evidence, side effects, abstention, escalation, and budgets before choosing an orchestration topology.
- Use retrieval-first for knowledge uncertainty, router-specialist for capability selection, and planner-executor only for genuinely variable multi-step work.
- Let models propose decisions while deterministic code validates state transitions, permissions, policies, and tool arguments.
- Treat a timed-out side effect as an unknown outcome. Reconcile through an idempotency key or downstream state before any retry.
- Trace retrieval, routing, planning, validation, tools, and final disposition under one task lineage.
- Promote changes through evals, shadow execution, canaries, and feature flags, with explicit rollback conditions.
Choose one valuable workflow whose actions can remain reversible. Write its task contract, instrument its full trace, add a safe abstention path, and place the release behind a flag. If you cannot explain what happens when evidence is missing, a tool times out, or a step partially succeeds, keep the scope narrow until you can.
References






