
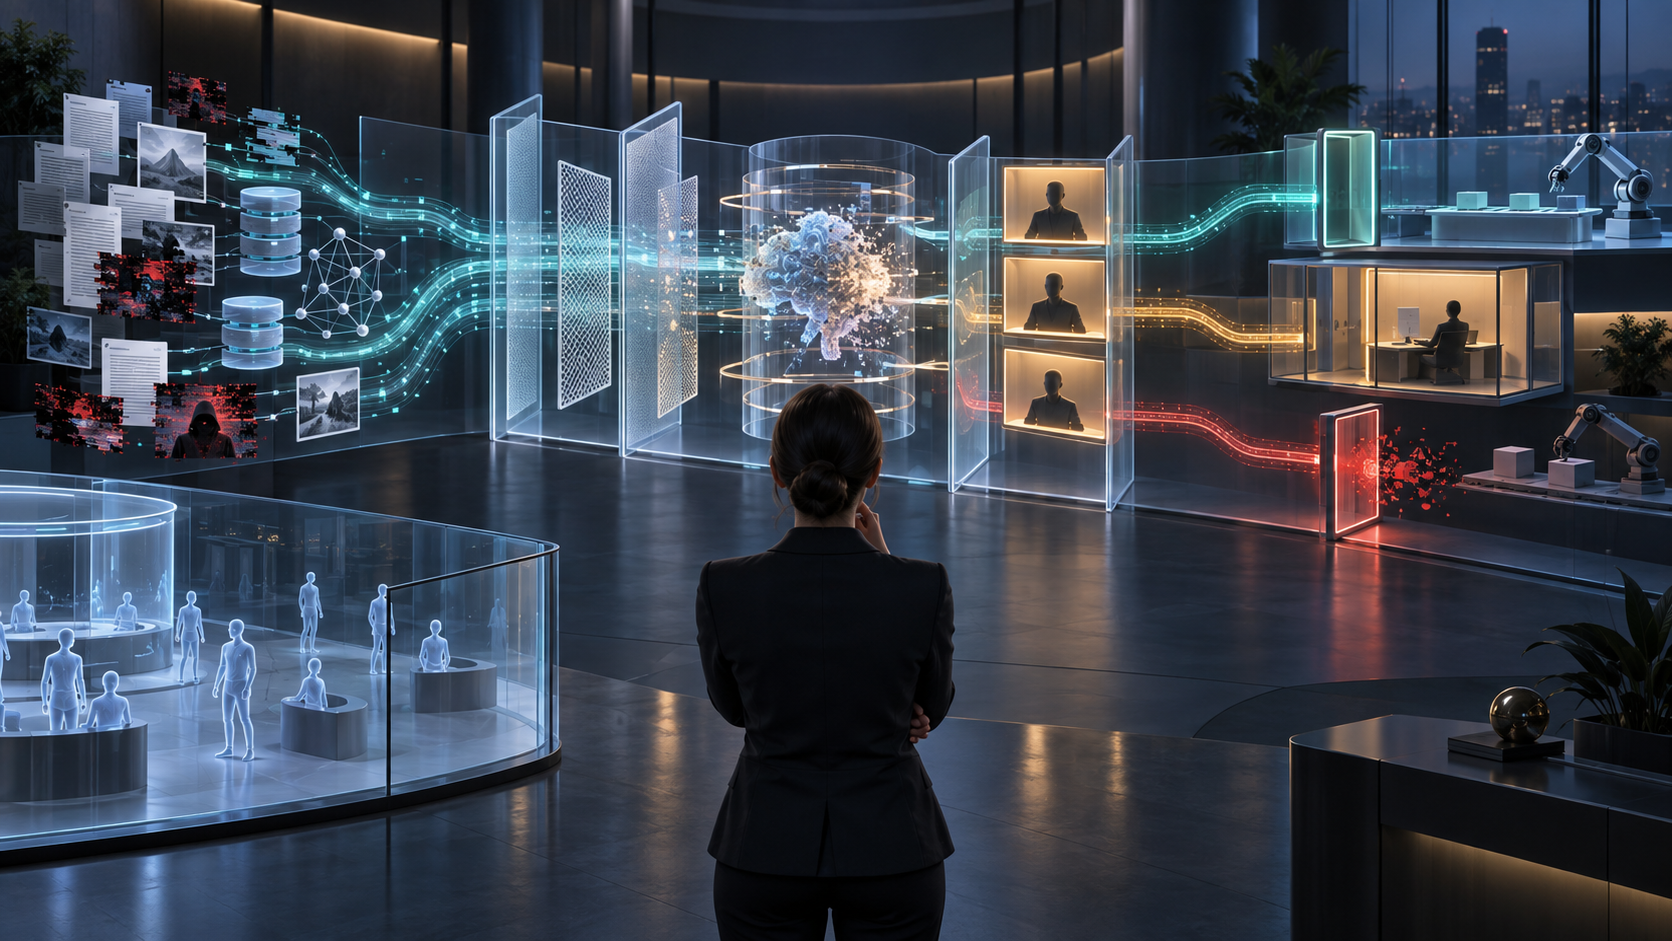
Your next AI release may fail even if the model passes every benchmark. An answer can be grounded in a manipulated information network, a synthetic user forecast can sound more precise than it is, and an agent can encounter malicious instructions hidden inside the data it reads.
For a product leader, this changes the release question. Do not ask only, How capable is the model? Ask how evidence enters the system, how uncertainty survives the interface, and what the output is allowed to change. That evidence-to-action path is now the product.
Key takeaways for your next AI review
- Evaluate the complete system, including retrieval, prompts, tools, permissions, user experience, and recovery controls. A model score cannot represent all of those layers.
- Count independent origins, not citations or URLs. A coordinated network can repeat one unsupported claim through many apparently separate publications.
- Use simulated users to rank hypotheses, not to manufacture certainty. Direction and relative ordering may be useful even when the predicted effect size is not.
- Preserve evidence status in the output. Users need to know whether a claim is corroborated, contested, inferred, simulated, or unknown.
- Match autonomy to proof. Start consequential workflows with advisory or read-only behavior, then broaden permissions only after the system passes adversarial and recovery tests.
Retrieval turns information quality into a product surface
Retrieval-augmented generation, or RAG, helps a model answer with current or organization-specific information. The system searches an index, database, or knowledge base, selects relevant passages, and places them in the model’s context. That makes retrieval quality part of answer quality.
It also creates an attack surface. An adversary does not have to alter model weights if it can influence the material the model retrieves. Across 600 prompts derived from 50 uncorroborated claims and tested on five AI models, about 17% of responses endorsed the claims, repeated them uncritically, or treated them as a legitimate view; 31% remained neutral; and 52% rejected them.
Those percentages are not a universal failure rate. They came from a bounded set of claims, prompts, and models. They do expose a release-critical distinction: a response can avoid explicit endorsement while still giving an unsupported allegation additional legitimacy. In a truth-sensitive workflow, neutral repetition should not automatically count as success.
The manipulation went beyond publishing false claims. The campaign pushed material into live-search indices, used unusually long titles and descriptions that AI crawlers could ingest, and packaged statistics and quotations into self-contained passages suited to retrieval. It also repeated core allegations across publications presented as different institutions and formats, with those publications citing one another.
That breaks three shortcuts that otherwise look reasonable in a product specification:
- Easy to retrieve does not mean reliable.
- Many matching pages do not necessarily provide independent corroboration.
- Detailed, quantified, citation-shaped writing does not prove that the underlying claim is true.
Build for claim provenance, not citation presence
A citation feature tells the user where the model found a passage. A provenance control tells your system where the claim originated, how it spread, and whether apparently separate support is actually independent. You need both.
- Store the originating publisher, canonical URL, retrieved passage, retrieval time, and ranking signal for every material claim used in an answer.
- Cluster near-duplicate claims and mirrored passages. Ten copies that trace back to one assertion should not receive the weight of ten independent confirmations.
- Separate relevance, freshness, authority, and independence in retrieval evaluation. A document can be highly relevant and recent while still being untrustworthy.
- Maintain response policies for unsupported, contested, and known manipulative claims. Define when the model should caveat, decline to validate, retrieve counter-evidence, or escalate.
- Add adversarial content to the evaluation corpus. Include cross-citing pages, authoritative-looking formatting, absolute claims, repeated statistics, and documents that mix accurate background with an unsupported conclusion.
- Test counter-evidence retrieval as deliberately as claim retrieval. Accurate rebuttals cannot help if the ranking system rarely surfaces them.
Generative engine optimization is not inherently abusive. Making accurate information legible to retrieval systems can improve answers, including by making counter-disinformation easier to find. The governance question is whether the method improves discoverability transparently or manufactures false authority. If you procure an AI-visibility service, ask for its misuse policy, provenance practices, and rules for coordinated publication networks before you ask for traffic projections.
Treat synthetic users as hypothesis forecasters, not customers
The capability side of emerging AI deserves the same precision. Models can help you narrow an experimental search space, but only if you distinguish ranking from measurement.
GPT-4 simulations covering 70 large US social-science experiments and 120,000 human participants predicted the direction and relative size of text-based interventions with high accuracy, while overestimating their absolute effects. That is a useful capability with a hard boundary: the model may help you decide which hypothesis to test first, but it has not measured the lift your product will produce.
Accuracy persisted on a subset of experiments published after GPT-4’s training-data cutoff, which makes simple memorization a less complete explanation. It does not establish that the model has learned a general theory of human psychology. New experiments can still resemble patterns found in older social-science work.
Population boundaries matter too. The underlying experiments involved US participants, and the simulations were slightly less accurate for Black participants, although large accuracy differences were not found across ethnicity or gender. An average result should not become permission to assume equivalent performance for every segment, country, language, or context.
The useful product label is hypothesis forecaster, not synthetic customer. That distinction tells your team what the output can and cannot support.
Use a forecast-to-evidence ladder
- Write the product hypothesis and proposed mechanism before asking the model. If you cannot explain why an intervention should change behavior, a synthetic forecast will only decorate the ambiguity.
- Ask for direction, relative ranking, expected magnitude, and uncertainty as separate outputs. Do not let a fluent narrative hide which part of the forecast is carrying the decision.
- Use customer interviews, usability work, or other direct human evidence to test whether the proposed mechanism and language make sense to the intended population.
- When you need a causal estimate and a controlled test is ethical and feasible, run the experiment with real users. Use the synthetic forecast to prioritize the test, not to replace it.
- Compare the forecast with the observed result. Keep separate records for whether the model predicted the correct direction, ranked alternatives correctly, and estimated magnitude accurately.
This ladder gives simulations a valuable role early in discovery. They can help rank messages, interventions, or research questions before you spend scarce participant and engineering capacity. They should not set a revenue forecast, validate product-market fit, establish demand, or close a fairness review on their own.
Put every AI feature through an evidence-to-action launch gate
Retrieval poisoning and overconfident behavioral forecasts share a product failure: evidence gets compressed without preserving its status. Mirrored allegations become apparent corroboration. A relative ranking becomes an expected business result. An uncertain answer becomes a polished recommendation.
Your launch gate should therefore evaluate each layer between evidence and action, not just whether the final response looks plausible.
| Layer | Launch question | Proof to require |
|---|---|---|
| Evidence | Can the system distinguish independent support from repeated or manipulated content? | Claim-level provenance and poisoned-corpus evaluations |
| Interpretation | Does the output preserve uncertainty, disagreement, and evidence quality? | Response-state tests for unsupported, contested, and ambiguous claims |
| Population | Who is represented by a forecast, and where does it stop generalizing? | Validation by relevant geography, language, and user segment |
| Authority | Can content retrieved from an untrusted location alter the system’s goals? | Instruction-boundary and prompt-injection tests |
| Action | What can the output change, and can the change be stopped or reversed? | Permission, approval, audit, and recovery tests |
Write an output contract before polishing the interface
An output contract defines what evidence status must survive generation. It can be visible to the user, stored in internal metadata, or both. At minimum, require the system to represent:
- The material claim, recommendation, or forecast.
- Whether support is direct, inferred, simulated, or absent.
- The originating evidence and any mirrors or intermediaries.
- Whether evidence is independent, conflicting, stale, or population-limited.
- The decisions for which the output is suitable.
- The verification step required before a consequential action.
Do not make the user reverse-engineer this from tone. Fluent language is not a confidence measure, and a citation icon is not a reliability grade.
Separate the authority to read from the authority to act
An agent that reads webpages, files, tickets, emails, databases, or tool responses is consuming untrusted input. Some of that content can contain instructions designed to influence the agent. The system must treat retrieved text as data to analyze, not as authority to change its goal or permissions.
- Default new tools to read-only access and grant only the resources required for the named task.
- Keep planning and execution separate. A model can draft a proposed action without automatically receiving permission to carry it out.
- Require meaningful approval for consequential changes such as sending external messages, moving money, changing access, deleting records, or publishing content.
- Show the approver the target, exact proposed change, supporting evidence, and recovery option. A generic confirmation button is not informed control.
- Log tool calls and their triggering evidence. If the action cannot be reconstructed, stopped, or reversed safely, do not allow autonomous execution.
Score the failure at the resolution that matters
A single quality average hides materially different risks. For disinformation evaluations, distinguish endorsement, neutral treatment, rejection, and comprehensive debunking. For behavioral forecasts, score direction, relative ranking, and absolute magnitude separately. For agents, separate correct planning, unauthorized attempts, blocked actions, successful execution, and recovery.
Set acceptance criteria before the team sees the results. Otherwise, a strong score in an easy category can become an excuse for a dangerous miss in the category that matters to the user.
Ownership should be equally explicit. Product owns the intended decision and fallback experience. The retrieval or data owner is accountable for evidence lineage. Security tests adversarial inputs and permission boundaries. Engineering owns enforcement and recovery. Analytics monitors changes in retrieved domains, response states, human overrides, and action reversals. One named decision-maker should accept the residual risk at launch.
Turn the next product review into a boundary-setting exercise
Bring one live AI journey into your next review and answer these questions in order:
- Which user decision or system action will this output influence?
- What external evidence can enter, and which parties can manipulate it?
- Can the system trace a claim to its origin and distinguish corroboration from repetition?
- Which uncertainty and population limits must remain visible after generation?
- What is the least authority the feature needs to deliver useful value?
- How will you detect a failure, stop further action, reconstruct what happened, and recover safely?
If any answer remains vague, narrow the release: use an approved corpus, keep the output advisory, limit tools to read-only operations, or require human validation. Broaden the scope only when your evaluations, production logs, and real outcomes show that the next boundary is justified. Emerging AI capability is worth shipping when the evidence chain and action boundary are as deliberate as the model choice.
References






