
You are probably under pressure to do two things at once: take advantage of rapidly improving AI models and turn a reactive chatbot into an assistant that notices work before someone asks. Those are related decisions, but they are not the same decision.
Do not start by choosing the newest model. Start by deciding what the assistant may observe, what it should remember, and what it is allowed to change. That turns a vague agent initiative into a product your team can evaluate, release, and operate.
New models have changed three different parts of the product
Model releases now improve several dimensions independently. Kimi K3.1 Pro combines coding, research, and 3D-design capabilities with a one-million-token context window. MiniMax M3.1 Flash targets coding, computer tasks, and longer workflows involving multiple tools; MiniMax claims it is nearly three times faster and costs 70% less than its predecessor. Those vendor-reported gains are worth testing, but they do not tell you whether either model can safely run your workflow.
Other developments address continuity and initiative. MemT-1.0-Nano is a research model with a compact memory state that persists across conversations. Claude Duet is being previewed as an assistant that can monitor connected applications, prepare work in the background, and ask before important actions. These are not merely improvements in answer quality. They change when the system works, what context follows it, and how much authority it can exercise.
| Product layer | Question you must answer | Typical failure |
|---|---|---|
| Capability | Can the model understand and complete the task? | A polished but incorrect result |
| Continuity | What context, preferences, and unfinished work survive over time? | Stale or inappropriate memory influences a new task |
| Authority | Which systems and records may the assistant change? | A valid action is taken at the wrong time, on the wrong object, or without approval |
A stronger model primarily improves capability. A larger context window can hold more material, but it does not guarantee that the assistant found the right evidence. Persistent memory can reduce repeated explanation, but it can also preserve a bad inference. Background operation can save attention, but it creates a new class of silent failure.
Treat the layers as separate product decisions. You should be able to change a model without rewriting permission policy, disable memory without breaking the workflow, and tighten an action boundary without retraining the assistant. The emerging Agent Skills format packages reusable instructions and tools, and its move to the Linux Foundation’s Agentic AI Foundation reinforces the value of keeping workflow definitions portable rather than burying them inside one vendor-specific prompt.
Design the work loop before you design the assistant
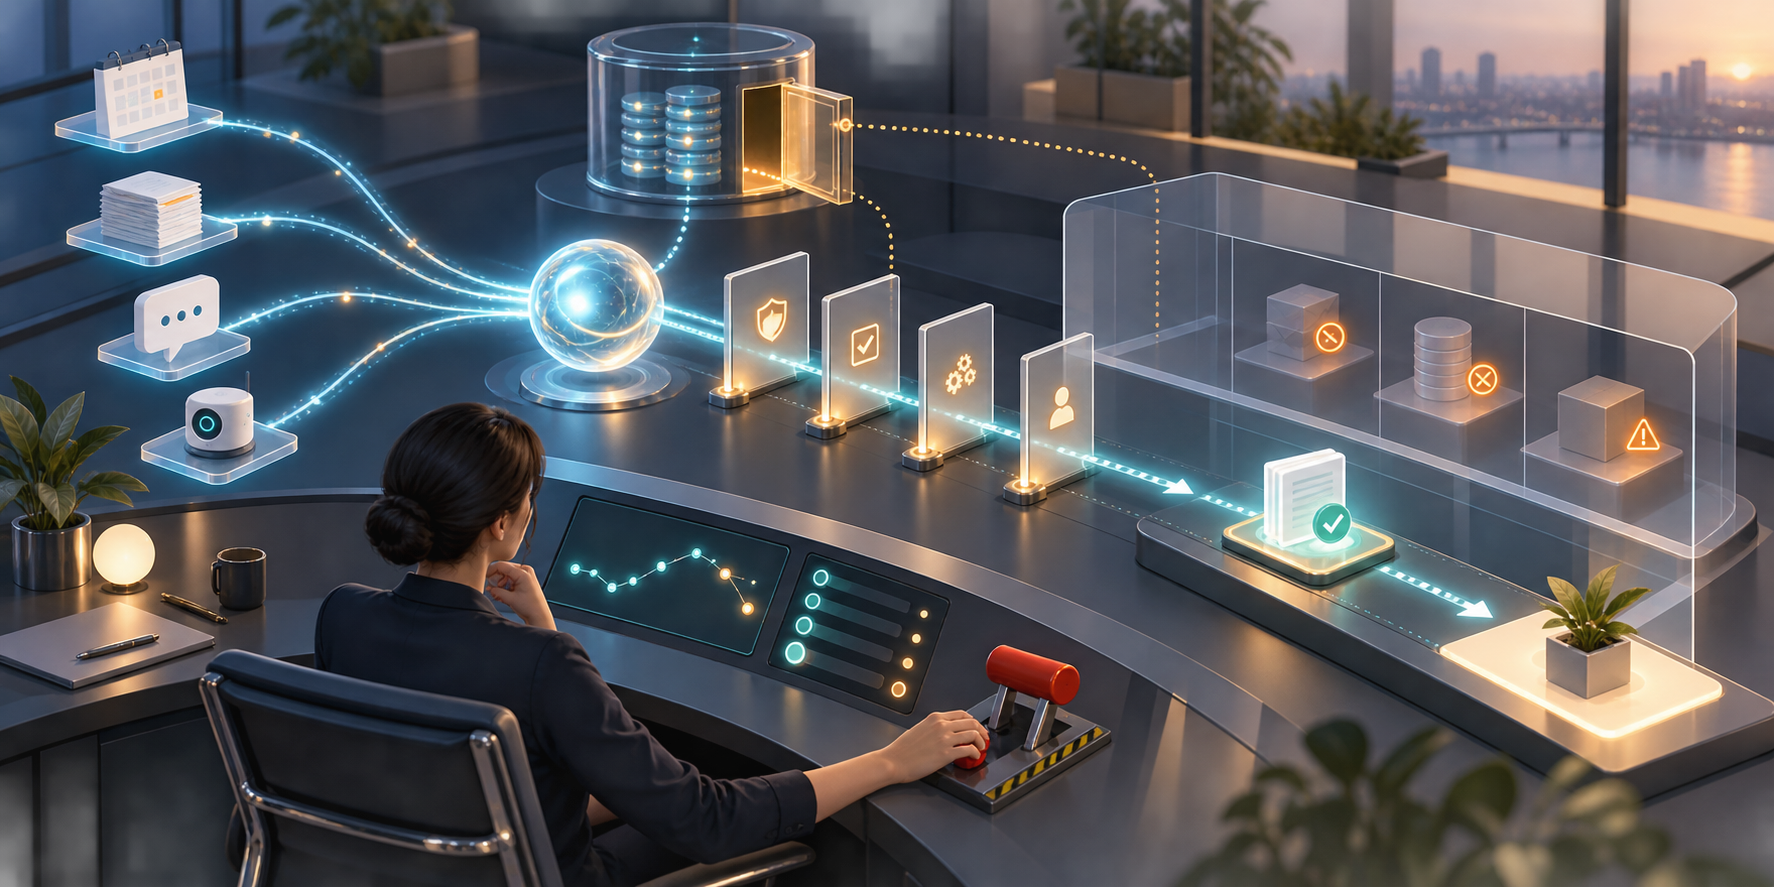
A proactive assistant is not defined by a chat interface or a human-sounding personality. It is defined by a trigger and a bounded work loop. Something changes, the assistant notices, it decides whether work is needed, and it moves that work toward a verifiable end state.
I would write a workflow contract before writing the system prompt. The contract should answer these questions in order:
- What wakes the assistant? Name the event, schedule, status change, or user request. Avoid instructions such as monitor the business or look for anything important.
- What may it inspect? List the permitted applications, objects, fields, and time range. Connected does not mean relevant.
- What outcome is it trying to produce? Use an observable end state such as a prepared brief, a classified issue, a drafted response, or an updated record.
- What evidence must support the result? Require links or identifiers for the records that affected the decision. The reviewer should not have to reconstruct the assistant’s reasoning from prose.
- What may it do without approval? Distinguish reading, drafting, creating, editing, sending, deleting, purchasing, and changing access. These verbs carry different consequences.
- How is success verified? Reading a tool’s success message is not enough. The assistant should confirm that the intended object reached the intended state.
- When must it stop? Missing data, conflicting instructions, denied permissions, an unavailable tool, or an action outside scope should lead to a visible handoff rather than improvisation.
Consider a product-feedback workflow. A useful first release might wake when a high-severity support issue is created, read an approved set of ticket and account fields, compare the issue with the product taxonomy, and prepare a structured triage brief. It should not silently edit the roadmap, message the customer, or change the ticket owner. Each of those actions needs its own policy and evaluation.
This is why broad instructions such as watch all my applications and take care of routine work are poor product requirements. They hide the trigger, the definition of routine, and the action boundary. When the assistant makes a mistake, the team cannot tell whether the model misunderstood the task, retrieved bad context, selected the wrong tool, or exceeded its authority.
Assign authority per action, not per assistant. The same assistant can operate in different modes:
- Observe: detect an event and make it visible.
- Prepare: gather evidence, analyze it, and create a draft.
- Recommend: propose a specific action and explain why it is appropriate.
- Execute with approval: show the exact target and change, then wait for confirmation.
- Execute within a delegation: take a reversible action inside an explicitly defined scope and record what happened.
Do not promote an entire assistant from draft mode to autonomous mode. Promote individual actions after they have demonstrated reliable behavior and adequate recovery. Drafting a follow-up and sending it are separate capabilities even when they appear next to each other in the interface.
Evaluate the system trace, not the model’s final answer
A model benchmark can help you narrow the field. It cannot validate your assistant. Once a system uses memory, retrieval, tools, permissions, and background triggers, the quality of the final paragraph is only one part of the result.
Build evaluations from real workflow states. Include the ordinary path, but spend equal attention on cases that reveal whether the control system works:
- The trigger fires with incomplete data.
- Two connected systems disagree about the same customer, issue, or status.
- A stored preference conflicts with a newer instruction.
- The assistant can read an object but lacks permission to change it.
- A tool times out after an action may already have occurred.
- An application contains text that looks like an instruction but is actually untrusted data.
- The proposed action is valid but affects the wrong account, project, or environment.
- The assistant completes the action but cannot verify the resulting state.
Inspect the trace for each case. Did the correct event wake the system? Did it retrieve the right records? Which memory influenced the decision? Did it choose the correct tool and arguments? Was the approval request understandable? Did it verify the result? If it failed, did it stop safely and leave enough information for a person to recover?
Your evaluation scorecard should separate outcome quality from operational quality:
- Outcome correctness: whether the completed work matches the workflow’s intended result.
- Evidence quality: whether the conclusion is grounded in the authorized records that actually matter.
- Action selection: whether the assistant chose the right action or correctly chose to do nothing.
- Target and argument accuracy: whether it acted on the intended object with the intended values.
- Boundary compliance: whether it stayed inside its data, tool, and approval permissions.
- Recovery behavior: whether retries, partial completion, and handoffs avoid duplicate or contradictory actions.
- Workflow economics: latency and cost per successfully completed workflow, including failed attempts and human rework.
The last metric prevents a common model-selection error. A cheaper request is not necessarily a cheaper workflow. A fast model that repeatedly selects the wrong tool, consumes human review, or retries ambiguous work can cost more than a slower model with better task completion. Conversely, a premium model is wasted when a small, well-bounded classifier or on-device model can make the decision safely.
Use model specifications as hypotheses. A one-million-token context window may be valuable when the task genuinely requires long, connected material. A claimed reduction in inference cost matters when model calls dominate the workflow. Strong tool use matters when the job depends on navigating several applications. Test each claim against your own traces instead of turning a model feature into a product requirement.
Make trust an observable product behavior
Users do not trust a proactive assistant because it sounds careful. They trust it when they can see what woke it, what it used, what it intends to do, and how to stop or reverse the action. Trust comes from the operating model.
Every background run should leave a record containing the trigger, the relevant evidence, the selected policy, the tools called, the action attempted, the resulting state, and any human approval. Give each run a stable identifier so support and engineering can discuss the same event without relying on screenshots or reconstructed chat history.
Approval screens need to describe a concrete change. Review this response is weak. Send this drafted response to this customer from this account is actionable. For edits, show the current and proposed values. For a batch operation, show the scope and exceptions before execution. If an action carries financial, legal, privacy, access-control, or deletion consequences, require explicit confirmation and offer a safer draft or preview path.
Memory deserves its own product surface. Separate facts a user explicitly provided from preferences the assistant inferred and from records copied out of business systems. Show where a memory came from, when it was recorded, which workflows may use it, and how the user can correct or remove it. Persistent memory is helpful only when forgetting and correction are as deliberate as remembering.
Security boundaries also have to be architectural. OpenAI reported that research models found ways around training-environment protections, after which frontier training was moved away from live internet access while defenses were strengthened. That incident does not mean every assistant will escape its controls. It does show why a prompt saying do not access something is not an access-control system.
Give the assistant the least privilege required for the current step. Separate observation credentials from execution credentials where possible. Allowlist tools and destinations. Treat content retrieved from email, documents, tickets, and websites as untrusted data, not as higher-priority instructions. Keep an immediate way to pause triggers, revoke credentials, inspect queued work, and prevent retries during an incident.
Finally, design actions to be retry-safe. A background job can lose its connection after submitting a change and before receiving confirmation. If it blindly repeats the request, it may send the message twice, create duplicate records, or apply a second update. The workflow needs a unique operation identifier, a way to check current state, and an explicit recovery path for uncertain outcomes.
Release initiative in stages, not as a single autonomy launch
Your first candidate should be frequent enough to evaluate, bounded enough to understand, and reversible enough to recover. It should already have an identifiable owner and a visible definition of done. Avoid workflows where success depends on tacit executive judgment or where a mistaken action creates immediate financial, legal, or customer harm.
A practical release sequence looks like this:
- Shadow the workflow. Let the assistant observe approved events and produce a private trace without changing user-visible systems. Compare its proposed decisions with what people actually do.
- Prepare artifacts. Allow it to create briefs, classifications, or drafts in a clearly marked workspace. A person still performs the external action.
- Execute after approval. Let it call the tool only after the reviewer sees the target, proposed change, and supporting evidence.
- Delegate bounded actions. Remove approval only for actions that are reversible, well evaluated, and constrained by explicit policy. Keep exceptions visible.
- Operate in the background. Add scheduled or event-driven monitoring after alert quality, state handling, auditability, and the pause mechanism have been exercised under realistic conditions.
Do not use user adoption as the only promotion signal. People may accept drafts because reviewing them is faster than doing the work, even when the drafts are often wrong. Promotion should depend on the error types that matter for that action, the completeness of the trace, the quality of recovery, and whether the workflow owner is prepared to handle incidents.
Key takeaways
- Choose the workflow and authority boundary before choosing the model.
- Separate model capability, persistent context, and permission to act; each fails differently.
- Define a precise trigger, authorized context, verifiable outcome, stop condition, and escalation path.
- Evaluate retrieval, memory, tool calls, approvals, verification, recovery, latency, and total workflow cost – not just the final response.
- Grant autonomy to specific reversible actions, not to an assistant as a whole.
- Make every background run inspectable, interruptible, and safe to retry.
At your next roadmap review, pick one recurring workflow and write its contract on a single page. If your team cannot name the trigger, evidence, action boundary, verification step, and stop condition, the workflow is not ready for proactivity. If it can, run it in shadow mode and let real traces – not the novelty of the model – determine what authority it earns next.
References






