Your AI demo is persuasive. It answers quickly, uses the right tone, and handles the happy path. Then a domain expert asks one uncomfortable question: what happens when the answer looks right but should not be acted on?
That is the central design problem in customer-facing AI. The hard part is not generating an answer. It is deciding when an answer deserves trust, what action it may trigger, and who is accountable when the situation falls outside the product’s competence. Human expertise has to shape that system before launch, not inspect its mistakes afterward.
Fluent output is not a trustworthy outcome
Generative AI can make a weak decision look finished. The language may be polished, the interface may feel responsive, and the recommendation may sound specific. None of those qualities proves that the underlying judgment is sound.
This is the product version of AI slop: output that appears competent but has not been subjected to competent judgment. It emerges when the ability to produce outruns the ability to evaluate. In a customer-facing product, the consequence is more serious than generic content. The output can change a customer’s decision, create work downstream, or initiate an action that is difficult to reverse.
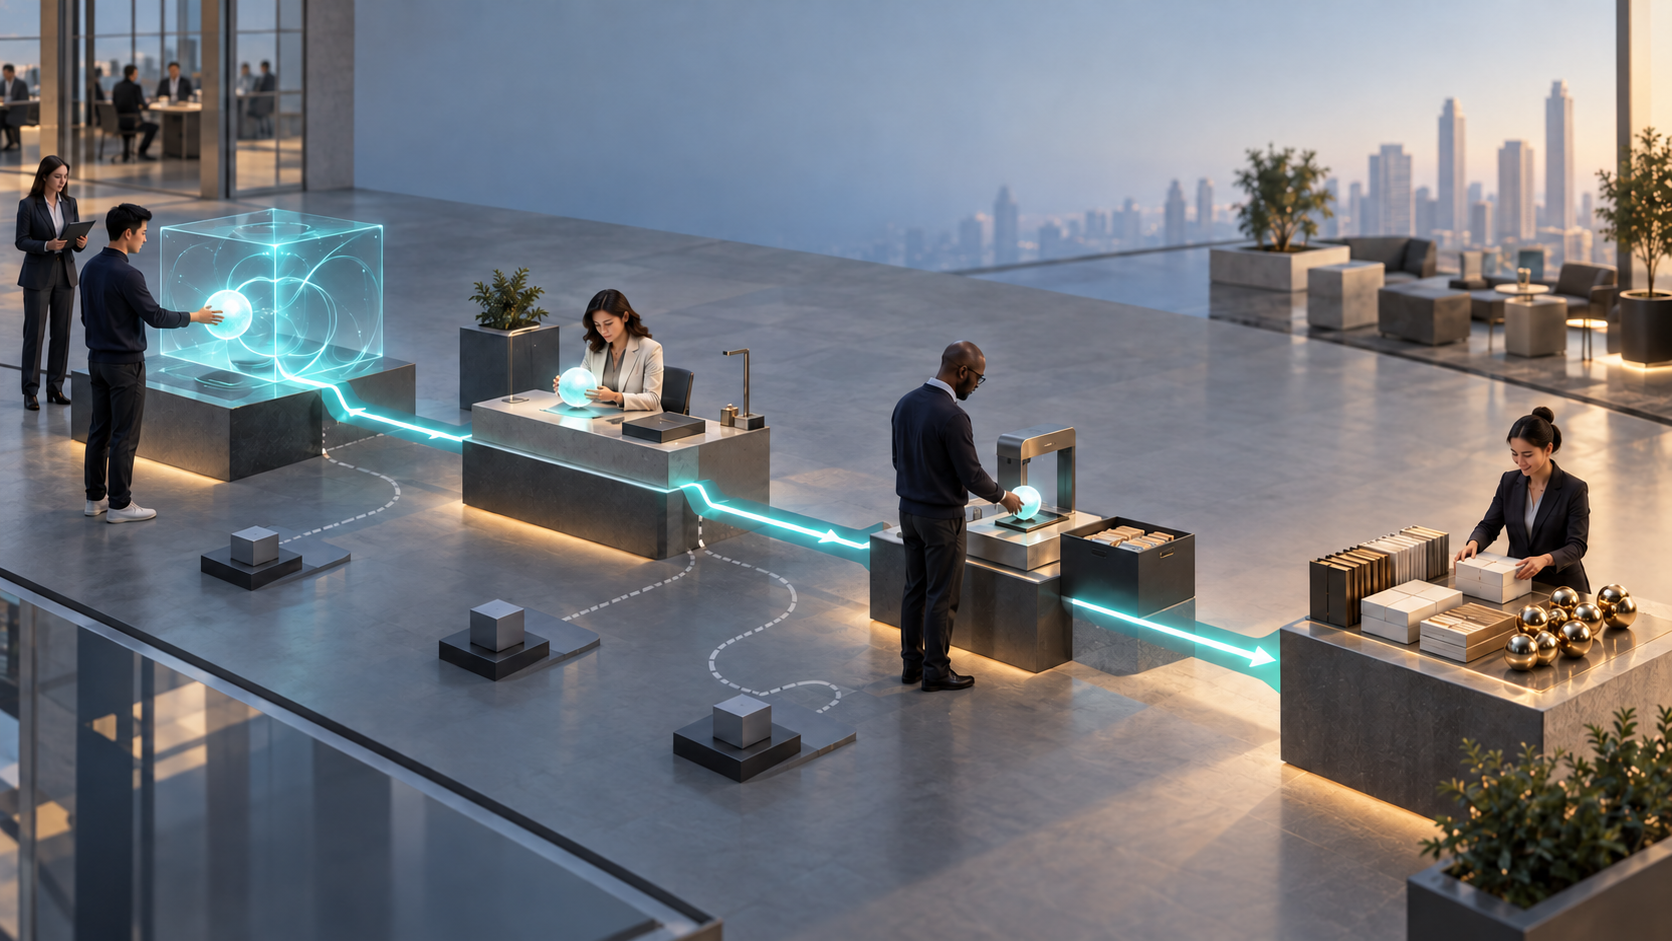
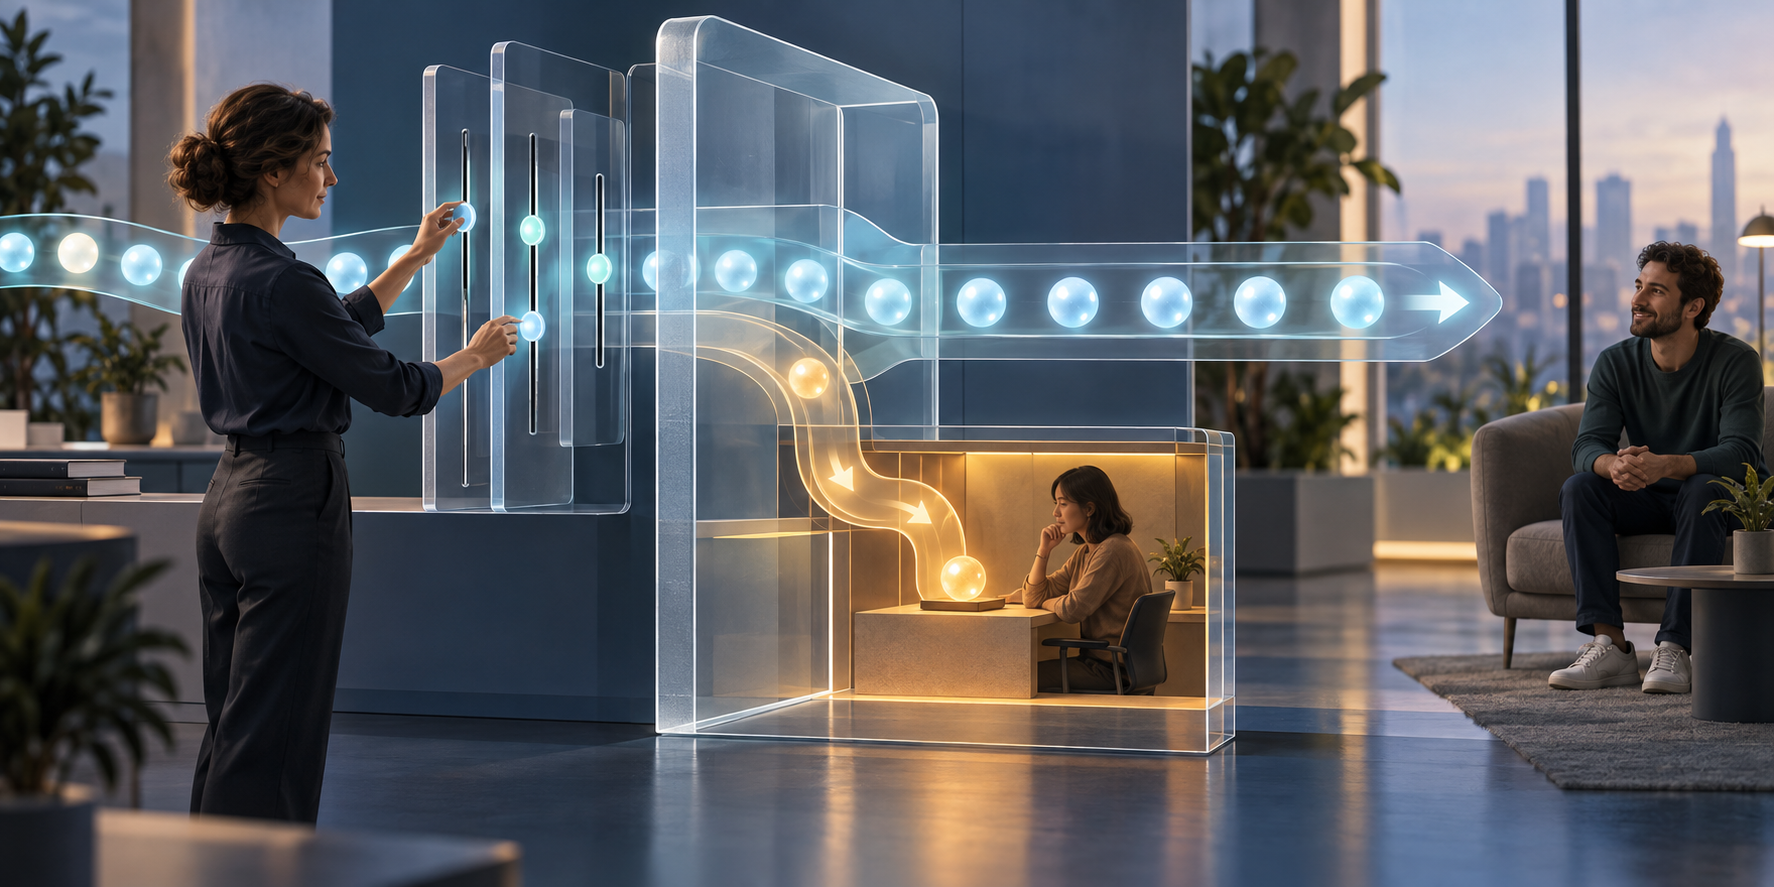
A product team can unintentionally amplify this problem. Good UX removes friction, and removing friction makes action easier. If the system is unreliable in an important scenario, a smooth interface does not neutralize the risk. It helps the unreliable answer travel faster.
Separate four questions that are often collapsed into one:
- Can the model produce an answer? This is a capability question.
- Is this answer correct enough for this task? This is a domain-quality question.
- Should the customer act on it without review? This is a consequence and decision-rights question.
- Did the interaction improve the intended outcome? This is a product and business question.
A successful prototype may answer only the first question. Shipping it requires credible answers to all four. Customer-facing AI design works when usability, trust, and business outcomes are treated as connected constraints, not as separate workstreams.
Before approving a feature, take its most persuasive sample output and ask: what knowledge would a qualified practitioner use to accept, edit, reject, or escalate this? If the team cannot name that knowledge, it has not yet defined quality. It has defined a demo.
Turn expert judgment into product requirements
Putting an expert in a review meeting is not the same as designing with expertise. The product cannot reliably apply knowledge that remains implicit in one person’s head.
The practical job is to convert expert judgment into observable rules, examples, tests, interface behavior, and escalation paths. That translation should happen during discovery. Waiting until acceptance testing usually produces vague feedback such as make it more accurate or the answer does not feel right. Neither instruction tells engineering what must change.
Build a judgment map for one customer task
Start with a narrow task, not the entire assistant. A judgment map should answer the following:
- Intended decision: What is the customer trying to decide or accomplish after seeing the output?
- Required evidence: What information must be present before the system may answer?
- Evidence priority: Which information wins when customer data, policy, prior conversation, and general model knowledge conflict?
- Disqualifiers: What missing, stale, contradictory, or out-of-scope information makes a definitive answer inappropriate?
- Quality boundary: What separates acceptable, needs-editing, and unacceptable output?
- Consequence: What happens if the customer follows a wrong answer?
- Recovery: Can the action be undone, and can the affected customer be made whole?
- Escalation trigger: What condition requires another person, workflow, or authority?
Do not ask an expert only for ideal answers. Ask for borderline cases, common mistakes, misleadingly plausible answers, and examples where the correct response is to stop. Those examples reveal the boundaries that polished happy-path demonstrations conceal.
For each example, ask the expert to label the decisive evidence. A rewritten answer tells you what the expert prefers. A labeled decision tells you why, which gives the team something it can encode in retrieval, prompting, policy, interface copy, or workflow logic.
Treat expert disagreement as product data
Experts will sometimes disagree. Do not hide that disagreement by averaging their labels or asking the most senior person to settle every case informally. Find the reason for the difference.
- If they rely on different facts, the product may be missing context.
- If they interpret the same policy differently, the policy may need clarification.
- If both answers are defensible, the product should preserve choice rather than manufacture certainty.
- If the right answer depends on customer circumstances, the interaction should collect those circumstances before recommending an action.
- If ownership is unclear, the product needs an explicit decision authority rather than another prompt revision.
This distinction matters because model tuning cannot resolve an organizational ambiguity. If the business has not decided what should happen, the AI cannot make that decision legitimate by expressing it confidently.
Place human checkpoints where consequences change
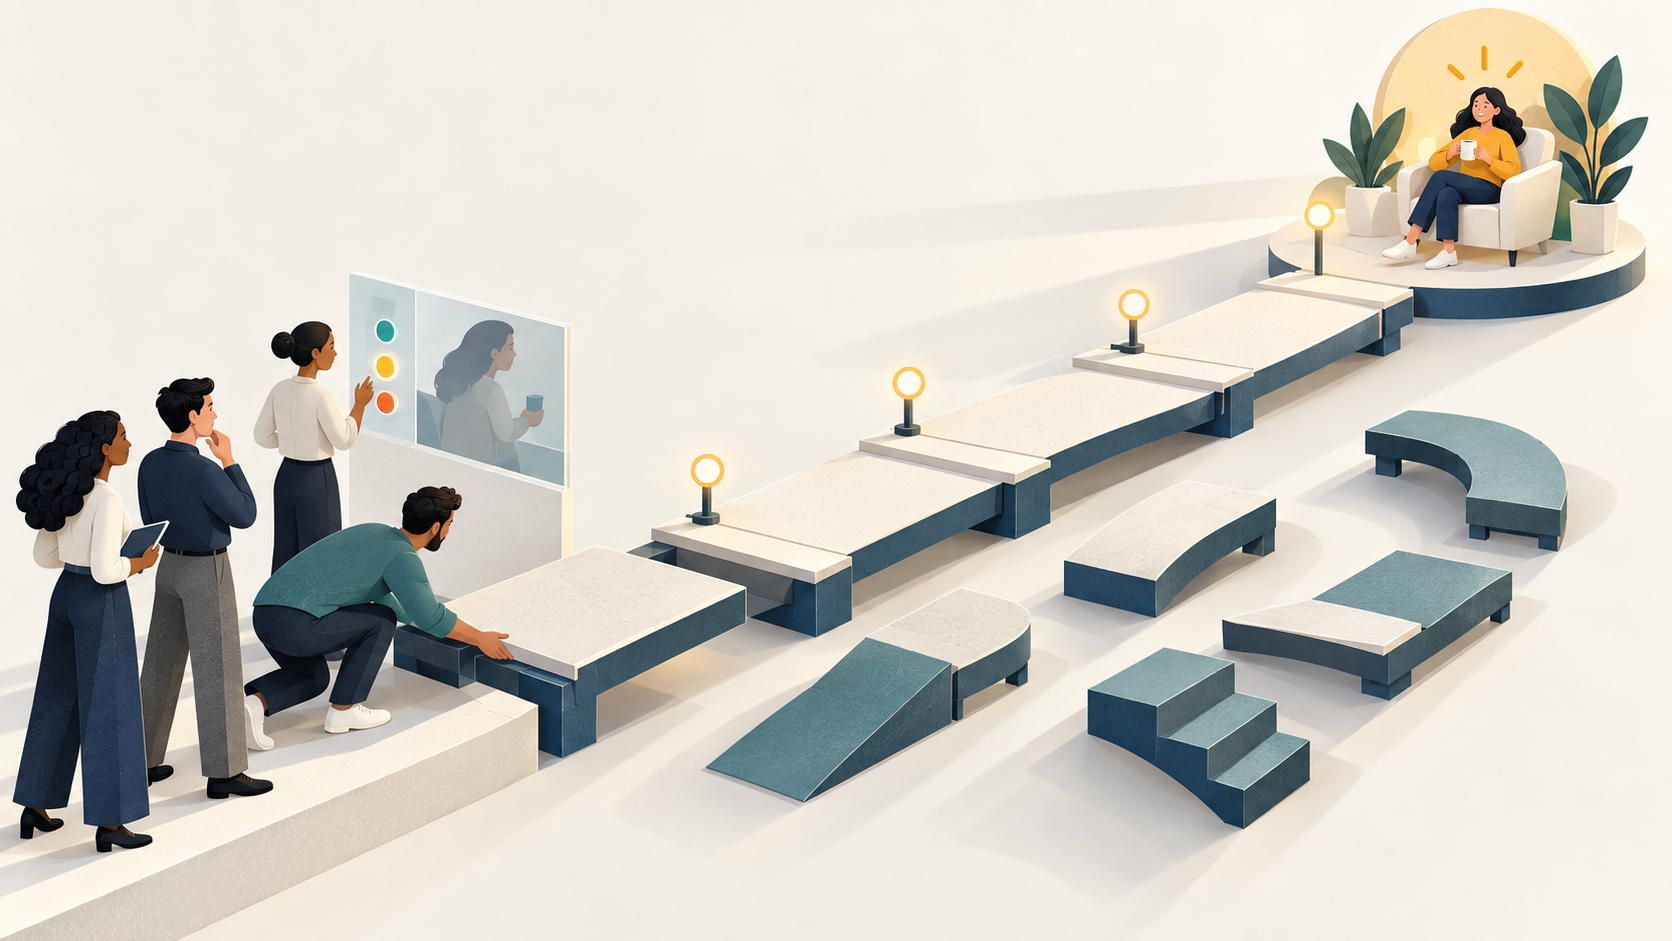
Human-in-the-loop is too broad to be a design specification. It could mean an employee approves every output, an expert audits samples after the fact, or a customer sees an edit button that almost nobody uses. The useful question is narrower: which decision belongs to the AI, which belongs to the customer, and which requires an accountable expert?
Classify the workflow by consequence and reversibility. Then assign decision rights explicitly.
| Situation | Appropriate AI role | Human decision right | Interface requirement |
|---|---|---|---|
| Low-consequence and easily reversible | Generate or complete the task within a defined boundary | An expert defines the boundary and audits behavior | Make editing, retrying, and correction easy |
| Meaningful but recoverable | Recommend an action and present the supporting information | The customer or responsible operator confirms the action | Show assumptions, material uncertainty, and what confirmation will do |
| Hard to reverse, costly, safety-sensitive, or subject to formal controls | Collect information, summarize, and prepare a draft | An authorized person approves or performs the action | State that review is required and preserve an audit trail appropriate to the workflow |
| Outside the product’s defined competence | Decline to decide and prepare a structured handoff | The relevant human owner takes over | Explain the boundary and carry context into the handoff |
The row should be determined by the potential consequence, not by how often the scenario occurs. A rare failure can still deserve a hard gate if recovery is difficult. Conversely, forcing approval on every low-consequence draft can create a rubber-stamp process in which people click through without adding judgment.
Use people in different positions for different purposes:
- In the loop: A person reviews a particular decision before a consequential action occurs.
- On the loop: An expert monitors patterns, audits samples, and investigates emerging failure modes without approving every routine output.
- Above the loop: An accountable owner defines policy, changes the system’s authority, and decides whether a class of decisions may be automated at all.
A good escalation is also a product experience, not a dead end. The handoff should include the customer’s request, relevant evidence, detected conflict or missing information, what the AI attempted, and the next decision required. Making the customer repeat the entire interaction transfers the cost of the system’s uncertainty back to the customer.
Do not treat a confidence display as a substitute for this design. Even a technically valid score does not tell the customer how costly an error would be or whether a human must approve the action. Communicate the operational meaning instead: what is known, what is missing, what the system can do, and what happens next.
Evaluate judgment, not just answer quality
Many AI evaluations stop at the generated response. Customer-facing quality depends on the whole decision path: what information was collected, what evidence was retrieved, how the output was framed, what the customer understood, what action followed, and whether the outcome held up.
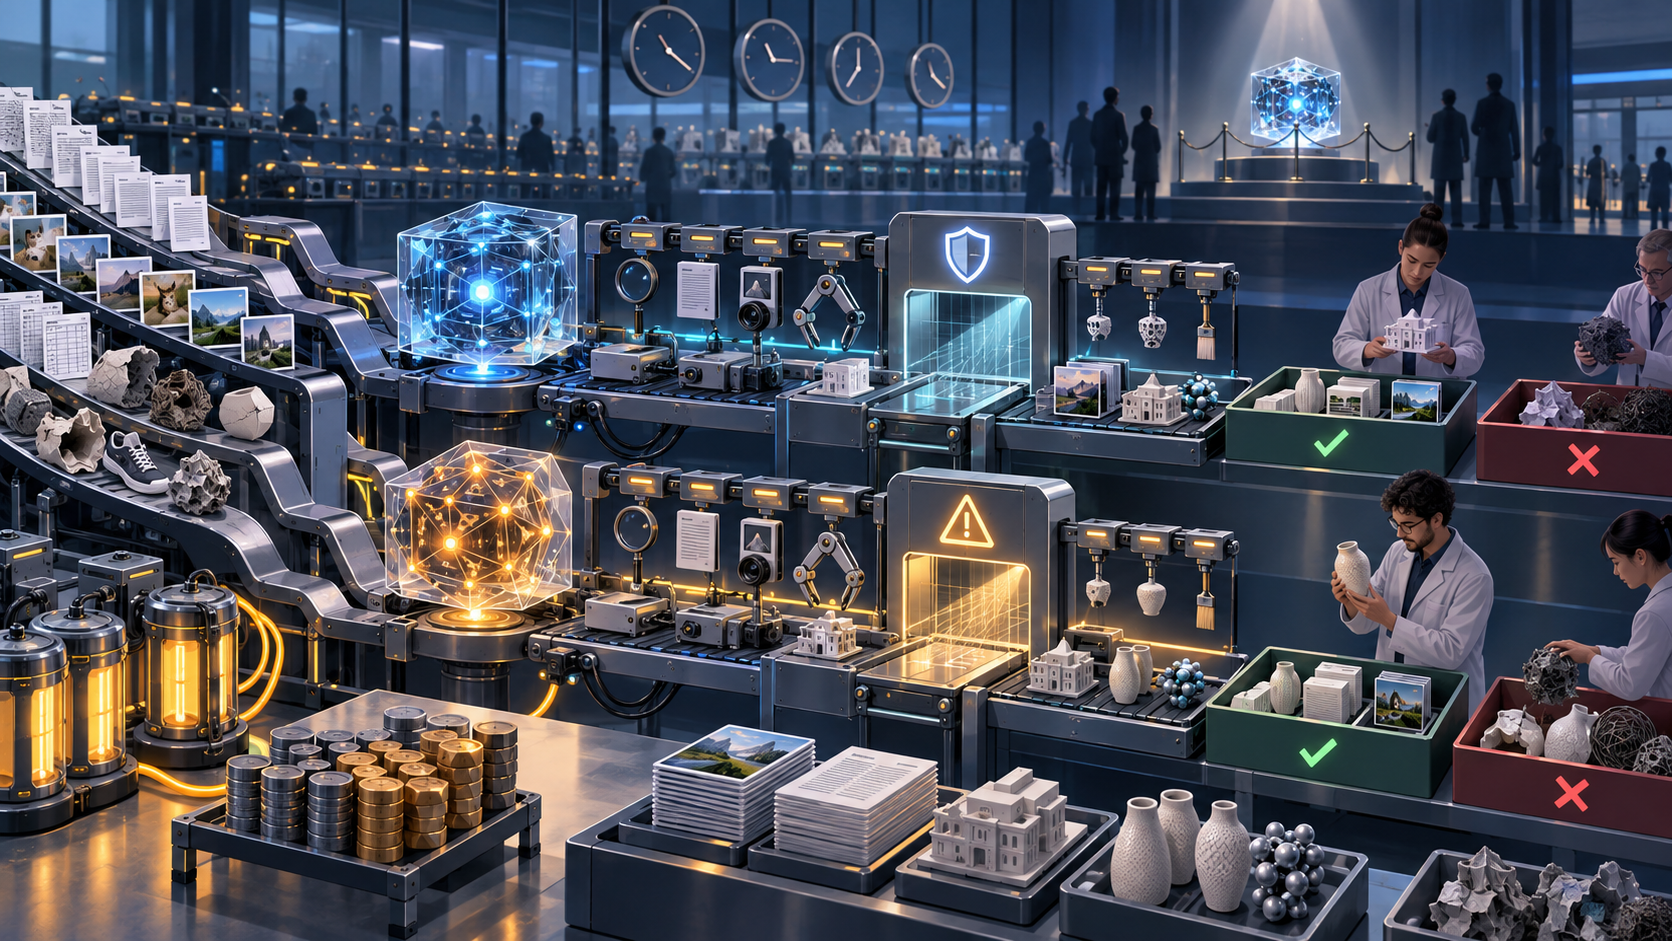
Build the evaluation set from the judgment map. Include routine cases, incomplete context, conflicting evidence, boundary cases, attempts to push the system beyond its role, and cases in which escalation is the correct result. A test set made only of questions the system should answer cannot verify whether it knows when not to answer.
Score distinct dimensions rather than hiding them inside one overall quality rating:
- Evidence use: Is the answer supported by the information the product is permitted to use?
- Decision fitness: Does the output help with the customer’s actual decision rather than merely discussing the topic?
- Boundary adherence: Does the system stay within its assigned role and authority?
- Uncertainty handling: Does it ask for necessary context, qualify a conditional answer, or escalate when appropriate?
- Consequence awareness: Does the workflow require confirmation or approval when the action warrants it?
- Recovery quality: When the system cannot proceed, does it preserve context and offer a useful next step?
- Customer comprehension: Can the customer tell whether the output is a draft, recommendation, confirmed fact, or completed action?
Keep critical failures separate from average performance. A strong score on routine responses should not cancel out a failure to stop in a consequential case. Define release gates around unacceptable behaviors, then use aggregate scores to improve performance within the safe boundary.
Product analytics need the same discipline. Acceptance is not proof of correctness. Customers may accept an answer because it is convenient, because they assume the system has checked it, or because checking takes more effort than continuing.
Pair interaction signals with outcome signals. Track edits and overrides, but also examine escalations, repeated contacts, reopened work, corrections, downstream rework, and whether the intended customer outcome was actually reached. If the team runs an A/B test, conversion or task completion should not be the sole success measure when one variant changes the risk of a wrong decision.
Expert review should focus on patterns, not just individual mistakes. A cluster of similar errors may point to a missing source, an ambiguous policy, an interface that invites the wrong assumption, or an authority boundary that is too broad. Each cause demands a different product change.
Build an operating loop that keeps expertise current
Human expertise is not a launch dependency that disappears after the model reaches production. Customer behavior changes, internal policy changes, available data changes, and the product’s own authority can expand. A system that was acceptable within one boundary can become unreliable when that boundary moves.
This creates expertise debt: the gap between what the AI is allowed to do and the judgment the organization has made explicit, tested, and maintained. Like other forms of product debt, it stays hidden during routine operation and becomes visible under change.
Assign ownership for the artifacts that control this gap:
- The product owner defines the customer outcome, product scope, and decision rights.
- The domain owner defines acceptable judgment, disqualifiers, and escalation conditions.
- Design makes system status, evidence, uncertainty, confirmation, and recovery understandable.
- Engineering and data owners enforce boundaries, capture relevant events, and make failures diagnosable.
- The accountable business or risk owner approves material changes to the system’s authority.
Maintain the judgment map, evaluation cases, escalation policy, and known failure modes as versioned product assets. Revisit them when the model or provider changes, retrieval or prompts change, the product enters a new use case, policy changes, a new error pattern appears, or experts repeatedly disagree. A model update is not the only event that can change customer risk.
Avoid using experts as permanent cleanup labor. If the same correction appears repeatedly, convert it into a rule, a better source, a product constraint, a new evaluation case, or a clearer handoff. The goal is not to remove experts. It is to spend their attention on novel judgment instead of making them repair the same predictable failure.
Key takeaways
- Judge a customer-facing AI feature by the decisions and actions it enables, not by the fluency of its output.
- Translate expertise into required evidence, disqualifiers, quality boundaries, consequence classes, and escalation triggers.
- Give the AI, customer, frontline operator, and accountable expert explicit decision rights.
- Test the system’s ability to stop and escalate, not only its ability to produce a good answer.
- Keep critical failures outside aggregate quality scores so routine success cannot conceal consequential mistakes.
- Treat expert rules, evaluation cases, and escalation policies as maintained product assets.
At the next feature review, ask the team to bring more than a polished output. Require the judgment map, the consequence classification, the decision owner, the escalation experience, and the cases that must block release. If those artifacts are missing, the feature is not ready for more prompt tuning. It is still missing its product design.
References
- Product School — Customer-Facing AI Product Design: 4 Levers To Make It Work
- The AI Educator — AI Slop Won’t Replace Expertise