Your next AI roadmap review may include a chat assistant, a copilot, and several model upgrades. That still leaves the harder product question unanswered: when should an AI response become a working interface instead of another block of text?
The answer changes what you prioritize, how you divide responsibility between the model and your application, and what you evaluate before launch. Get that division wrong and a polished calculator or chart can make a weak answer look authoritative. Get it right and the model can remove the handoffs between understanding a decision, exploring the options, and taking the next safe action.
The response is becoming a product surface
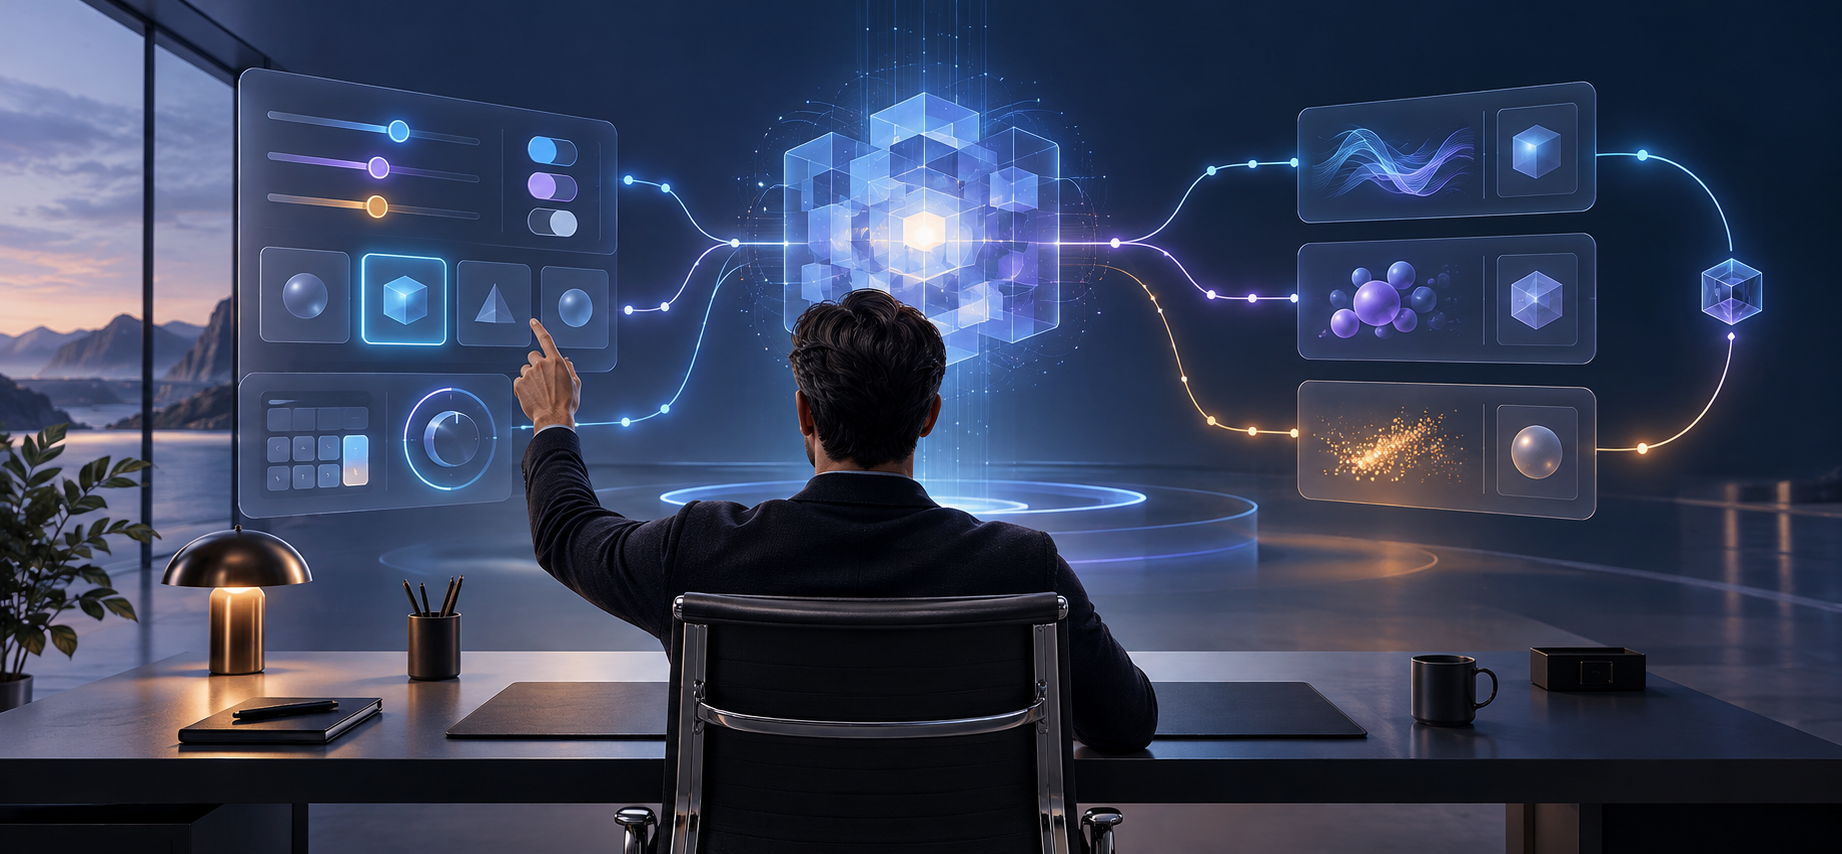
GPT-6 brought model-selected charts, buttons, forms, calculators, and decision flows to ChatGPT’s 1.2 billion weekly users. A person can change an input and see the result update inside the answer. The model decides whether the question calls for prose, a visual, a control, or a combination of them.
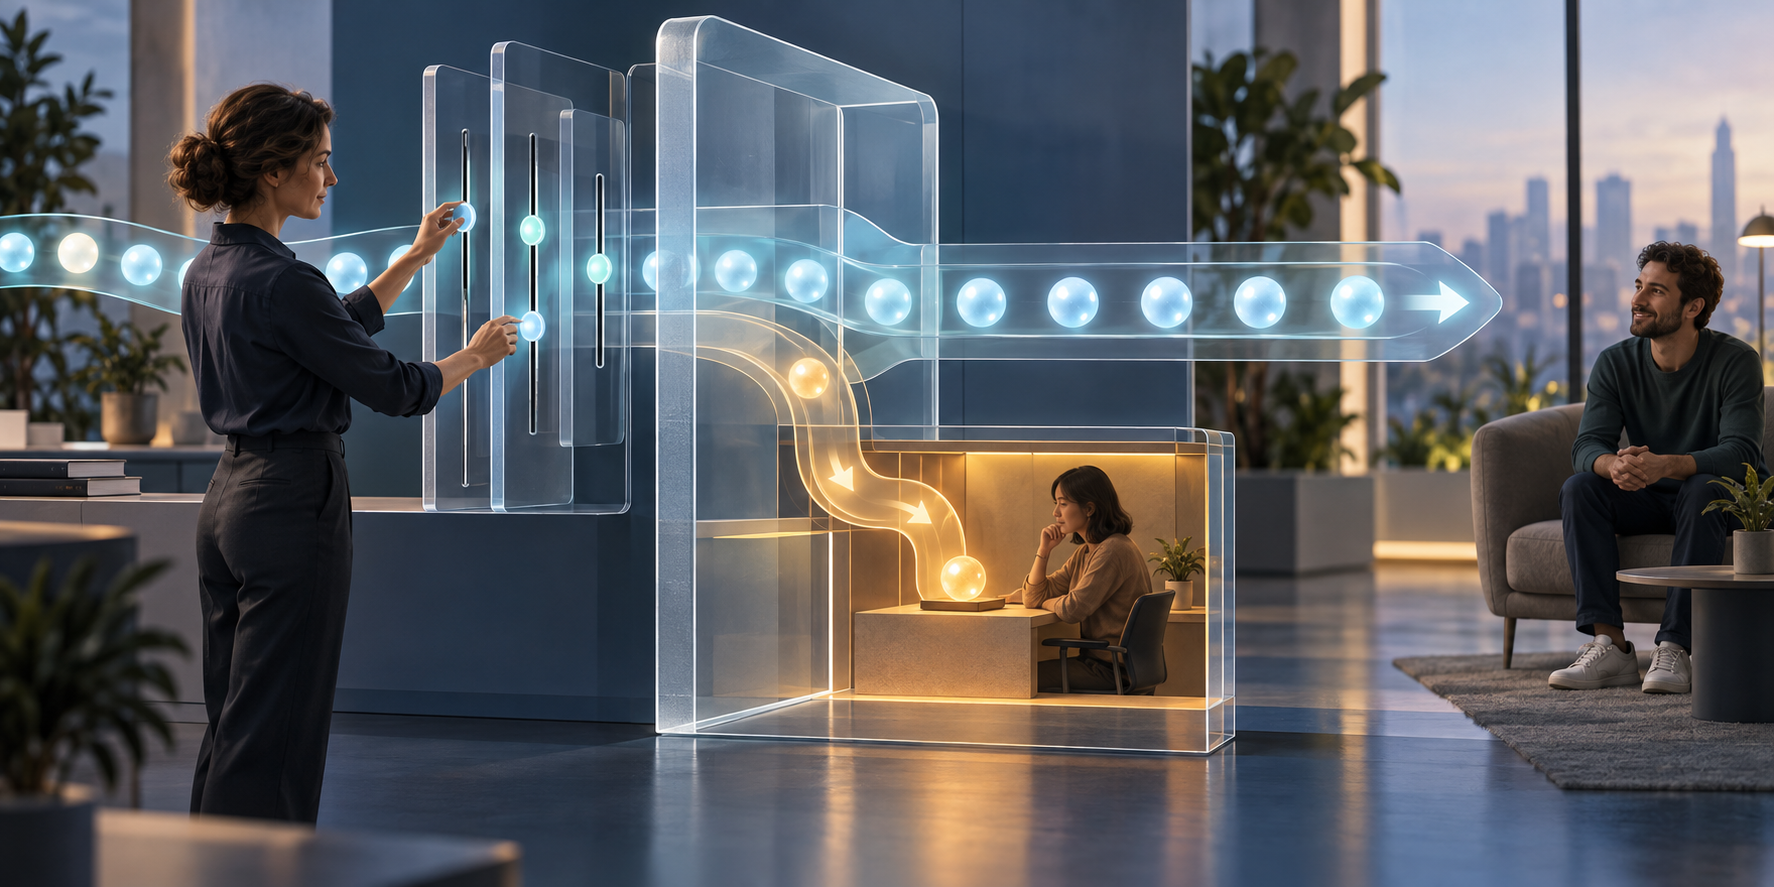
That is more than a presentation upgrade. A text response is usually an artifact: you read it, interpret it, and move somewhere else to do the work. An interactive response can be a stateful loop: inspect, adjust, compare, validate, and act. The unit of product value therefore moves from an answer delivered to a decision completed.
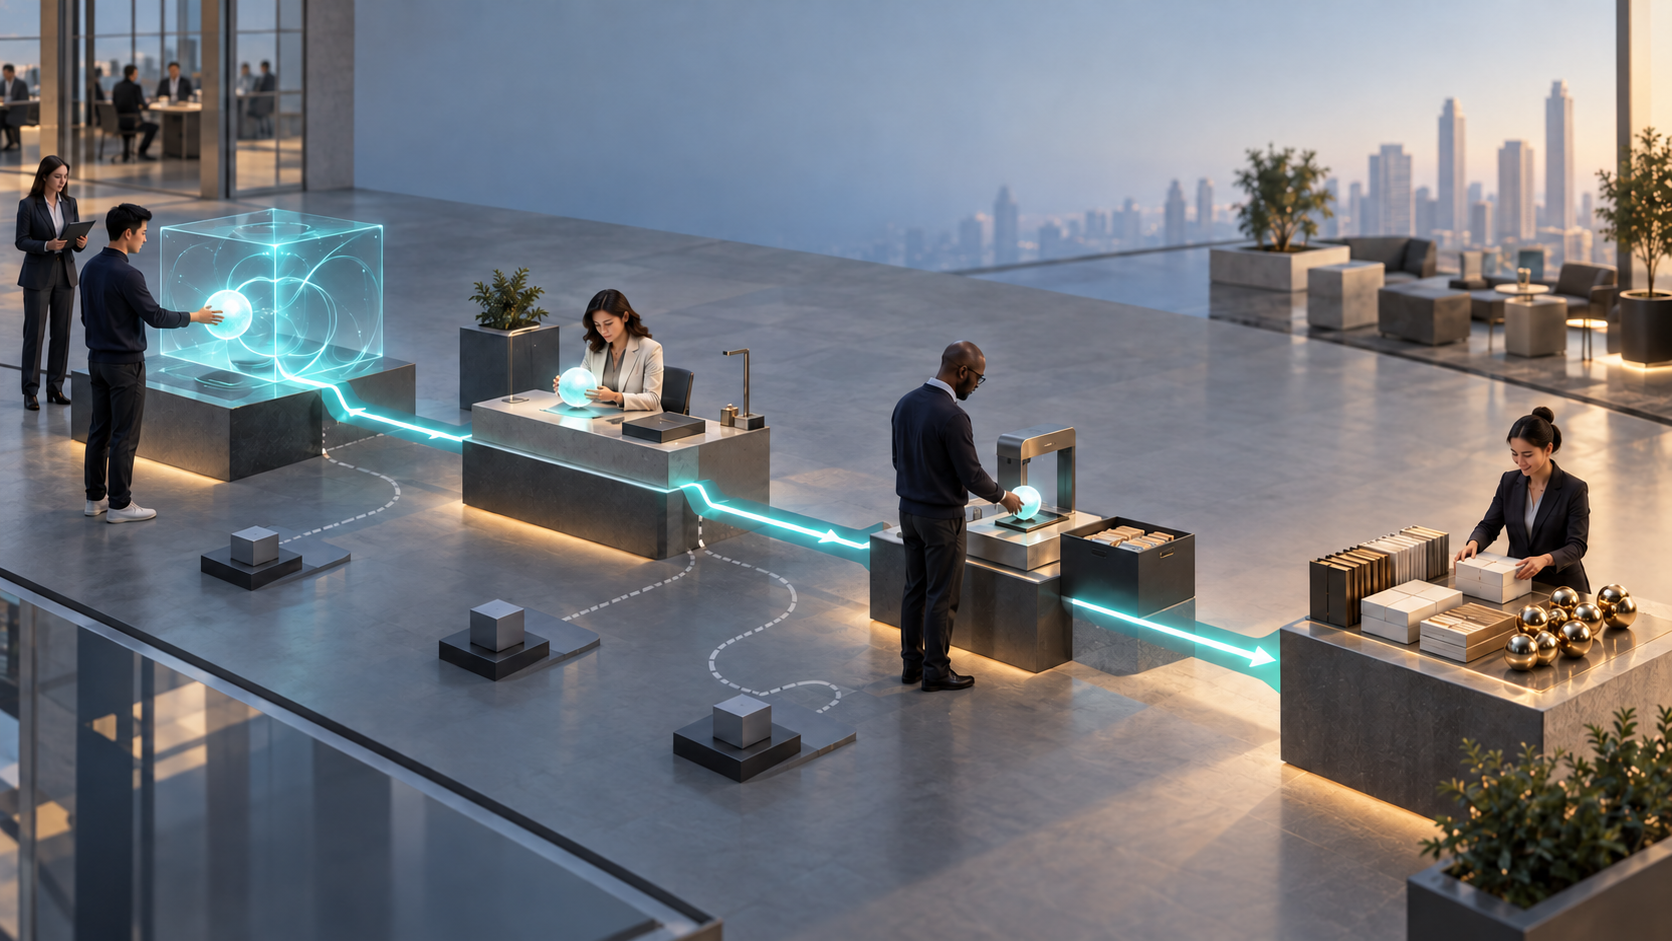
Consider an AI product that analyzes a customer-onboarding funnel. A prose answer can identify the largest drop-off and recommend an experiment. An interactive answer can also let the product manager change the cohort, time window, or segment; inspect the affected step; compare alternatives; and turn the selected option into an experiment brief. The advantage comes from removing those handoffs, not from adding a chart for its own sake.
| Interaction mode | User’s job | What the product must provide |
|---|---|---|
| Inform | Understand an answer | Clear language, grounded facts, and visible uncertainty |
| Explore | Change inputs and compare outcomes | Bound controls, deterministic recalculation, and stable state |
| Commit | Save a record or trigger an action | Permissions, confirmation, auditability, and recovery |
These modes should not blur into one another. A generated chart may be safe to explore without confirmation. Changing a billing rule, publishing a campaign, or modifying access is not. The model may choose a suitable presentation, but the product must decide where exploration ends and authority begins.
A generated answer is also only one interface strategy. Claude’s placement inside Google Docs, Sheets, and Slides represents another: bring AI into the durable workspace where the user already edits and stores the result. Before building an AI-native surface, decide which of these patterns fits the job:
- Generate a temporary interface when the task is exploratory, the relevant controls depend on the question, and the result may disappear after the decision.
- Embed AI in an existing workspace when the document, spreadsheet, design, or record is the durable object and AI is helping modify it.
- Hand off to a system workflow when an action needs formal validation, role-based access, approval, or an auditable transaction.
Do not assume every temporary interface should become a permanent feature. One promise of model-composed UI is that it can serve long-tail tasks that would never justify a dedicated screen. Your permanent product should be the trusted component system, data layer, and action layer underneath it.
Choose workflows by decision density, not visual novelty
The best candidate is rarely the workflow with the most impressive demo. It is the workflow with high decision density: the user must manipulate several meaningful inputs, compare alternatives, resolve missing information, or choose a branch before reaching a useful outcome.
A single-fact lookup usually needs a direct answer. A pricing scenario, incident-triage path, campaign configuration, or onboarding diagnosis may benefit from controls because the user is likely to ask several related follow-up questions. An interface earns its place when it compresses that loop.
Screen candidate workflows with these questions:
- Does the user repeatedly change inputs? Look for work currently done by editing a prompt, copying values into a spreadsheet, or asking nearly identical follow-up questions.
- Does comparison matter more than a single recommendation? Interactive controls are useful when seeing trade-offs produces confidence. They add little when only one grounded answer exists.
- Can the important rules be enforced outside the model? Calculations, validation, permissions, and policy constraints should have deterministic owners.
- Can the product show where the data came from and how fresh it is? A responsive control built on unknown or stale inputs creates false precision.
- Is the next action reversible or safely previewable? If a mistake creates material cost, data loss, or external exposure, keep the model in a draft or preview role.
- Will interactivity eliminate a real handoff? If the user still has to recreate the result elsewhere, the component may be decoration rather than workflow improvement.
Rate each candidate high, medium, or low on those questions. Prioritize the recurring workflows that are high on input manipulation, comparison, and handoff removal, with no hard failure on deterministic enforcement or action safety. This avoids false precision while still giving the roadmap discussion a consistent test.
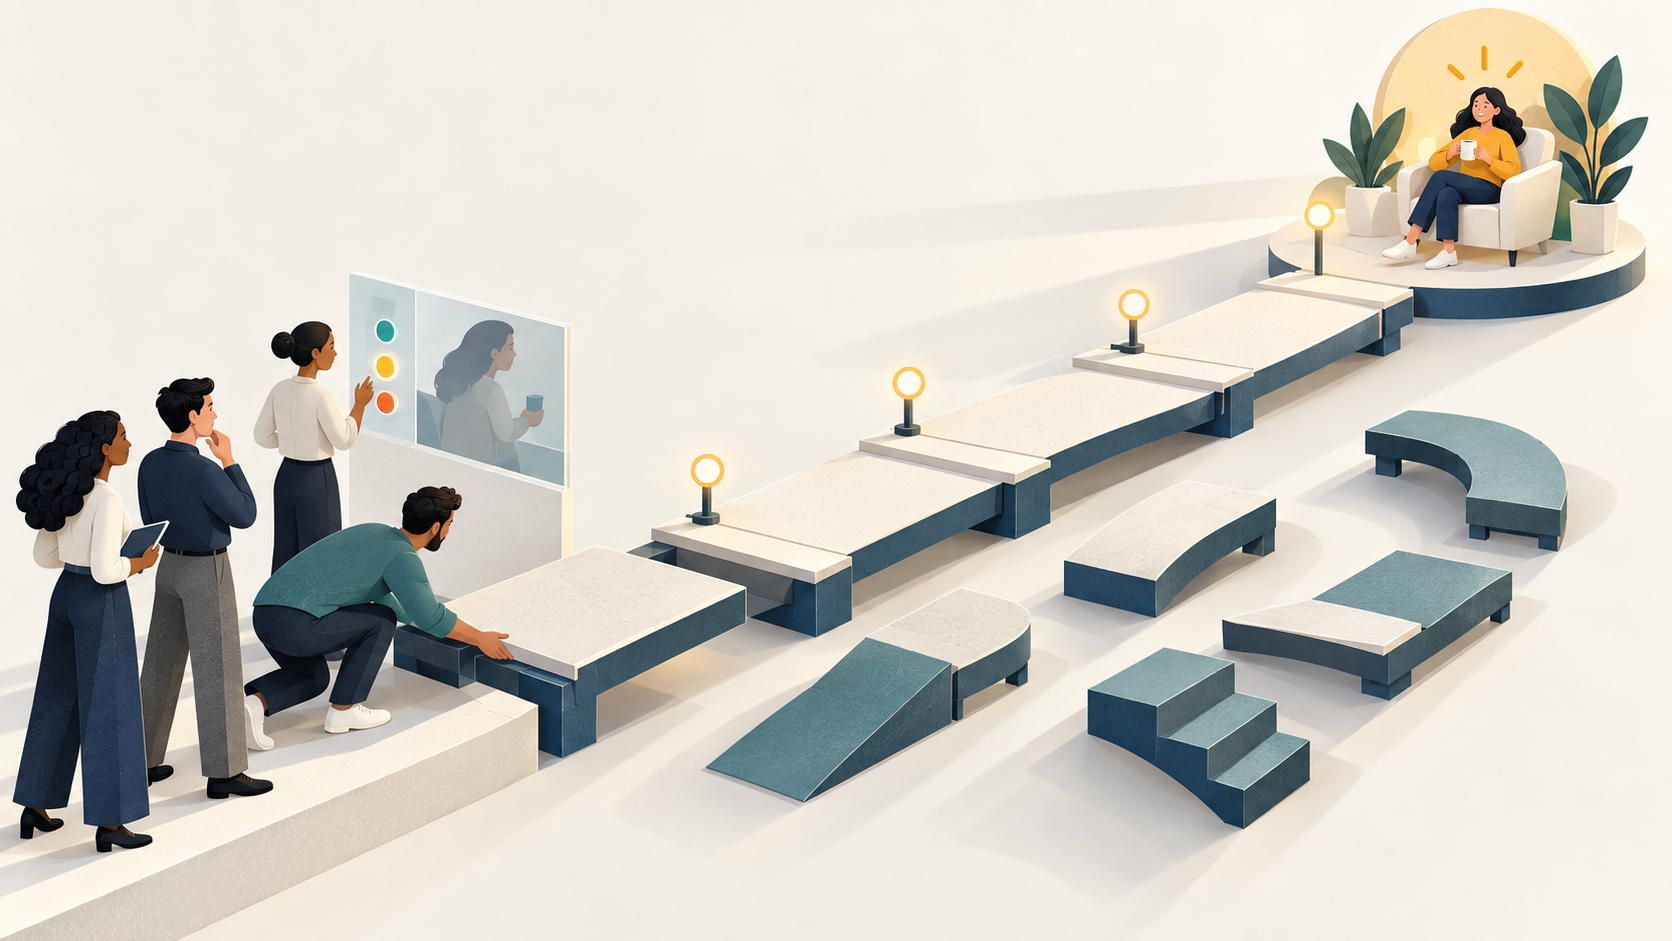
Then storyboard the job before designing components:
- Write the user’s job as a verb and outcome, such as “compare plans and select one,” rather than as a feature such as “show an AI table.”
- Mark every place the user leaves the current experience to calculate, verify, retrieve, reformat, or enter information.
- Identify the inputs the user is likely to revisit. Those are candidates for controls.
- Name the durable output: a decision, a saved configuration, a document, a system record, or no persistent artifact at all.
- Describe the failure the user must be able to notice, including stale data, a missing value, a conflicting instruction, or an unavailable action.
- Choose a generated surface, embedded workspace, or system handoff only after the earlier choices are explicit.
My rule is simple: if an interactive answer does not remove a meaningful handoff or make a consequential trade-off easier to inspect, leave the answer as text. Text is fast, accessible, familiar, and often exactly the right interface.
Define the interaction contract before exposing controls
A production interactive response should be constrained composition, not arbitrary front-end generation. Let the model select and populate governed primitives. Do not let it invent execution semantics, formulas, permission rules, or persistence behavior as it goes.
Your interaction contract should define:
- Component vocabulary: the charts, tables, forms, calculators, comparison cards, and decision controls the model may request.
- Input and output schemas: required fields, data types, units, allowed ranges, missing-value behavior, and validation messages.
- State boundaries: which values exist only in the conversation, which become saved drafts, and which are committed to a system of record.
- Data lineage: the origin and freshness of displayed values, plus whether they were retrieved, inferred, calculated, or supplied by the user.
- Action semantics: what preview, confirm, execute, cancel, retry, and undo mean for each supported action.
- Fallback behavior: a usable text representation when a component cannot render, a tool fails, or the current client does not support the interaction.
- Telemetry: events for rendering, validation, input changes, submission, cancellation, correction, fallback, failure, and reversal.
The ownership line should remain visible in the architecture as well as the interface.
| The model may propose | The product must enforce |
|---|---|
| User intent and a suitable component | The allowed component set and its schema |
| Extracted or suggested field values | Types, ranges, required fields, and validation |
| An explanation of a result | The calculation, retrieved data, and provenance |
| A recommended next action | Identity, authorization, confirmation, and execution |
| A conversational draft | Persistence, versioning, audit history, and recovery |
Take a pricing comparison as an example. The model can recognize that the user wants to compare seat counts, choose a calculator, populate known assumptions, and explain the difference. A pricing service should own the formula, currency, discount rules, and eligibility. The interface should label which values are assumptions. Saving or applying a price should be a separate, authorized action rather than an accidental consequence of changing a control.
This division also makes the product portable across models. Use a provider-neutral component request containing the component type, schema version, input bindings, data references, permitted actions, and text fallback. Add an adapter for each model instead of allowing a provider-specific output format to leak through the entire application.
Portability is not an abstract concern. Mistral Large 4 launched with API availability and open weights scheduled after additional security testing, while its license had not yet been published. Model capability, hosting choice, licensing, and availability can move on different timelines. If your roadmap depends on planned weights or a pending license, treat that as an unresolved dependency rather than a current asset.
Trust also has to survive the richer presentation. Put the data origin, relevant timestamp, assumptions, and limitations near the result they qualify. Do not label a chart as live unless the retrieval path actually fetched current data. Do not let an editable input imply that every value is permitted. When an action can spend money, modify access, publish externally, or destroy data, show the exact object, scope, and consequence before confirmation. If the action cannot be safely reversed, keep the model in compose-and-preview mode.
Evaluate the complete loop and release authority gradually
A model benchmark cannot tell you whether an interactive product works. The product can fail even when the prose is correct: the wrong component can appear, a control can bind to the wrong field, a recalculation can use stale state, or a confirmed action can differ from the preview.
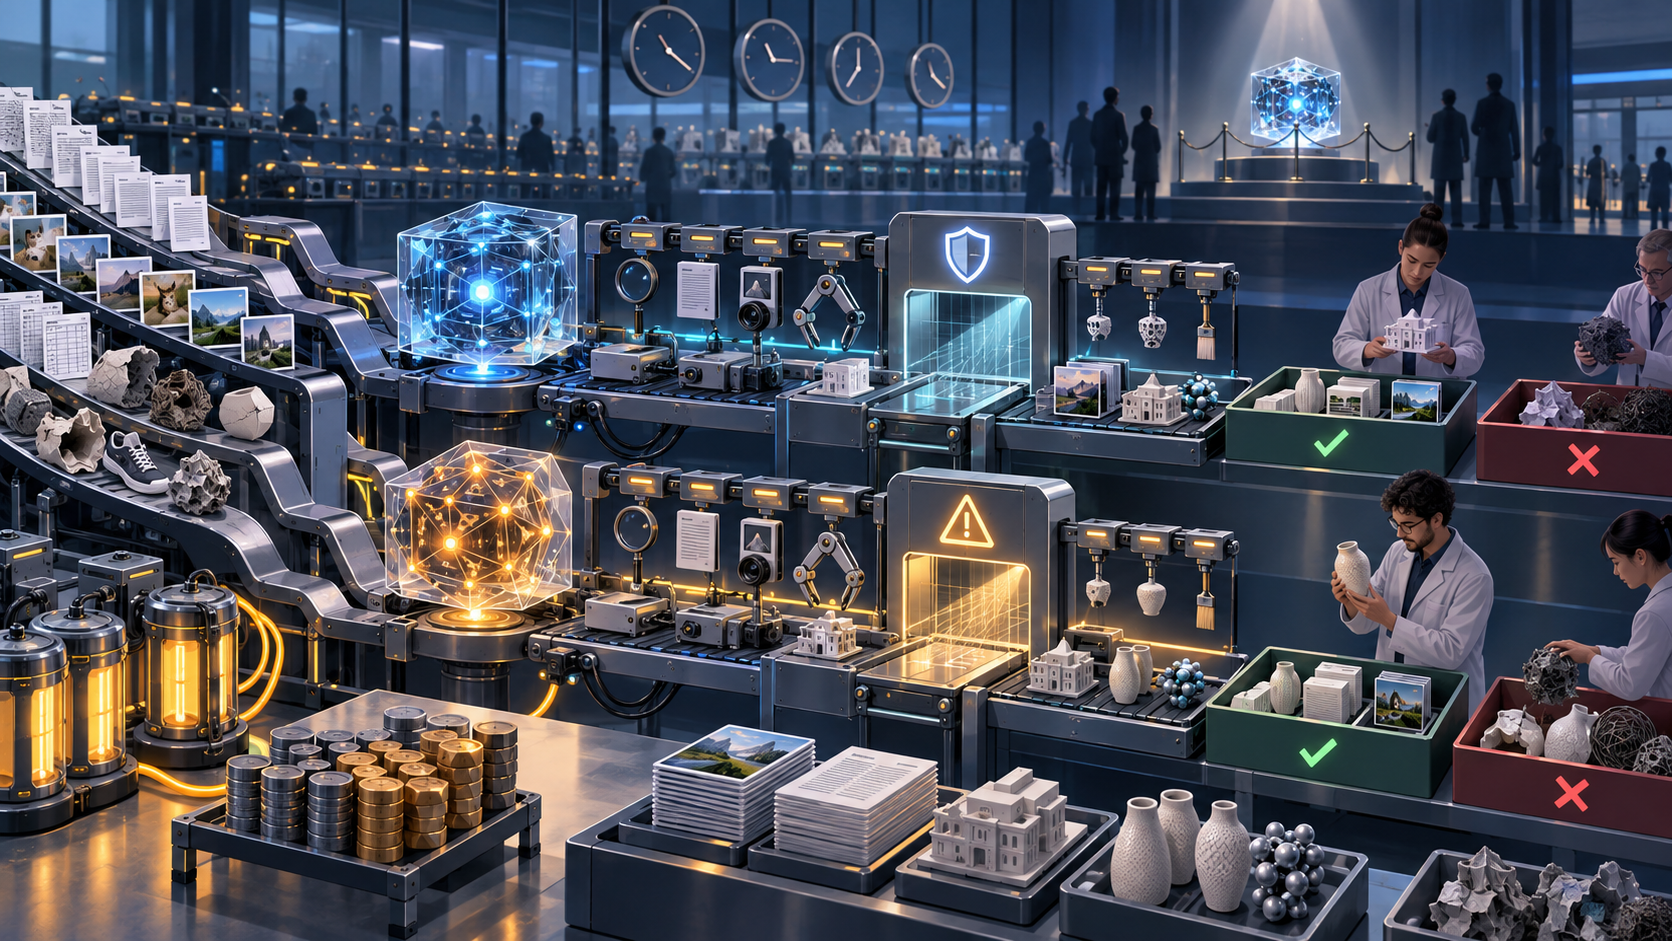
Test four layers separately
- Content: Did the system understand the request, retrieve the right information, preserve uncertainty, and avoid unsupported claims?
- Component: Did it choose an appropriate primitive, produce a valid schema, label fields and units clearly, and provide a usable fallback?
- Interaction: Do input changes update every dependent value correctly? Are errors visible? Does state behave predictably across follow-up turns?
- Action: Does the preview match the execution? Are identity, permissions, confirmation, idempotency, audit logging, and recovery enforced?
Build the evaluation set around failure transitions, not only happy-path prompts. It should include underspecified requests, contradictory inputs, invalid ranges, missing or stale data, unavailable tools, denied permissions, user edits after generation, interrupted execution, and unsupported component clients. For each case, define the acceptable component, the required clarification or warning, whether an action is allowed, and the text fallback.
Record enough lineage to reproduce failures: the model, system instructions, component schema version, tool calls, data timestamp, validation result, and action outcome. Do not indiscriminately log sensitive field values. The debugging trail should explain what happened without creating a second, poorly governed copy of customer data.
Measure the task, not the novelty of the widget. Useful product metrics include correct task completion, time to completion, validation failures, user corrections, abandonment after a component appears, fallback-to-text rate, action cancellation, and reversal. A high click rate can coexist with a low success rate if people are clicking because the generated interface is confusing.
When you run an A/B test, compare the interactive experience with the best realistic non-interactive flow, not a deliberately weak text answer. Randomize at the task or user level so repeated exposure does not mix the experiences. Evaluate completion and error outcomes together. Faster completion is not a win if it also increases incorrect or unintended actions.
Use a staged authority ladder
- Compose: the model creates a structured draft, but nothing leaves the conversation or workspace.
- Preview: the product resolves data and shows the exact change without committing it.
- Confirmed execution: the user approves a narrow action with clear scope and a recovery path.
- Conditional autonomy: only repeatable, bounded actions with demonstrated reliability can run under explicit conditions, monitoring, and limits.
Do not assume one interface evaluation covers every model tier. ChatGPT uses GPT-6 Sol for paid tiers and GPT-6 Luna for Free and Go while exposing the same Intelligent UI concept. A consistent component library can still receive different selections, field values, explanations, or tool-use decisions from different models. Run the same interaction suite against every model and configuration you intend to serve.
Release controls should be equally granular. Keep switches for a component type, action type, model configuration, and execution path. If generated charts become unreliable, you should be able to fall back to a table or text without disabling forms. If an execution integration fails, users should still be able to compose and export a draft. A single global AI flag turns a local failure into a product-wide outage.
Key takeaways
- Optimize interactive AI for a completed decision or task, not a more elaborate response.
- Prioritize workflows with mutable inputs, meaningful comparisons, enforceable rules, and a handoff that the interface can remove.
- Let the model propose presentation and language; keep calculations, validation, permissions, persistence, and execution under product control.
- Evaluate content, component generation, interaction state, and action behavior as separate failure surfaces.
- Move from composition to preview, confirmed execution, and conditional autonomy only as evidence and reversibility allow.
- Keep the component contract provider-neutral and preserve a text fallback for every generated surface.
At your next roadmap review, choose one recurring workflow where users repeatedly adjust inputs or leave the product to finish the job. Define the non-interactive baseline, interaction contract, failure cases, and authority boundary before building the visual layer. If the generated surface cannot remove a handoff without obscuring who controls the data or action, keep it as an answer. If it can, you have the foundation for an AI product that does more than talk.
References
- The Creators AI – ChatGPT Gets Interactive, Mistral’s European Giant, Manus Bounces Back
- AI Search – Gemini 4, GPT 6.1, Dots, Claude Sonnet 5.5, Ideogram 4.5, Flux 3: AI NEWS