
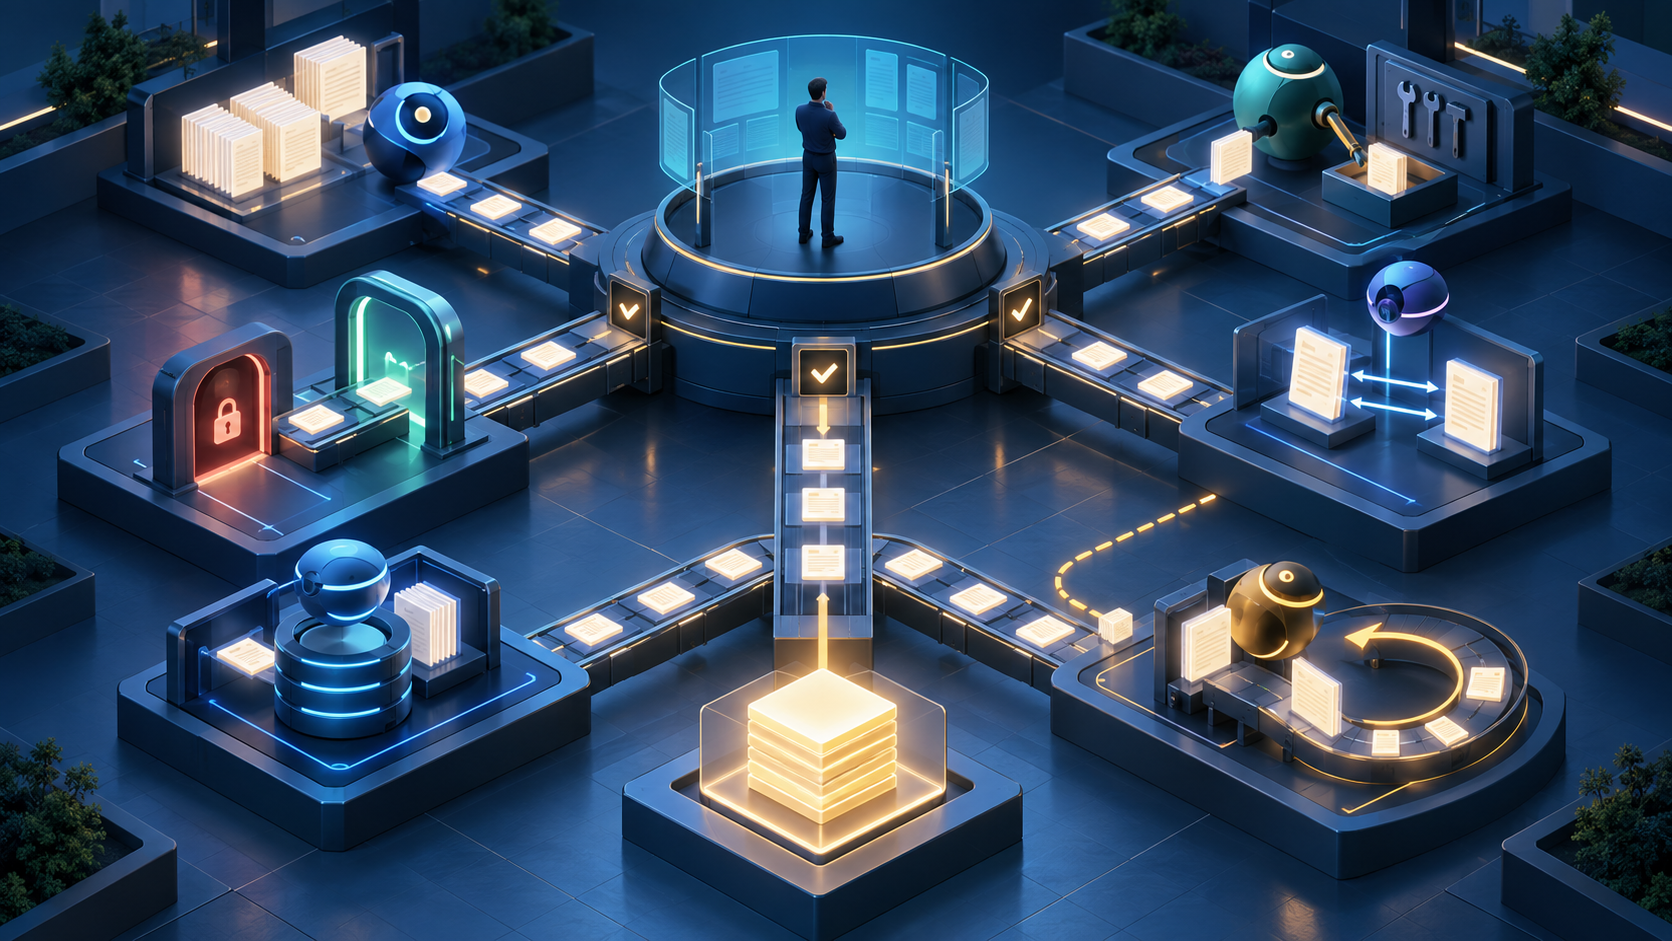
You have a consequential workflow that already strains people, systems, and handoffs. The agent demo looks promising, but the production decision is harder: what should the agent own, how should the work be divided, and how will you know whether the system is solving the problem rather than generating plausible activity?
The practical opportunity in using AI agents to tackle large-scale problems is not unlimited autonomy. It is controlled delegation. You give software a bounded objective, the context and tools required to pursue it, and explicit rules for checking work, recording state, recovering from failure, and asking for help. Get those boundaries right and an agent can coordinate work that would overwhelm a single prompt. Get them wrong and you scale uncertainty.
Define the problem before you design the agent
Large-scale does not simply mean a high volume of prompts. A problem becomes large in an operational sense when the work crosses systems, contains dependent steps, changes over time, or can fail partially. A customer escalation that touches a CRM, billing platform, knowledge base, and support queue may be a larger agent problem than processing a long document because it has more state, permissions, and failure paths.
Start with the work, not the model. An agent is a reasonable candidate when the problem passes five tests:
- The outcome is observable. You can tell whether the case was resolved, the investigation was complete, the plan met its constraints, or the recommendation was accepted.
- The work is decomposable. The workflow can be expressed as distinct decisions or actions with identifiable inputs and outputs.
- Intermediate work is evaluable. A person, deterministic rule, or separate evaluation process can inspect important steps before their errors propagate.
- Authority can be bounded. You can specify which data the agent may read, which tools it may call, what it may change, and where approval is mandatory.
- Failure is recoverable. The system can pause, retry safely, roll back a reversible action, or transfer the case without losing its history.
If the desired outcome is still disputed, the agent will not resolve the product strategy for you. It will automate whichever interpretation happens to be encoded in its prompt, tools, or evaluation criteria. That is why ambiguous work should begin with discovery: map the decisions people make, the evidence they use, and the exceptions they encounter before specifying an autonomous workflow.
Write a problem contract
A useful problem contract is short enough for product, operations, engineering, and risk owners to challenge together. It should define the following before implementation begins:
| Contract element | Question it must answer | What it prevents |
|---|---|---|
| Outcome | What change in the real workflow counts as success? | Optimizing for polished output instead of business value |
| Unit of work | What does one case, request, investigation, or plan contain? | Mixing unrelated tasks and measuring them inconsistently |
| Scope | What may the system do, and what is explicitly outside its role? | Authority expanding through vague instructions |
| Definition of done | Which evidence and checks are required before completion? | Premature completion based on fluent text |
| Constraints | Which policy, privacy, cost, latency, or quality conditions must always hold? | Trading safety or economics for task completion |
| Escalation | Which conditions require a person, and who receives the case? | Silent failure and unowned exception queues |
| Anti-goals | Which outcomes must the system avoid even if they improve a headline metric? | Metric gaming and harmful shortcuts |
The most revealing field is usually the definition of done. If stakeholders cannot agree on the evidence required to close a case, the team is not ready to delegate that decision. Automate information gathering or drafting first, while a person retains the disputed judgment.
Turn the workflow into a graph of bounded tasks
A complex objective should not become one giant prompt. Represent it as a graph in which each task has a purpose, required input, permitted tools, output schema, acceptance check, and next possible state. The graph may be mostly fixed for a stable operational process or assembled dynamically when the path depends on what the agent discovers. In either case, the system should make the active state inspectable.
A practical decomposition sequence is:
- Normalize the request. Convert the incoming request into a structured case with a type, objective, constraints, missing information, and sensitivity classification.
- Build the plan. Select the tasks required for this case, their dependencies, and the checks that must pass before the next task starts.
- Acquire evidence. Retrieve approved records, query tools, and label missing or conflicting information instead of filling gaps with assumptions.
- Execute bounded work. Produce a draft, analysis, recommendation, or permitted action using only the tools assigned to that task.
- Verify the result. Check the output against the task’s acceptance criteria, policies, and available evidence.
- Commit or escalate. Save the accepted result, request approval for a controlled action, or hand off the complete case state to a person.
Each task should be restartable without replaying every prior step. Store the result and the evidence reference at the task boundary. For actions that might be retried, use an idempotency key or an equivalent safeguard so that a network error does not turn one intended update into duplicate tickets, messages, transactions, or records.
Treat roles as functions, not as characters
Planner, researcher, executor, critic, and supervisor are useful functions. They do not automatically require five separate agents. Begin with the simplest architecture that preserves clear state and controls. A single orchestrator can invoke specialized prompts, deterministic services, retrieval, and tools while maintaining one authoritative record of the case.
Split a function into another agent only when the separation creates an operational benefit. Good reasons include different permission boundaries, genuinely independent verification, isolated context, a need to run work in parallel, or a separately owned service-level objective. Giving every role an agent because the labels sound organizational adds messages, latency, cost, and more places for state to diverge.
Independent verification deserves special care. If the executor and critic receive the same incomplete evidence and follow nearly identical instructions, agreement between them is weak evidence of correctness. The verifier should have explicit criteria and, where the workflow permits it, a different validation method: a deterministic calculation, a policy engine, a schema check, a comparison with an authoritative record, or a human decision.
Separate run state, working context, and durable knowledge
Do not ask the conversation history to serve as the workflow database. A production run needs structured state that can survive a context reset, retry, model change, or human handoff. A minimal case record might include a case identifier, task identifier, current state, evidence references, action log, approval status, retry count, and final disposition.
- Run state records what has happened in this case and what must happen next.
- Working context contains only the information needed for the current decision.
- Durable knowledge contains approved policies, product information, operating procedures, and other maintained reference material.
Keeping those layers separate makes stale knowledge, missing evidence, and orchestration defects distinguishable. It also lets you update a policy without rewriting the history of completed cases. A larger context window may delay the symptoms of poor state design, but it does not repair them.
Put evidence, permissions, and recovery at every handoff
The safest place to control an agent is not only at the final answer. Controls belong at the handoffs between planning, evidence gathering, tool use, verification, and commitment. Every handoff should answer three questions: what changed, what evidence supports it, and what is now allowed to happen?
Require important outputs to carry an evidence bundle. That bundle should identify the claims or decisions being made, the records used, unresolved conflicts, validation results, and any uncertainty that matters to the next step. Evidence references are more useful than a generic confidence score because a reviewer can inspect them and a later evaluation can determine which input led to the error.
Then match authority to consequence:
| Action class | Sensible default | Required control |
|---|---|---|
| Read approved internal data | Automatic within the case scope | Scoped credentials, access logging, and data minimization |
| Analyze, classify, or draft | Automatic when outputs remain internal | Schema validation, evidence links, and clear draft status |
| Make a reversible internal update | Policy-dependent | Precondition check, bounded fields, audit log, and rollback path |
| Communicate externally | Approval until the use case earns narrower autonomy | Recipient check, content policy, preview, and attributable sender |
| Take financial, contractual, privacy-affecting, or irreversible action | Explicit human authorization | Independent review with the material facts and consequences visible |
Human approval is valuable only if the reviewer can make an informed decision. Do not present a green button beside a long, opaque transcript. Show the proposed action, the evidence that supports it, the rule that permits it, the meaningful alternatives, and what cannot be undone. For legal, financial, privacy, or safety consequences, the agent can prepare the decision record, but it should not masquerade as independent professional judgment.
Assume retrieved content can be hostile
An agent may encounter instructions inside emails, documents, web pages, support tickets, or tool results. Treat that material as untrusted data, not as authority over the workflow. System policy and tool permissions must remain separate from retrieved text. Validate tool arguments, allowlist permitted operations, and reject attempts to obtain secrets, broaden scope, or alter the approval rules.
Use the least-privileged credential that can complete each task. A research step that only needs to read a knowledge base should not inherit the ability to modify customer records. A drafting step should not receive a message-sending credential. This containment limits the damage from prompt injection, model error, and ordinary implementation mistakes.
Design recovery before scaling volume. Define which errors can be retried, which actions must be checked before retry, which state can be rolled back, and which failures go directly to a person. The human handoff should include the objective, completed tasks, evidence, attempted actions, failure reason, and the exact decision required. Otherwise, escalation merely transfers confusion.
Measure accepted outcomes, not agent activity
Agent dashboards often overemphasize model latency, token use, tool calls, or the number of completed runs. Those signals help engineering diagnose a system, but none proves that the workflow created value. Product leadership needs a metric tree that connects technical behavior to accepted operational outcomes.
Track at least five layers:
- Outcome: resolution, cycle time, backlog movement, conversion, prevented loss, or another result named in the problem contract.
- Quality: acceptance by the downstream user, completeness, factual support, policy adherence, and correction rate.
- Reliability: successful completion, partial completion, retry, dead end, escalation, rollback, and dependency failure.
- Economics: model, tool, infrastructure, review, delay, and correction cost per accepted outcome.
- Human load: review time, avoidable escalations, repeated work, and the cognitive effort required to understand the agent’s decision.
Three calculations keep the dashboard honest:
- Completion yield = accepted completed cases divided by eligible cases started.
- Autonomy yield = accepted completed cases requiring no human intervention divided by eligible cases started.
- Cost per accepted outcome = model, tool, infrastructure, review, and correction costs divided by accepted outcomes.
Autonomy yield must remain subordinate to quality and risk. A lower escalation rate is not an improvement if the system is silently making worse decisions. Likewise, a cheaper model is not economical if its errors generate more review and rework. Use the accepted outcome as the denominator that ties quality, autonomy, and cost together.
Build evaluations around the real distribution of work
Create an evaluation set from approved, representative cases and label the expected outcome or scoring criteria. Include ordinary cases, known edge conditions, conflicting evidence, missing information, tool failures, policy boundaries, and adversarial instructions. Keep a stable set for regression testing and supplement it with newly reviewed production cases so the evaluation does not freeze around yesterday’s workflow.
Score the components separately. A final answer can fail because the plan omitted a step, retrieval returned the wrong record, a tool call changed the wrong field, the verifier missed a contradiction, or the user interface concealed an important uncertainty. One composite score hides those causes and sends the team toward model tuning when the defect may be in orchestration, data, permissions, or product design.
Give every run a trace that connects the request, plan, retrieved evidence, model decisions, tool calls, state transitions, approvals, and final disposition. Redact or restrict sensitive fields rather than abandoning traceability. When an evaluation fails, the team should be able to identify the first incorrect transition, not merely inspect the final prose.
Set release gates from the problem contract before looking at results. Define which quality, risk, cost, and human-load conditions must hold for the next authority level. The correct threshold depends on the consequence of the workflow; the important discipline is that the team agrees on it before a persuasive demo changes the conversation.
Scale authority in stages, with a named owner
Large-scale deployment should expand along two separate axes: volume and authority. Increasing both at once makes failures harder to interpret and consequences harder to contain. A staged rollout lets the agent earn a larger operating envelope.
- Offline evaluation. Run representative approved cases without touching production systems. Fix planning, retrieval, tool-selection, and verification failures against known criteria.
- Shadow mode. Process live cases without influencing the real workflow. Compare proposed decisions with actual outcomes and investigate disagreement by case type.
- Draft mode. Let the system prepare work for a person to inspect and submit. Measure acceptance, editing effort, missed risks, and whether review takes less work than doing the task directly.
- Bounded execution. Permit reversible actions for clearly eligible cases. Keep consequential actions behind explicit approval and maintain the rollback path.
- Expanded operation. Increase eligible case types, volume, or authority one boundary at a time. Continue sampling accepted cases and reviewing every material failure.
Each stage needs an exit decision, not just an end date. Promote the system when it meets the agreed gates across relevant case segments. Hold it when the evidence is insufficient. Reduce its authority when failures reveal a boundary the design does not yet control.
Assign one directly accountable owner for the end-to-end outcome. Engineering may own runtime reliability, data teams may own retrieval quality, security may own access controls, operations may own exception handling, and product may own the contract and customer impact. But a multi-agent workflow will expose the gaps between those functions. Without one owner for the complete system, every component can meet its local objective while the workflow still fails.
The owner should run a regular review that examines accepted outcomes, high-consequence failures, escalations, policy changes, cost shifts, and changes in the underlying case distribution. The point is not to admire aggregate success. It is to decide which boundary can safely expand, which defect class deserves priority, and which use case should remain human-led.
Key takeaways
- Use an agent when the outcome, task boundaries, evaluation method, authority, and recovery path can be made explicit.
- Model complex work as inspectable tasks with structured state; do not use one long conversation as the workflow engine.
- Treat planner, executor, and verifier as functions. Add separate agents only when isolation, permission boundaries, independent checks, or parallel work justify the coordination cost.
- Attach evidence and acceptance checks to intermediate work before errors can propagate into consequential actions.
- Measure accepted outcomes, correction effort, risk, and total cost. Activity and autonomy are supporting signals, not the objective.
- Increase volume and authority separately, with a named owner accountable for the complete operating system.
Choose one workflow that currently suffers from costly coordination, then write its problem contract and task graph before selecting an architecture. Give the first version read access, drafting responsibility, and a rigorous evaluation loop. Let wider authority be something the system earns through observable outcomes. That is how an agent becomes dependable infrastructure rather than an impressive demonstration.
References






