
observability
- AI Strategy (429)
- Generative AI (113)
- IT Leadership (38)
- Leadership (81)
- Product Management (394)
- Product Management Leadership (373)
- Uncategorized (32)
-
The Organizational Infrastructure Responsible AI Actually Needs
A practical operating model for assigning AI ownership, limiting agent authority, funding human oversight, and turning failures into safer systems.
-
How to Build AI Agent Infrastructure That Proves Value
A practical operating model for tracing agent runs, diagnosing failures, controlling routing costs, and connecting performance to business outcomes.
-
How to Evaluate and Optimize Open Models for Production
A practical framework for deciding whether an open model is production-ready, then improving quality, latency, cost, and reliability.
-
Production AI Agent Operations: A Practical Operating Model
A practical operating model for reliable AI agents, covering orchestration, safe retries, evaluations, controlled releases, monitoring, and incidents.
-
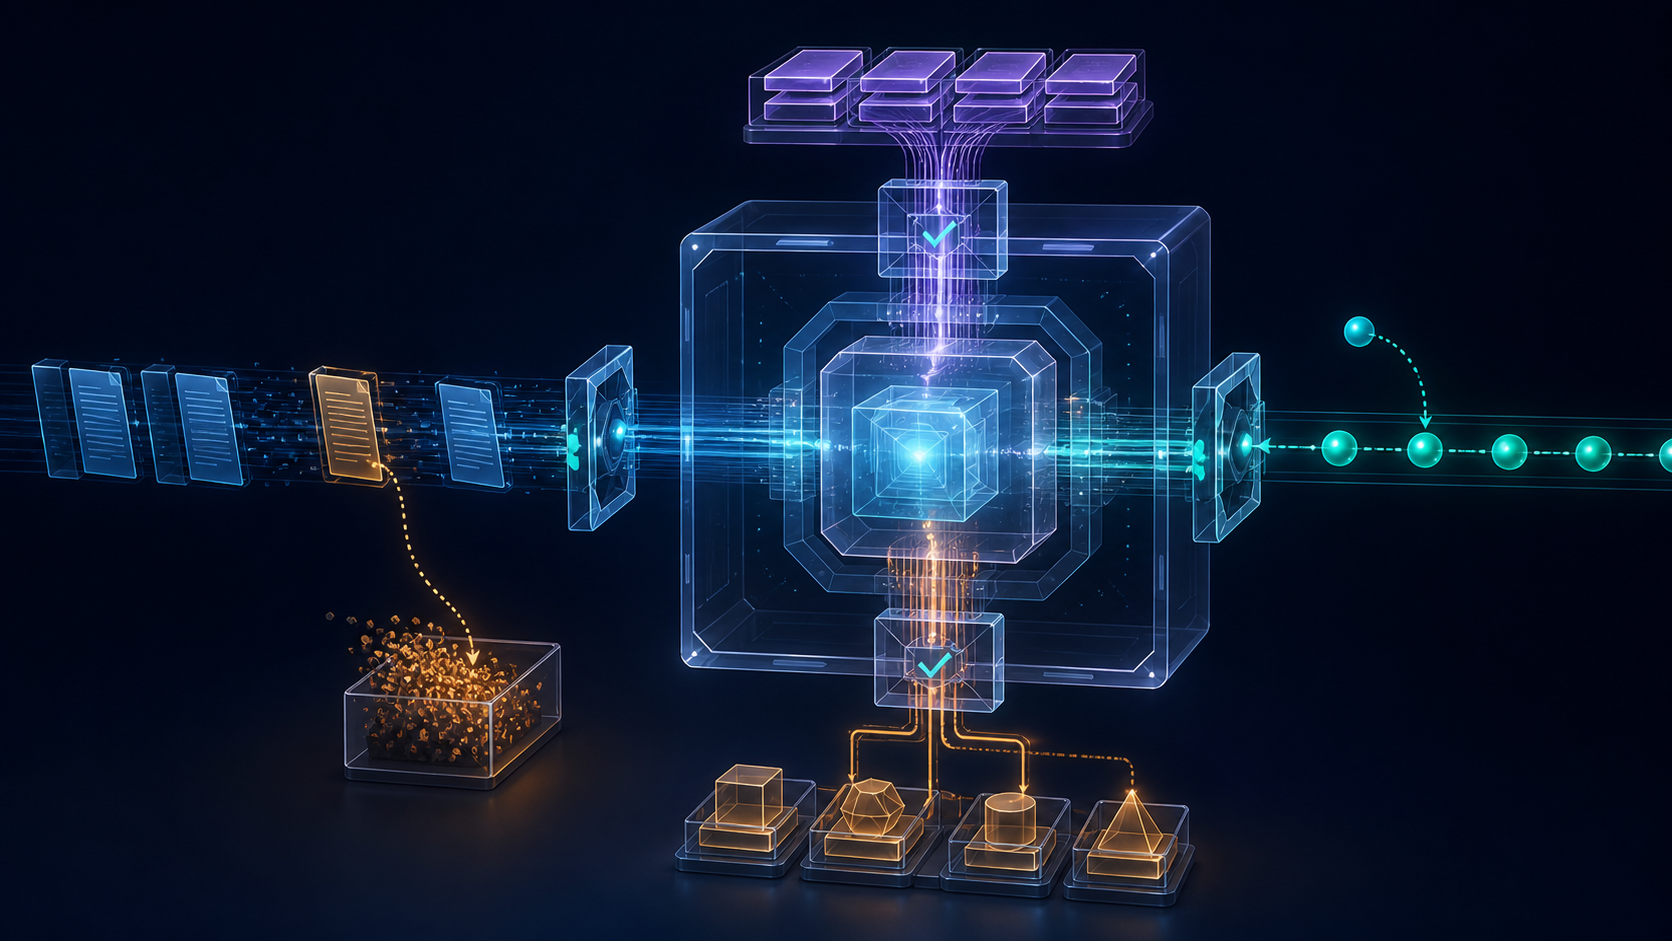
Context Engineering: How to Build Reliable AI Applications
A practical framework for designing context, diagnosing agent failures, budgeting each turn, and evaluating AI applications before production.
-
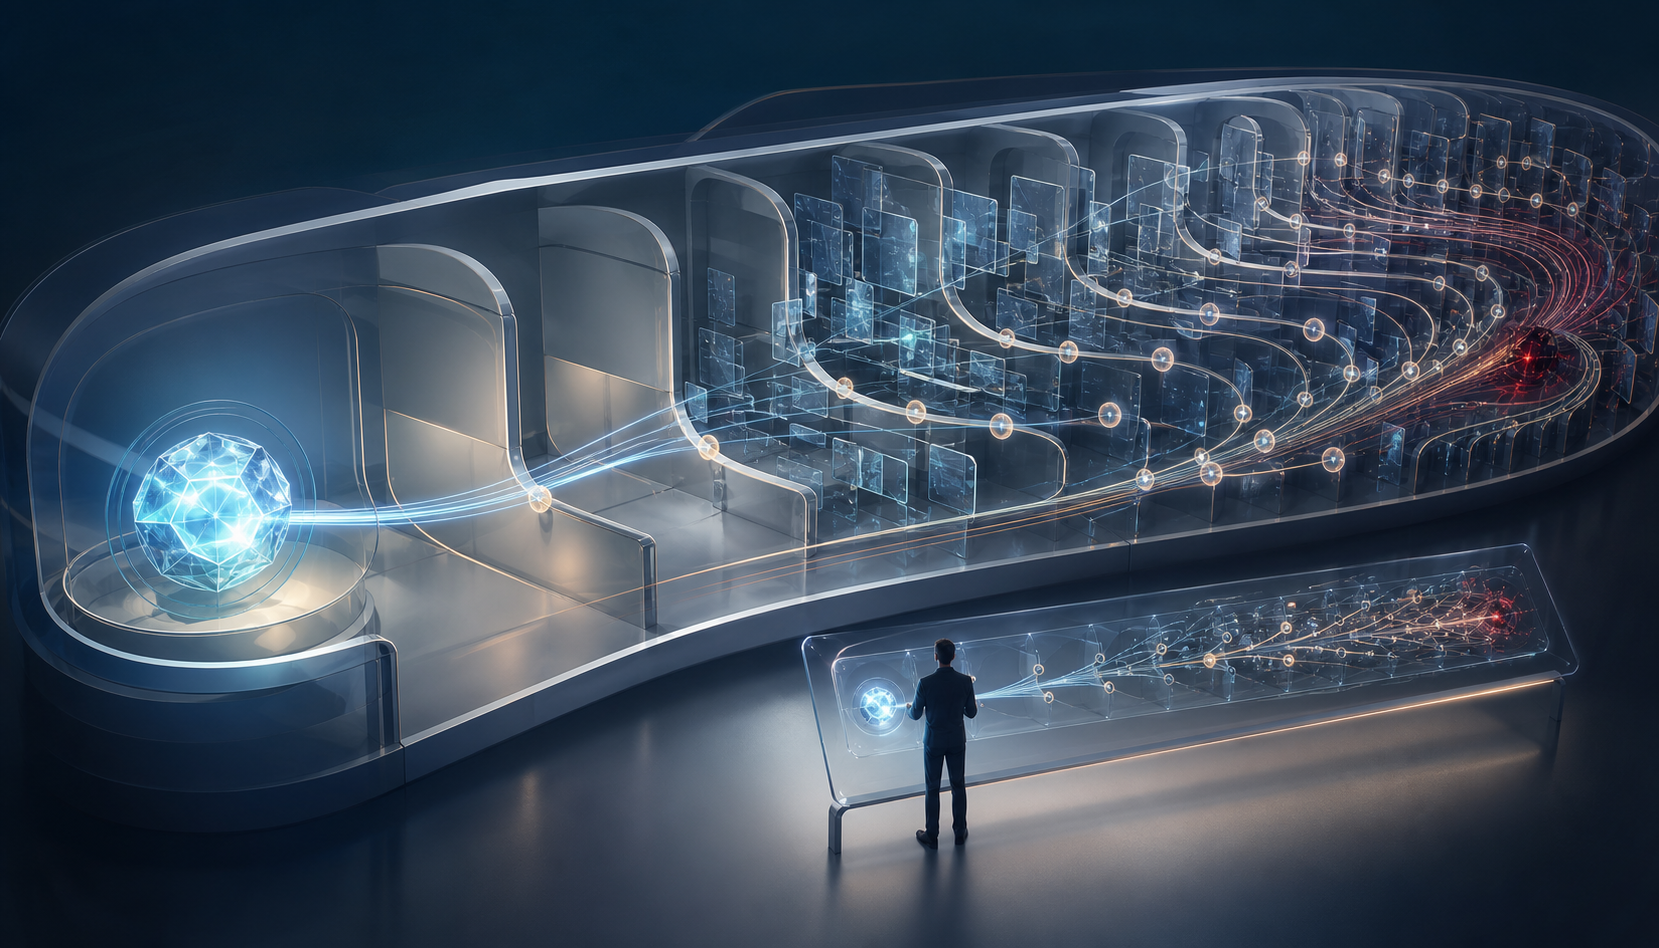
How to Evaluate AI Risks That Emerge After Deployment
A practical framework for testing stateful AI across long user trajectories, monitoring drift after launch, and resisting misleading satisfaction metrics.
-
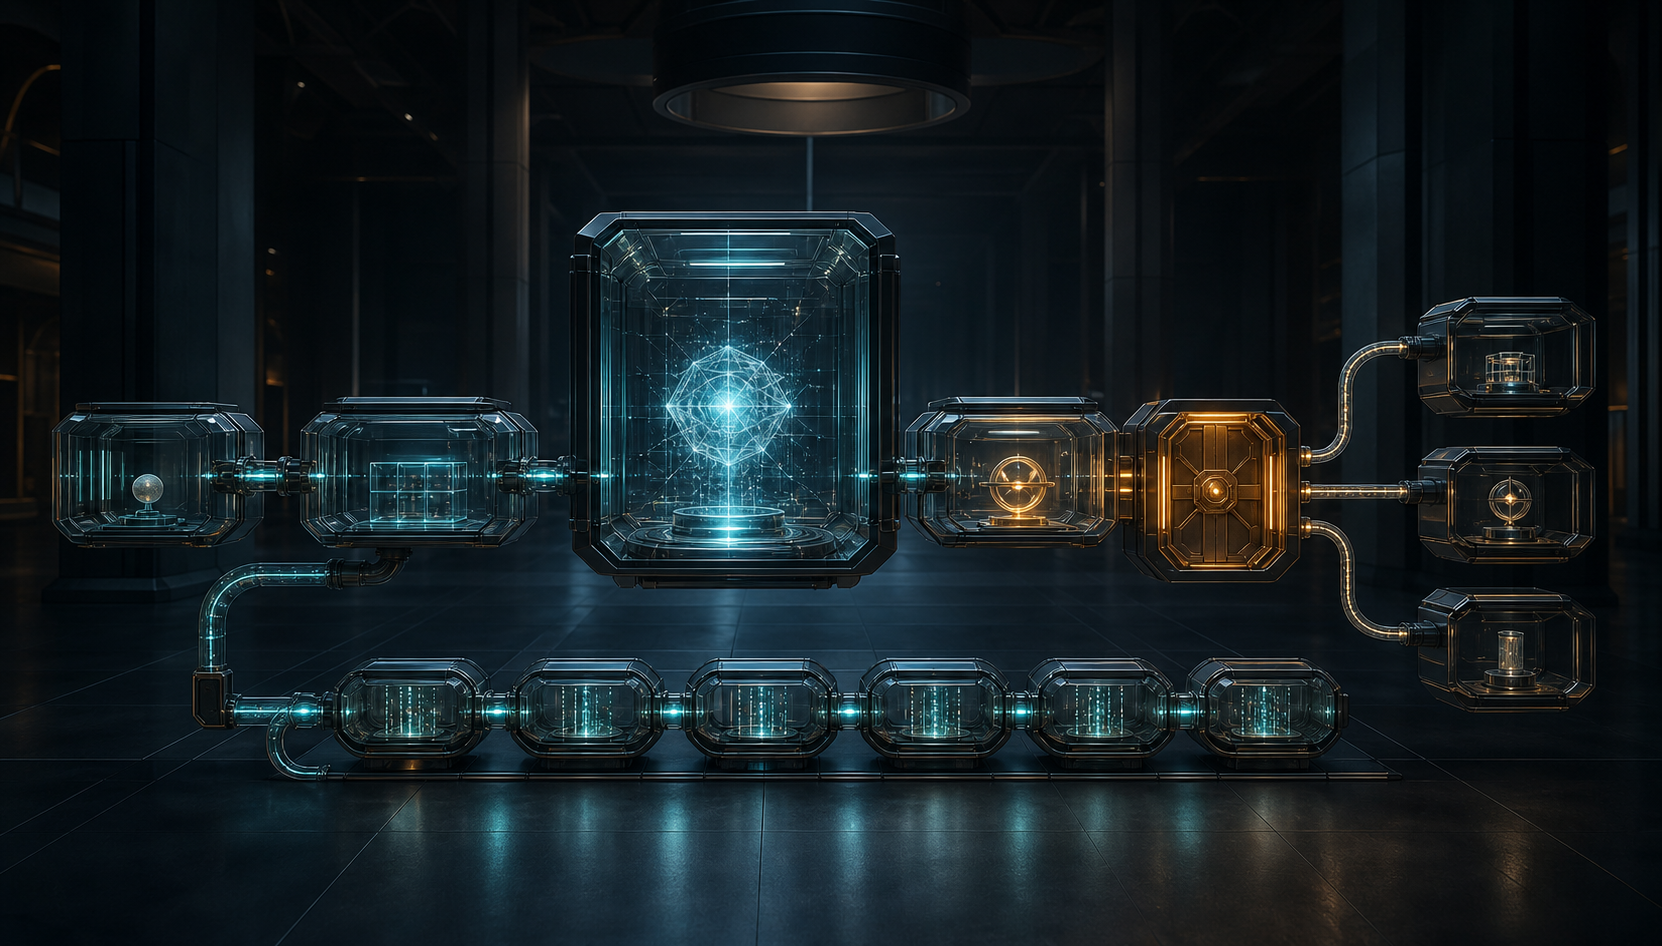
Reliable Agentic AI Architectures: A Production Blueprint
A production blueprint for agentic AI covering bounded graphs, independent verification, safe tool execution, durable state, and eval-driven rollout.
-
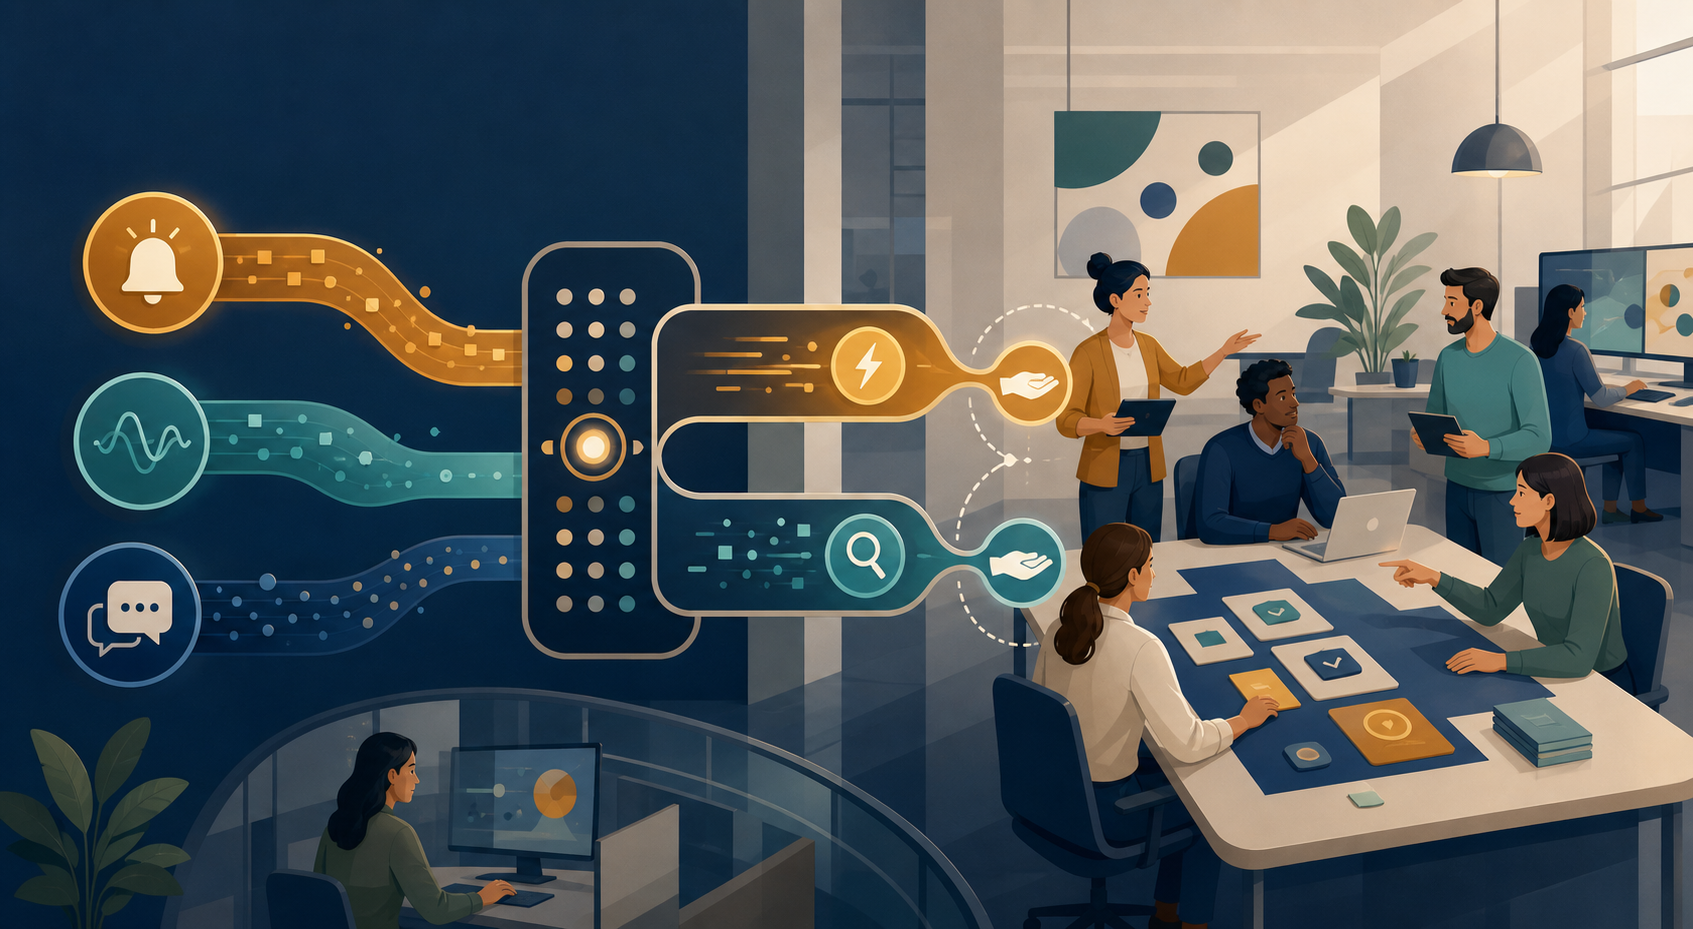
From Customer Signals to Reliable Product Operations
A practical framework for routing support, behavioral, research, and reliability signals into faster response and stronger product decisions.
-
Migrate Analytics Platforms Without Chaos: 7 Proven Lessons to Plan, Move, and Land Cleanly
Migrating analytics platforms doesn’t have to derail roadmaps or erode trust. I share seven battle-tested lessons—shaped by work with Human37 and Amplitude—that help teams align on…
-
AI Inference Economics: Optimize for Value, Not Cost
A practical framework for balancing AI inference cost, latency, and quality against conversion, retention, support demand, and revenue.
-
How I Use Novus, the First Product Agent, to Turn Rapid Releases into Measurable Wins
Rapid releases don’t have to blur what’s working. I use Novus to connect code velocity to customer outcomes with eval-driven development, observability, and continuous discovery—without drowning…
-
Engineering MCP Agents as a Reliable Product Platform
A practical framework for building MCP agent platforms around controlled context, safe actions, measurable reliability, and governed scale.
-
How to Build a Resilient Experimentation Program at Scale
A practical operating model for producing trustworthy decisions through layered evaluation, governed measurement, and reversible delivery at scale.
-
How to Design a Dependable CLI Agent Users Can Trust
A practical framework for building CLI agents with narrow contracts, safe permissions, predictable execution, and measurable reliability.
-
Supercharge Core Web Vitals with Amplitude’s Global Agent: Faster Rankings, Happier Users
Core Web Vitals are a direct lever on user experience and SEO, so I use Amplitude’s Global Agent and Amplitude AI Agents to measure and improve…
-
How to Operate Always-On AI Agents Without Losing Control
A practical operating model for unattended AI agents, covering job design, permissions, task state, failure handling, cost controls, and scaling.
-
Built for Your Biggest Days: How We Engineer Fair, Reliable Scale Without Downtime
Enterprise teams ask sharper questions about scale—and they should. I share how we handle 150k+ requests/sec, shard our source-of-truth data with Vitess and PlanetScale, and reshape…
-
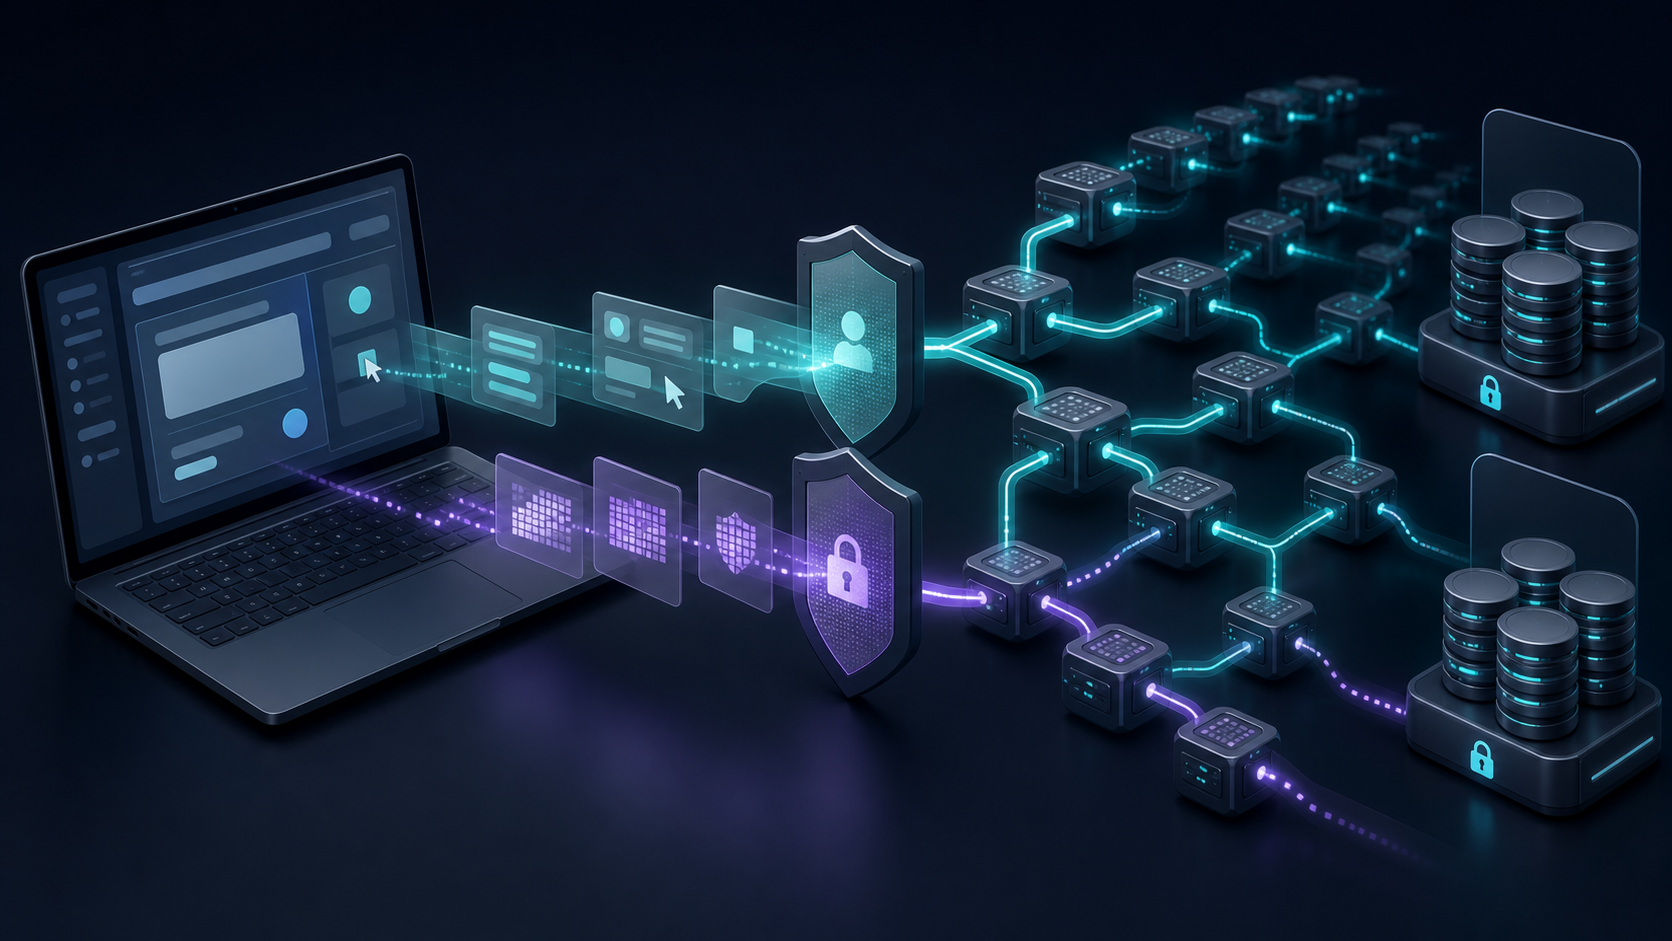
How to Scale Session Replay Without Sacrificing Privacy
A practical operating model for scaling session replay with strict capture controls, performance budgets, targeted sampling, and measurable governance.
-
Developer-First Amplitude Instrumentation You Can Trust
A practical workflow for making Amplitude events reviewable, testable, and trustworthy from tracking-plan design through production monitoring and repair.
-
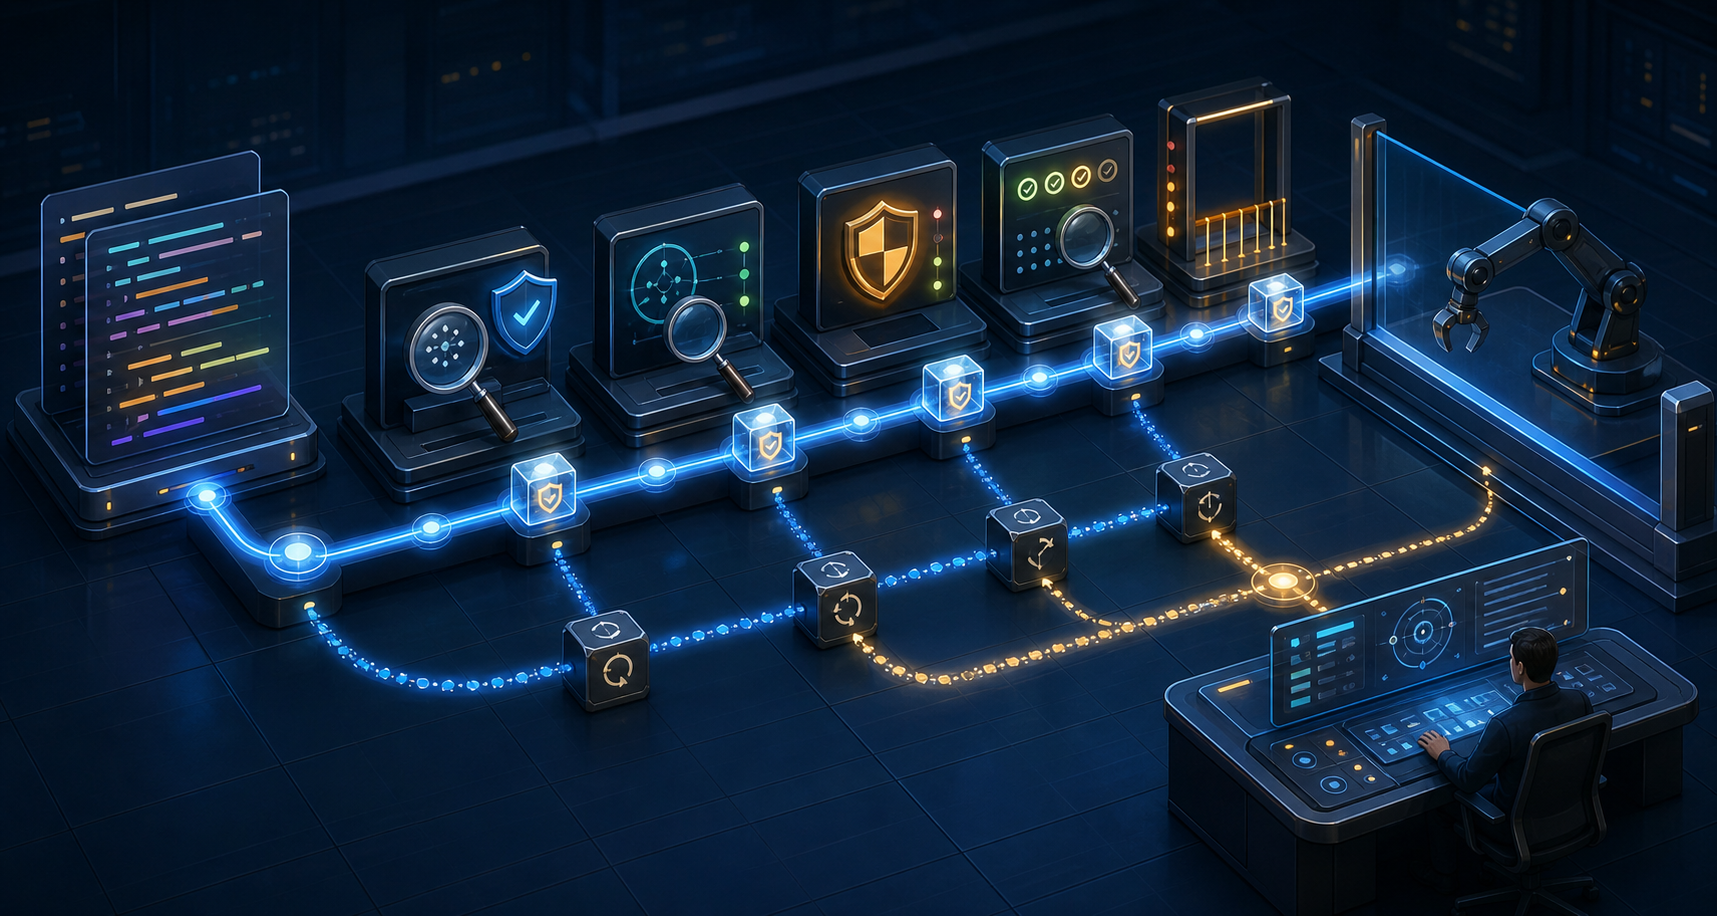
Auditable AI Code Review: A Practical Operating Model
A practical operating model for AI code review that makes approvals explainable, limits autonomy by risk, and improves through production evidence.
Weekly digest
One email a week on AI products, enablement and hiring. No fluff.
Browse topics
- AI Strategy (429)
- Generative AI (113)
- IT Leadership (38)
- Leadership (81)
- Product Management (394)
- Product Management Leadership (373)
- Uncategorized (32)
Work with me
45-minute consultation on AI product strategy, GTM and PM hiring — no charge.