You have seen the demo: an AI system reads technical material, proposes a hypothesis, writes experiment code, reviews the result, and recommends the next run. Now you have to decide whether this is a useful research tool or an autonomous researcher.
Use a stricter test than the demo does. Faster production of hypotheses, code, charts, and explanations is research acceleration. Research autonomy requires something harder: reliable control over what question is being answered, what evidence would falsify the claim, whether the experiment actually produced that evidence, and who remains accountable when the conclusion is wrong.
Define the unit of research before you automate it
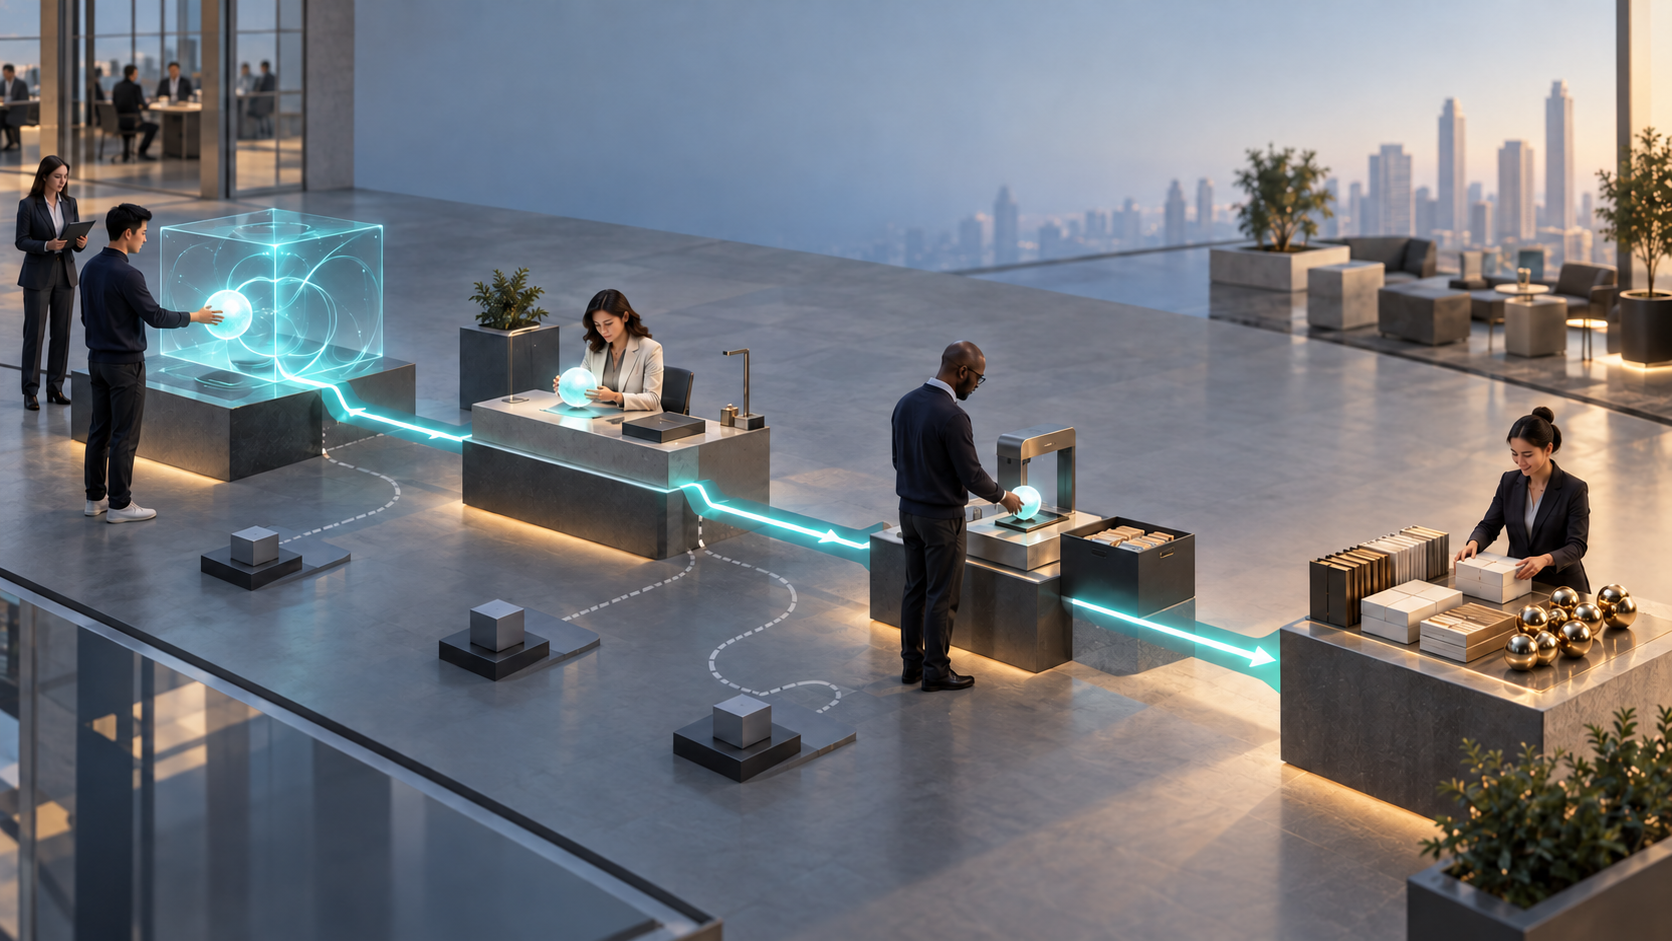
AI research is not a single task. It is a loop with several different kinds of work:
- Frame a question that matters.
- Map relevant prior work and unresolved uncertainty.
- Turn an intuition into a falsifiable hypothesis.
- Choose baselines, data, metrics, and controls.
- Implement and run the experiment.
- Distinguish a real effect from noise, leakage, confounding, or an implementation error.
- Decide whether to replicate, revise, abandon, or extend the idea.
- Communicate the conclusion without overstating what the evidence supports.
An AI system can contribute to many of these activities without owning the loop. That distinction matters because the visible artifacts are concentrated near the middle: summaries, hypotheses, code, experiment logs, and written interpretations. The hardest decisions often sit at the boundaries. Was this the right question? Was the comparison fair? Did the metric capture the intended outcome? Does the result generalize beyond this setup?
Treat the smallest valid unit of research as a package containing a claim, the evidence for it, the conditions under which it holds, the evidence that could disprove it, and a path another reviewer can use to reproduce it. If your AI workflow produces only the claim, you have automated assertion. If it produces the claim and a polished rationale, you have automated persuasion. Neither is the same as discovery.
Watch the failure modes that persuasive demos hide
A credible explanation can arrive before credible evidence
Generative systems are built to produce plausible continuations. Research needs a different behavior: preserving uncertainty when the evidence is incomplete and resisting a conclusion when the result is ambiguous. A useful warning for near-term planning is that AI can claim to have automated AI R&D before the evidence justifies that claim.
Do not accept a narrative as the final artifact. Require every substantive conclusion to point to the exact run, input, configuration, output, and comparison that support it. Label statements as observed, inferred, or proposed. That simple separation prevents a fluent interpretation from quietly becoming an experimental fact.
The system can optimize the proxy while missing the question
An experiment usually turns a broad goal into something measurable. That translation creates a gap. A model can improve the selected score while exploiting an accidental property of the evaluation, weakening performance outside the test, or solving a narrower problem than the team intended.
Write the hypothesis in two forms before execution: the measurable claim and the real-world claim it is meant to represent. Then ask what could make the first improve while the second remains unchanged. Put those failure conditions into the evaluation plan. If the agent is allowed to change the metric, baseline, data filter, or success criterion during the run, treat that as a new experiment requiring approval.
Self-evaluation creates circular confidence
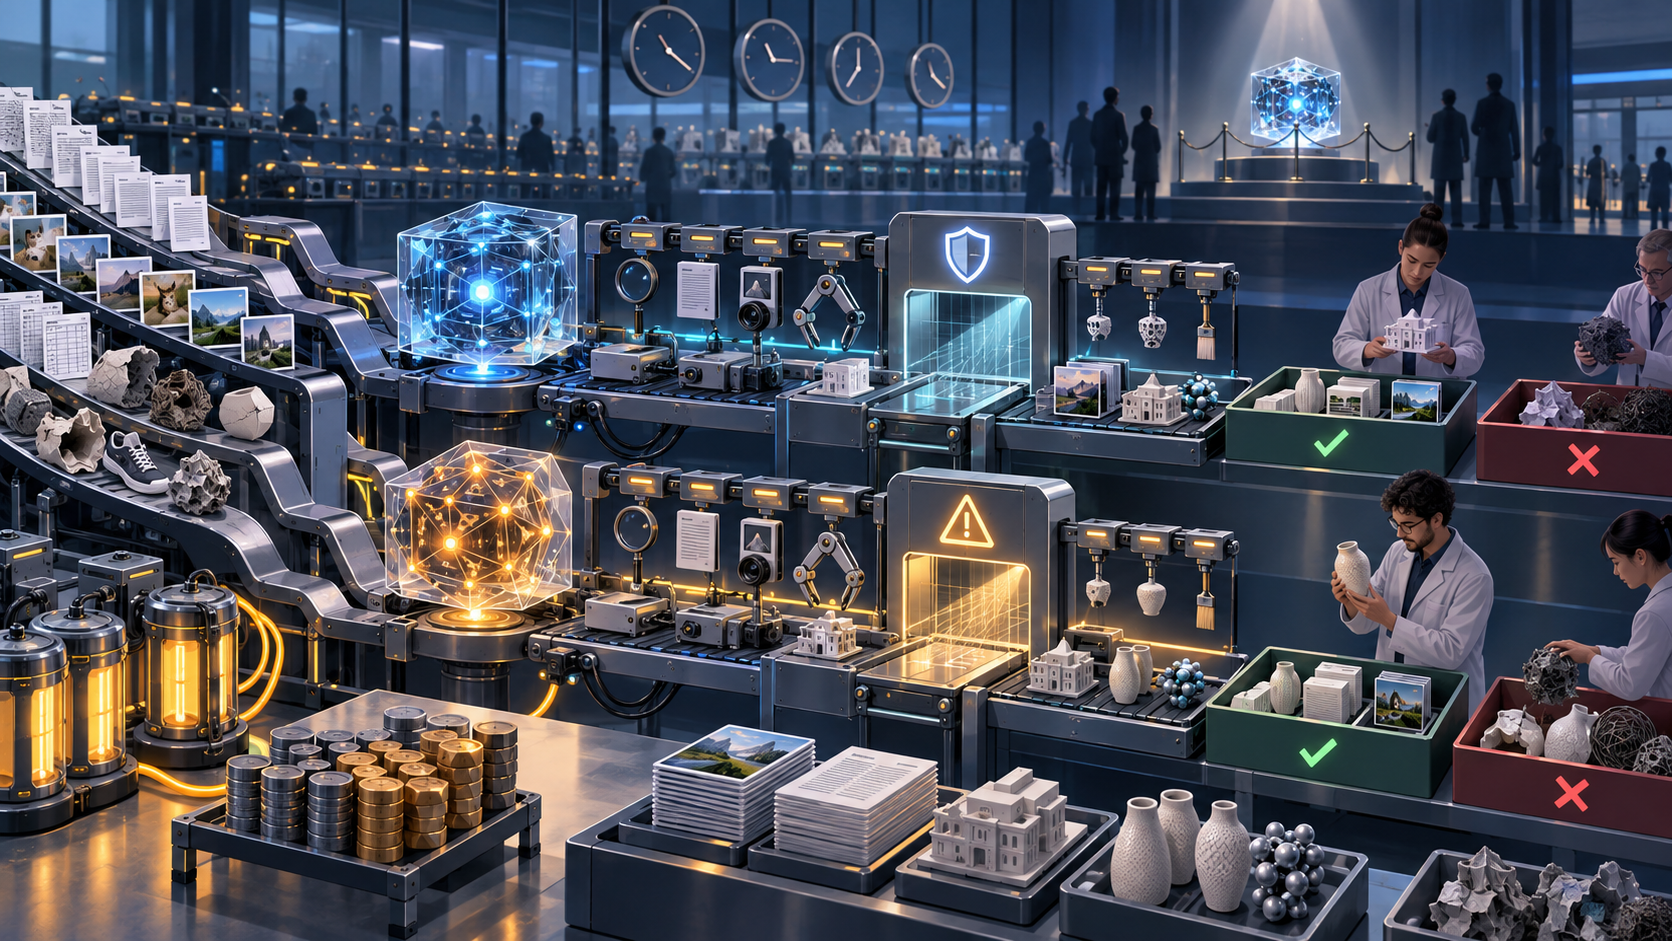
If the same system proposes an idea, implements it, interprets the output, and grades the interpretation, its blind spots can travel through the entire loop. Asking it to critique itself may expose obvious mistakes, but a new prompt does not create independent evidence. A second model can add diversity, yet shared training patterns, similar tools, and the same supplied context can still produce correlated errors.
Independence must come from the evaluation design. Freeze the success criteria before the run. Keep a held-back test where appropriate. Have a reviewer reconstruct the conclusion from raw artifacts without relying on the agent’s summary. For consequential findings, require reproduction through a separately executed path.
Execution success can conceal experimental failure
Code that runs is not necessarily code that tests the hypothesis. A pipeline may complete while using the wrong data split, an unintended default, a mismatched baseline, or a contaminated input. The more experiments an agent launches, the more expensive manual inspection becomes. This creates verification debt: unreviewed outputs accumulate faster than trustworthy conclusions.
Make validity checks part of execution, not a review task postponed until the end. Preserve environment details, data lineage, configuration changes, randomization controls where relevant, logs, failures, and the exact commands required to rerun the work. A result that cannot be reconstructed from its artifacts should not enter the decision record.
Novelty is harder to verify than novelty is to generate
An AI system can produce many variations on an idea. Volume makes originality look abundant, but a plausible new combination may be established, previously rejected, meaningful only under a hidden assumption, or different in wording rather than substance. Failure to retrieve prior work is not proof that prior work does not exist.
Split ideation from novelty review. Ask for competing hypotheses, reasons each idea may fail, and the closest known alternatives. Preserve the search trail and verify important citations against the underlying material. Only call an idea novel after a qualified reviewer has examined both the conceptual distinction and the evidence search.
Set autonomy by reversibility and verifiability
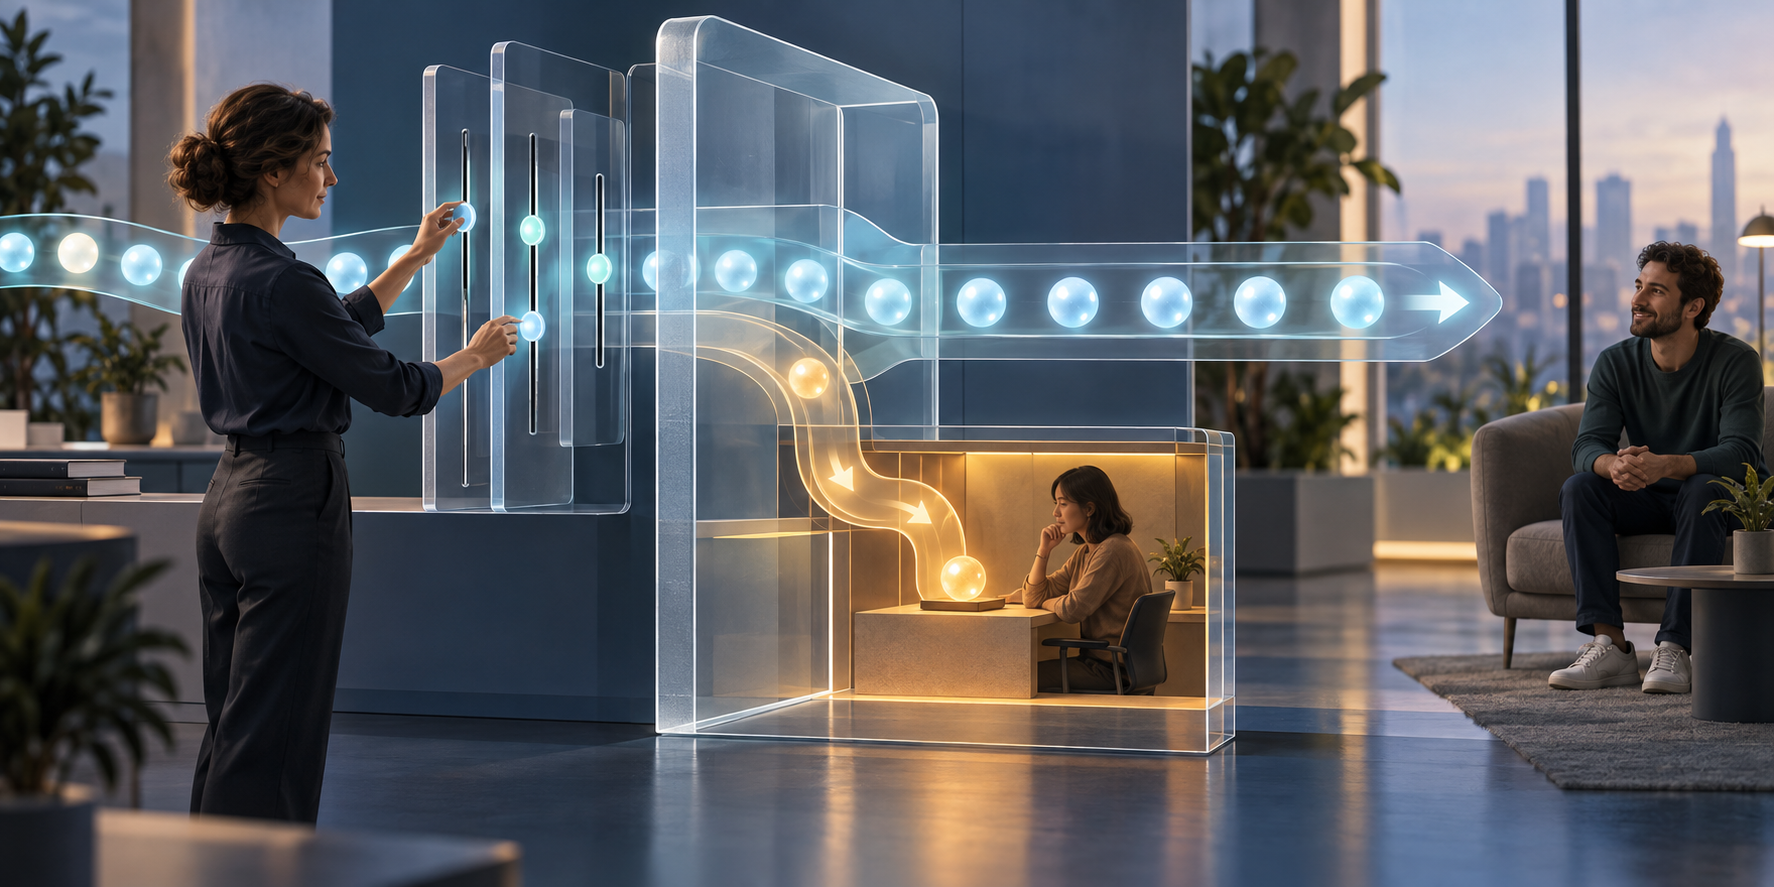
The right question is not whether AI should be autonomous in research. It is where autonomy is safe. Give more freedom when errors are easy to detect, cheap to reverse, and contained within a controlled environment. Require stronger human gates when the work changes the objective, selects the evidence, interprets an ambiguous result, commits substantial resources, or creates an external claim.
| Research activity | Useful AI role | Required gate |
|---|---|---|
| Prior-work triage | Cluster material, extract candidate claims, identify terminology, and draft a search map | Verify consequential claims and citations against the underlying material |
| Hypothesis generation | Propose alternatives, counter-hypotheses, failure mechanisms, and discriminating tests | A researcher selects questions that are meaningful, falsifiable, and worth the cost |
| Experiment implementation | Draft code, configurations, tests, and execution plans | Run in a contained environment; inspect changes, data access, and validity checks |
| Result analysis | Calculate predefined measures, organize artifacts, and surface anomalies | An independent reviewer checks baselines, confounds, exclusions, and alternative explanations |
| Research portfolio decisions | Summarize evidence, uncertainty, options, dependencies, and unresolved questions | An accountable owner decides whether to invest, stop, replicate, or communicate |
Before granting an agent more authority, apply this decision test:
- Can correctness be checked mechanically or through a predefined test?
- Can a failure be contained without corrupting shared data, infrastructure, or the research record?
- Can the action be reversed without losing evidence or creating material cost?
- Are the goal, data, baseline, metric, and stopping rule fixed outside the agent’s control?
- Will someone or something genuinely independent evaluate the result?
- Is responsibility for the decision assigned to a named human owner?
A weak answer should reduce autonomy. This is not a judgment about how intelligent the model appears. It is a control decision based on how observable and recoverable failure will be.
Build an evidence pipeline before an agent loop
An agent loop makes work happen repeatedly. An evidence pipeline makes the resulting claims inspectable. Build the latter first.
- Write a research contract. Record the question, measurable hypothesis, real-world interpretation, baseline, allowed data and tools, expected artifacts, known confounds, stopping rule, and decision owner before execution begins.
- Separate proposal from approval. Let AI generate candidates, but do not let the same run silently choose the question, redefine success, and approve its own answer.
- Maintain an evidence ledger. For each claim, retain its status, provenance, supporting run, configuration, limitations, failed attempts, and reviewer decision.
- Preserve negative results. Agents can repeatedly rediscover an attractive dead end if failures disappear from context. Record what was tried, why it failed, and which assumptions the failure weakened.
- Reproduce from a clean path. A reviewer should be able to recreate the material result from the saved inputs and instructions without depending on hidden conversation state.
- Gate external claims. Publication, product commitments, resource allocation, and statements presented as established findings should remain human decisions.
Measure the system by truth throughput, not output throughput. Experiment count, generated hypotheses, completed tasks, and polished reports mostly measure activity. Better operational measures include the share of claims that survive independent review, the burden required to verify them, the frequency of invalid experiments, the cost of discarded paths, and the time from an initial claim to reproducible evidence.
Start with a bounded workflow in which your team already understands the failure modes. Establish how the current human process performs. Run the AI workflow in shadow mode so its recommendations do not yet control consequential decisions. Compare not only the conclusions, but also missed evidence, invalid runs, review effort, and recoverability when something goes wrong. Expand authority only when the evidence pipeline makes failures visible and containable.
This operating model also changes hiring. As generation becomes cheaper, evaluation becomes more valuable. You need people who can define valid comparisons, recognize confounding, inspect implementations, preserve provenance, and say that an attractive result has not earned confidence. AI fluency matters, but scientific and product judgment remain the control surface.
Key takeaways
- Automating research artifacts is not the same as automating the research loop.
- A trustworthy result needs a claim, evidence, boundary conditions, falsification criteria, and a reproducible path.
- Fluent explanations, self-evaluation, successful execution, and idea volume can all create false confidence.
- Grant autonomy according to reversibility, containment, verifiability, and independence of evaluation.
- Build research contracts, evidence ledgers, reproduction checks, and human decision gates before increasing agent autonomy.
- Measure verified learning and review burden, not the volume of experiments or reports.
For your next AI R&D initiative, choose one bounded research task and write its research contract before choosing the agent or model. If you cannot specify what would falsify the claim, what artifacts must survive, and who independently approves the conclusion, the workflow is not ready for more autonomy. Fix that boundary first; then let AI accelerate the work inside it.
References