A threat report lands with a familiar warning: an adversary is exploiting a product you might use. Your team still has to determine whether the affected version is deployed, whether an attacker can reach it, what controls stand in the way, which detections would fire, and what deserves action first. If those answers take days, an AI-generated summary only helps you read the warning faster.
If you own security strategy, an AI product, or the platform supporting a security operations team, this is the decision in front of you: do you automate an intelligence feed, or do you build a system that connects attacker behavior to your changing environment? The second option is harder, but it is where AI-enhanced threat intelligence becomes operationally useful.
Start with the security decision, not the AI model
Traditional threat intelligence commonly arrives as indicators of compromise, malware signatures, advisories, and descriptions of attacker tactics, techniques, and procedures. That tells you what is happening outside your organization. It does not automatically tell you whether the same activity presents an exploitable path inside your organization.
AI can make existing work faster. It can help normalize intelligence, enrich alerts, summarize reports, prioritize patches, and support first-line triage. These are worthwhile improvements because they reduce manual work and shorten response cycles. But accelerating an existing workflow is different from changing the decision the workflow can produce.
The stronger product requirement is not, “Summarize this threat report.” It is, “Determine whether the described attack can work here, show the evidence, and identify the safest useful response.” That framing forces you to connect external intelligence with assets, identities, software versions, network paths, configurations, controls, and detection coverage.
Define a decision contract before selecting a model or vendor. For each use case, write down:
- Decision: What exact choice will the system help someone make?
- Trigger: What event starts the analysis: a new intelligence item, an environment change, an alert, or an incident observation?
- Required context: Which external and internal facts must be available for a defensible answer?
- Output: Does the user need a ranked queue, an attack path, a detection proposal, a response hypothesis, or an approved action?
- Owner: Who remains accountable for deciding and acting?
- Authority: May the system recommend, draft, request approval, or execute?
- Feedback: How will the system learn whether the recommendation was accepted, rejected, or disproved?
Consider a newly observed exploitation campaign. A weak decision contract asks the AI to extract affected products and indicators. A useful one asks which deployed systems match the affected versions, which are externally or laterally reachable, which protect critical services, which lack compensating controls, and who should remediate them. The intelligence is the trigger. The environment-specific decision is the product.
Give the system both sides of the risk equation
Security teams often maintain two bodies of knowledge. Threat intelligence describes adversary capabilities, targeting patterns, tools, objectives, and preferred techniques. Exposure data describes vulnerable software, misconfigurations, excessive privileges, weak segmentation, and missing detections. When those bodies remain in separate tools and separate teams, an analyst has to reconcile them manually whenever a consequential threat appears.
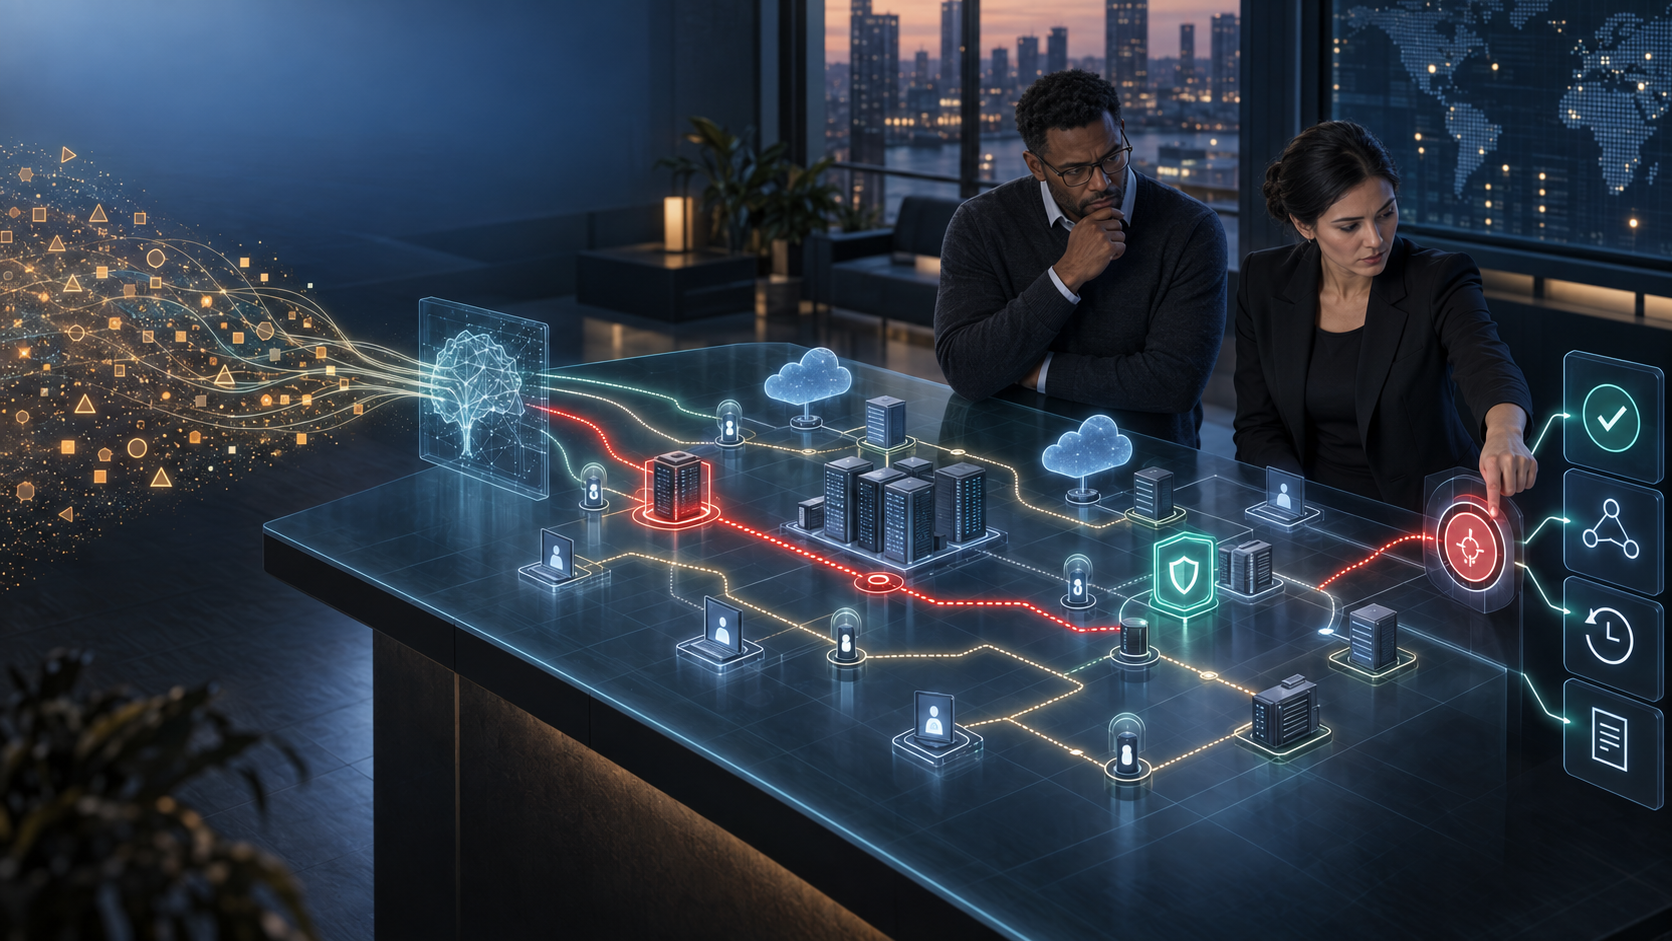
AI is most valuable at that intersection. It can continuously ask, “Where does this adversary’s known tradecraft meet a condition that exists in my environment?” The result should be neither a generic threat brief nor another vulnerability list. It should be an evidence-backed view of applicable risk.
Represent attacker behavior as more than indicators
An indicator can expire while a technique remains useful. Your external context should therefore preserve relationships among the adversary, targeted sectors, objectives, delivery mechanisms, tools, techniques, and known exploitation behavior. It should also retain provenance, observation time, and confidence. Without those fields, the AI cannot distinguish a strong, current observation from a weak or stale inference.
Model the environment as relationships, not a flat inventory
An asset list can tell you that a server exists. It cannot tell you whether a compromised identity can reach that server, whether the server can reach a sensitive data store, or whether a control interrupts the path. Environment context needs relationships among assets, identities, privileges, software versions, vulnerabilities, configurations, network routes, segmentation boundaries, logging coverage, detections, and business-critical services.
This becomes a living exposure model. As software, privileges, configurations, and network paths change, the system can re-evaluate how an attacker could reach a critical asset. Enriching that model with the paths and tools adversaries actually use creates a continuously updated, threat-informed view of exposure, rather than a point-in-time assessment that starts aging as soon as it is delivered.
Make freshness and missing context visible
A sophisticated model cannot recover facts that your systems do not provide. An unknown software version, an incomplete identity graph, or stale network data should appear as an explicit gap, not disappear inside a confident narrative. Every recommendation should show which inputs were used, when they were observed, and which required facts were unavailable.
A practical evidence path looks like this: observed adversary technique, required attack condition, matching internal condition, reachable asset, control or detection gap, potential business impact, and proposed action. If the system cannot construct that path, it should ask for the missing evidence or lower its confidence. This is more useful than producing a longer explanation.
You do not need to centralize every security record before delivering value. Start with the minimum connected context required for one decision contract. For vulnerability prioritization, that might mean exploitation intelligence, deployed versions, reachability, asset criticality, and compensating controls. Add more data only when a real decision repeatedly fails because the context is missing.
Build decision loops around four concrete security jobs
The same intelligence and exposure foundation can support several workflows, but each one needs a distinct output and accountable owner. Treating them as one general-purpose security chatbot blurs those requirements.
| Decision loop | Question to answer | Minimum context | Useful output | Accountable owner |
|---|---|---|---|---|
| Vulnerability prioritization | What should be remediated first? | Exploitation behavior, adversary interest, deployed version, reachability, asset criticality, and compensating controls | Ranked remediation queue with evidence, uncertainty, and recommended treatment | Vulnerability or asset owner |
| Detection engineering | Which likely attacker behavior can we not detect? | Relevant techniques, available telemetry, existing detections, and known coverage gaps | Prioritized coverage gap and a testable candidate detection | Detection engineer |
| Attack-path management | Which viable route to a critical asset matters most? | Identities, privileges, vulnerabilities, configurations, segmentation, and critical assets | Threat-relevant path with the most effective breakpoints | Security architect or platform owner |
| Incident response | What is the attacker likely to attempt next? | Current telemetry, observed techniques, environment state, and known adversary patterns | Ranked hypotheses, evidence to collect, and bounded response options | Incident commander |
Prioritize vulnerabilities by applicability, not severity alone
A theoretical severity score cannot tell you whether an adversary is using the weakness against your sector, whether the vulnerable component is deployed, or whether an attacker can reach it in your environment. AI-enhanced prioritization can combine those facts and move the weaknesses at the intersection of intent, capability, and exposure to the front of the queue.
Do not replace one opaque score with another. For every priority change, show the contributing evidence: observed exploitation, relevant adversary behavior, matching version, exposed route, critical dependency, missing control, and uncertainty. A vulnerability with incomplete exploitation data should be marked as uncertain rather than silently treated as safe. Absence of intelligence is not proof that exploitation cannot occur.
Turn detection gaps into tested coverage
Threat intelligence becomes useful to detection engineering when it identifies techniques relevant to your environment and compares them with the telemetry and rules you actually have. The system can then prioritize a coverage gap and draft candidate logic. The deliverable is not generated code by itself. It is a detection that has known data dependencies, test evidence, an owner, and a controlled deployment path.
Run generated detections against representative telemetry before using them for paging or automated response. Check that the required fields exist, the logic identifies the intended behavior, and ordinary administrative activity does not overwhelm the signal. A plausible rule that depends on telemetry you do not collect creates imaginary coverage.
Use attack paths to choose the right control
A list of weaknesses encourages teams to fix items one by one. An attack path shows how multiple ordinary conditions can combine: an exposed service enables entry, an overprivileged identity enables movement, and weak segmentation exposes a critical system. Threat intelligence helps rank paths by the routes and tools relevant adversaries are known to favor.
The useful output is a breakpoint, not just a visualization. Ask which single change – patching a reachable component, removing a privilege, closing a route, or adding a detection – interrupts the most consequential path with the least operational disruption. Assign that change to the team that can make it and recalculate the path after completion.
During an incident, predict without pretending certainty
Experienced responders use observed behavior to anticipate credential access, persistence, lateral movement, and collection attempts. AI can make that threat-informed reasoning available earlier by matching partial telemetry and configuration changes with known patterns. That can help a team collect the right evidence and protect the next likely target before another alert appears.
Present these outputs as ranked hypotheses, not definitive attribution. Each hypothesis should include supporting observations, contradictory evidence, the next fact that would strengthen or weaken it, and a bounded response option. This prevents a familiar-looking technique from locking the team onto one adversary or one attack path while contrary evidence is still emerging.
Set AI autonomy by consequence and reversibility
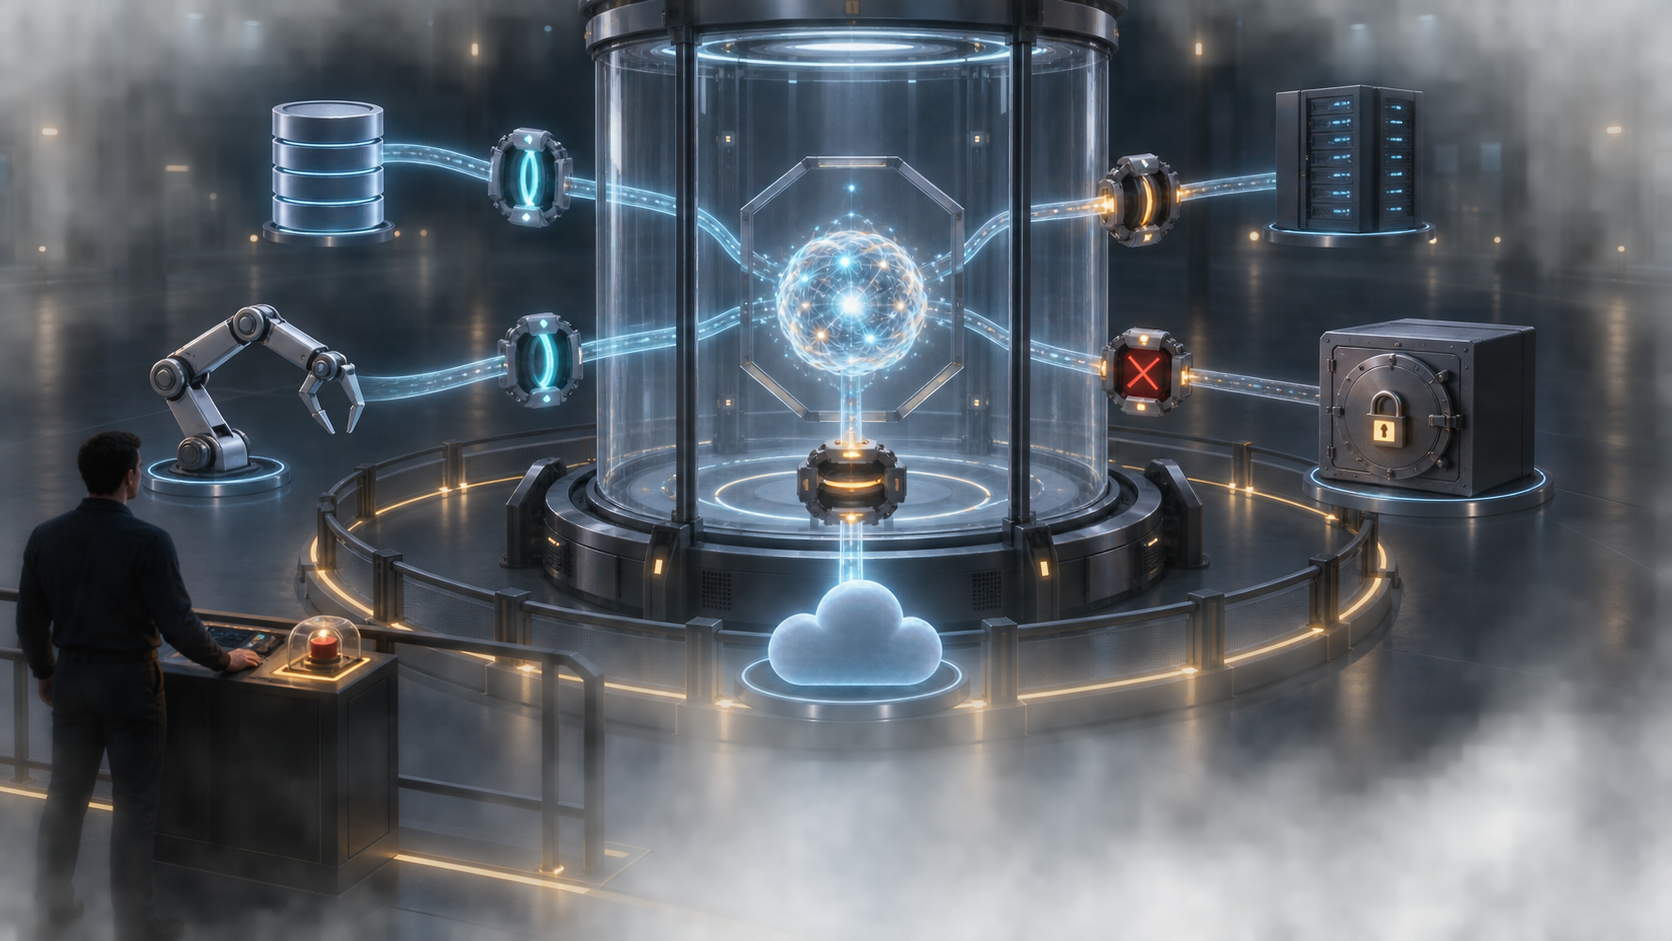
A fluent recommendation is not evidence, and a fast action is not necessarily a safe action. The right autonomy level depends on what happens when the system is wrong and whether the action can be reversed cleanly.
- Recommend: Rank vulnerabilities, identify likely detection gaps, propose attack-path breakpoints, or suggest incident hypotheses.
- Draft: Prepare queries, candidate detection rules, remediation tickets, change requests, and response plans for review.
- Act after approval: Create an assigned ticket, launch an approved validation, deploy a tested detection, or execute a reviewed playbook.
- Auto-execute: Reserve this for pre-authorized, observable, narrowly scoped, and reliably reversible actions with clear rollback conditions.
Do not allow unreviewed AI to disable identities, isolate production systems, block broad traffic ranges, delete evidence, rotate critical credentials, or change security controls during an incident. A mistaken action can create an outage, destroy investigative context, or alert an intruder before responders are ready. The safer pattern is to present the action, supporting evidence, expected blast radius, validation step, and rollback plan to the incident commander.
Package each recommendation in an evidence envelope:
- The decision or action being proposed.
- The external and internal observations supporting it, including timestamps and provenance.
- The evidence path connecting attacker behavior to the exposed condition.
- Confidence, assumptions, missing data, and plausible alternatives.
- The expected security benefit and potential operational consequence.
- The validation required before execution.
- The owner, approval boundary, and rollback method.
Apply the same discipline to system access. Give the AI only the data and execution permissions required for its current decision contract. Keep its reads, recommendations, approvals, tool calls, and outcomes auditable. If a user cannot reconstruct why a consequential recommendation appeared, the system is not ready for greater autonomy.
Human review should also be substantive. Asking an overloaded analyst to approve a dense recommendation in seconds merely transfers accountability without improving control. Design the review around the evidence that could change the decision, and make rejection or correction easy to record. Those corrections become essential feedback for both the model and the surrounding data pipeline.
Roll out one explainable decision loop at a time
The fastest credible path is a narrow workflow with measurable consequences, not an enterprise-wide assistant. Choose a recurring decision where external intelligence already matters, internal context is obtainable, and a named owner can judge the output.
- Baseline the current decision. Capture how the team reaches it now, what evidence it uses, where work waits, which handoffs fail, and what errors create real consequences.
- Implement the decision contract. Connect only the external and internal context needed to produce the agreed output. Label missing or stale fields instead of filling them with inference.
- Run in shadow mode. Let the system produce recommendations without changing queues, detections, or controls. Compare its priorities and evidence with the accountable team’s decisions.
- Test disagreement, not just agreement. Review cases where the AI raised an item humans dismissed, missed an item humans escalated, or reached the right answer for the wrong reason. These cases reveal data and reasoning failures that average accuracy can hide.
- Introduce bounded action. Start with drafting and ticket creation. Add approval-based actions only after the evidence package and rollback process work reliably.
- Expand by adjacent decisions. Reuse the trusted context model for detection, attack-path analysis, or incident support, but give each workflow its own output, owner, evaluation, and autonomy boundary.
Measure whether decisions improve, not whether the AI looks busy. Useful operating measures include:
- Time from receiving relevant intelligence to determining whether it applies to your environment.
- Time from identifying a relevant technique to producing and validating detection coverage.
- Time that a threat-relevant, reachable weakness remains exposed.
- Share of recommendations that include current evidence, explicit uncertainty, and an accountable owner.
- Acceptance, override, and reversal patterns, including the reasons behind them.
- Operational harm caused by incorrect recommendations or actions, such as unnecessary disruption or avoidable analyst workload.
Counts of reports summarized, indicators ingested, or chat sessions completed are activity metrics. They can help operate the platform, but they do not establish that threat intelligence changed a security outcome. Set improvement targets from your own baseline because decision complexity, environment volatility, and organizational risk tolerance differ.
Key takeaways
- AI-enhanced threat intelligence creates value when it maps attacker behavior to your actual assets, identities, paths, controls, and detection gaps.
- The quality and freshness of internal context will usually constrain the decision before model sophistication does.
- Design outputs as owned security decisions with evidence, uncertainty, and a next action – not as summaries or generic risk scores.
- Use AI to recommend and draft broadly, but grant execution authority according to consequence, reversibility, and observability.
- Judge the program by decision latency, validated coverage, reduced relevant exposure, and avoided operational harm.
Take the most recent high-priority threat report your team handled and try to trace one claimed technique to a matching internal condition, a reachable asset, a control gap, an owner, and a reversible next step. Wherever that trace breaks is the next capability to build. That exercise will give you a more useful AI roadmap than starting with a model demonstration.
References