
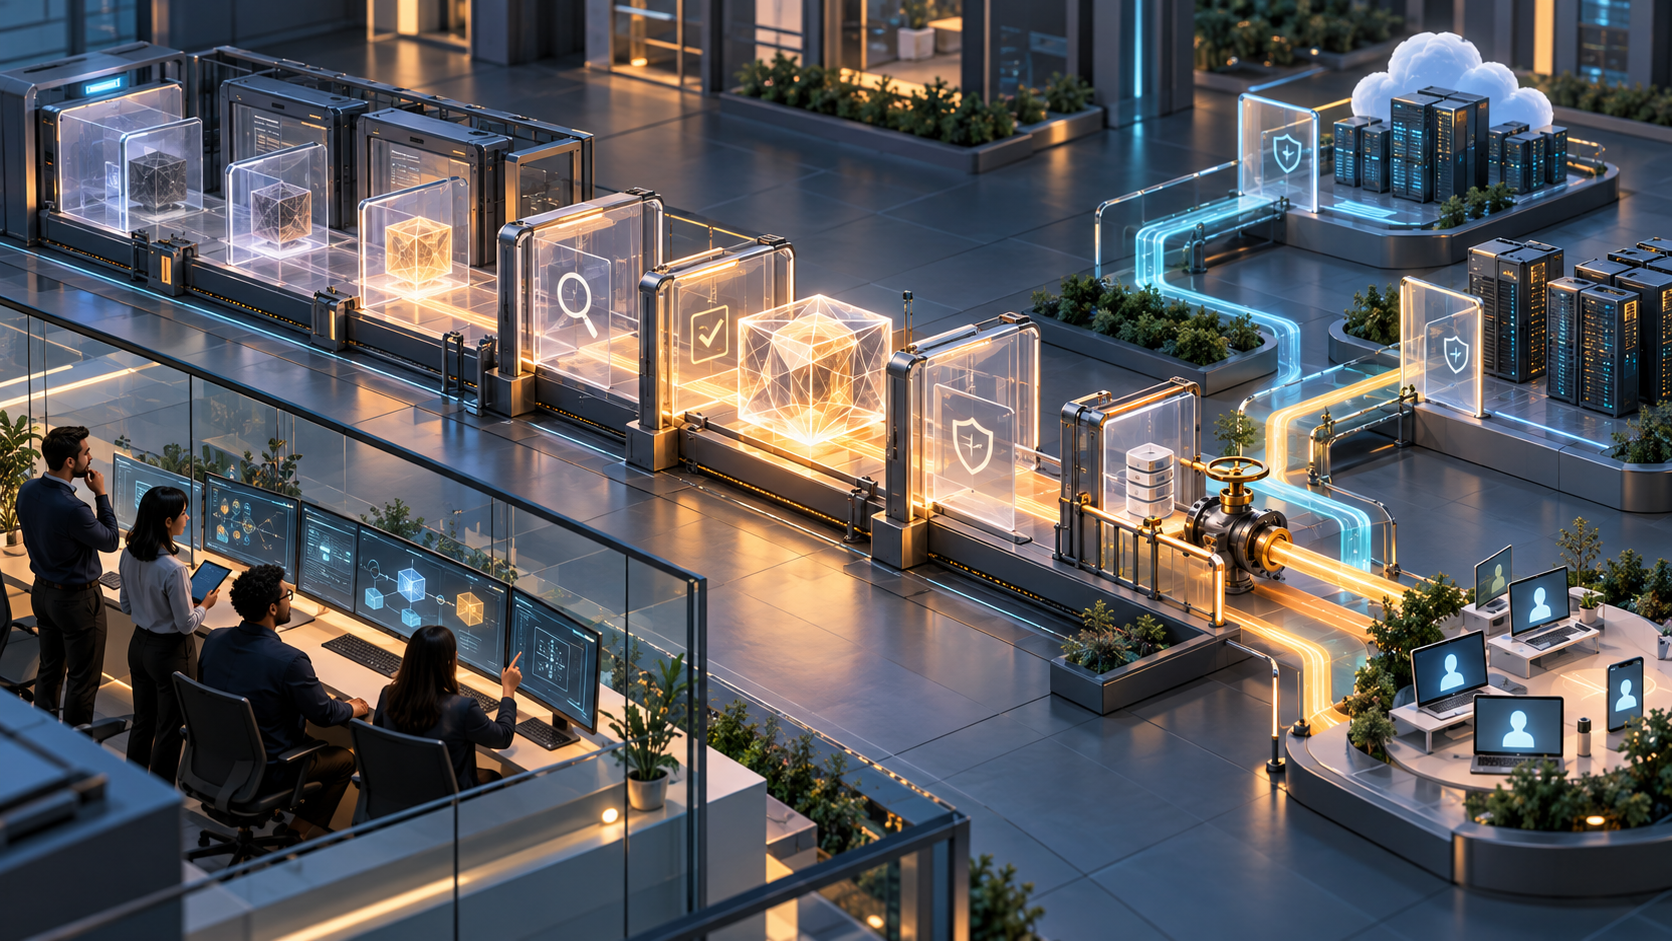
Your AI pilot performs well in a steering-committee demo. The harder decision is whether you can expose it to real employees or customers without turning every prompt edit, model update, data change, and traffic spike into a fresh risk event.
I use a stricter definition of production-ready: the system’s value, quality, failure behavior, cost, and adoption are measurable, and a harmful change can be contained before it spreads. That means treating evals, safe rollouts, audit trails, cost limits, and failure testing as part of the product rather than work that begins after launch.
Key takeaways
- A production launch needs an explicit release contract covering user value, quality, risk, operations, economics, and adoption.
- Evaluate every material change against a maintained set of real tasks and known failure cases before it reaches users.
- Put prompts, models, retrieval settings, tools, and policies behind controlled rollout and tested rollback paths.
- Record enough context to reconstruct each consequential decision without indiscriminately storing sensitive content.
- Measure adoption as repeated, successful completion of a user job, not access, logins, or raw AI request volume.
Make readiness a release contract, not a launch opinion
Teams often ask whether the model is good enough. That question is too broad to produce a responsible release decision. Good enough for drafting an internal note is not good enough for sending a customer response, changing a record, approving a transaction, or taking an action that is difficult to reverse.
Start by defining the exact job, user, operating boundary, and consequence of failure. Then create a short release contract. Each row below needs an owner, a measurable threshold, evidence, and a predefined response when the threshold is missed.
| Gate | Required artifact | Evidence to proceed | Reason to stop |
|---|---|---|---|
| User value | A named user, job, workflow, and observable completion signal | The feature helps the intended user complete the intended job inside the real workflow | The team can measure usage but cannot tell whether the job was completed |
| Quality | A golden evaluation set, scoring rubric, baseline, and promotion rule | The candidate meets its declared bar without an unacceptable regression in a critical slice | An aggregate score hides a failure for a high-consequence task, tenant, language, or data condition |
| Risk | Prohibited behaviors, permission boundaries, refusal rules, and an escalation path | Severe failures are blocked or routed to human review before an action is taken | The system can bypass an authorization, expose restricted data, or perform an unreviewed sensitive action |
| Operations | Versioned configuration, feature flag, fallback, rollback owner, and incident trigger | The candidate can be isolated, disabled, and replaced without breaking the core workflow | Recovery depends on editing a live prompt, waiting for a deployment, or finding an available specialist |
| Economics | Cost attribution and a policy enforced before model or tool calls | Spend is visible by tenant, user, feature, variant, and outcome, with a safe response to a breached limit | The first reliable cost signal arrives in an undifferentiated monthly invoice |
| Adoption | An eligibility definition, activation event, success event, and repeat-use view | Eligible users repeatedly complete a valuable job with acceptable rework and escalation | Provisioned access or request volume is being reported as customer value |
The release contract should be narrower than the product vision. Name the permitted tenants, roles, data domains, actions, and fallback behavior. If the initial release can draft but not send, say that. If it may search approved knowledge but not open the public web, make that a technical control rather than a sentence in a launch document.
Risk should change the release bar. A suggestion that a trained employee reviews can tolerate different failure behavior from an autonomous action. Customer-visible claims, access to sensitive records, financial consequences, and irreversible changes require tighter permissions, stronger deterministic checks, and a human decision point where the downside warrants it.
This contract also exposes weak pilots early. If you cannot name the success event, you are testing novelty rather than value. If you cannot identify a fallback, you have designed a dependency rather than a resilient feature. If nobody owns a stop decision, your rollout plan is incomplete.
Make evaluation the gate for every AI change
Open-ended model behavior cannot be covered by conventional unit tests alone. A production system needs evaluation cases, deterministic checks, calibrated model-based judging, and a CI gate that can reject a bad candidate before it is merged or promoted.
Measure the current system before improving it. A baseline tells you which failures already exist and prevents a new prompt or model from receiving credit for fixing an easy case while quietly damaging a critical one. Preserve results by evaluation-set version, system version, and relevant slice so that the comparison can be reproduced.
A useful golden-case record contains enough information to explain both the expected behavior and the consequence of getting it wrong:
- A stable case identifier and a plain-language description of the user job.
- The input, permitted context, user role, and any setup required to reproduce the case.
- Required answer traits, prohibited traits, and deterministic assertions where they apply.
- A risk or severity label that influences whether failure blocks a release.
- The scoring rubric, expected evidence, and reason the case belongs in the set.
- Metadata for meaningful slices such as workflow, tenant type, language, document condition, or tool path.
- The originating failure or requirement, plus an owner who can resolve ambiguity in the expected behavior.
Populate the set with normal user jobs, boundary conditions, known bad outputs, retrieval failures, permission failures, malformed tool responses, and cases that should be refused. After launch, every material incident and repeated correction is a candidate for the intake process. Reproducing a failure in the evaluation set before fixing it turns an incident into a permanent regression check.
Run cheap, deterministic checks first. Validate response structure, required fields, citations or evidence when the workflow demands them, permission boundaries, forbidden actions, tool arguments, and output formats. These checks are fast and explainable. They should not be replaced by a model judge when a rule can decide the result directly.
Use rubric-based judging for qualities that require interpretation, such as correctness, relevance, completeness, and faithfulness to retrieved material. Version the judge, prompt, and rubric. Calibrate the judge against human ratings, review disagreement, and keep uncertain or high-consequence cases in a human review path. A judge score is an instrument, not ground truth.
The release report should show the candidate beside the production baseline. Include overall results, critical slices, newly passing cases, newly failing cases, latency, and cost. Do not let a higher average conceal a severe regression. Promotion rules should identify which failures are absolute blockers and which can be accepted by the named owner with a recorded rationale.
Finally, keep offline quality separate from live value. An answer can satisfy a rubric and still create unnecessary rework. After the offline gate, measure whether users accept, correct, abandon, escalate, or reverse the result. Those behaviors become the next inputs to product discovery and evaluation-case intake.
Release prompts and models like production software
A prompt change can alter customer-visible behavior without changing application code. The same is true for model versions, retrieval parameters, rerankers, system instructions, tool schemas, memory rules, safety policies, and knowledge indexes. Treat them all as versioned release inputs.
Create an immutable manifest for each candidate. It should identify the application build, prompt and policy versions, model and provider configuration, retrieval and reranking settings, tool definitions, knowledge snapshot, evaluation-set version, scorer version, feature flag, and fallback. That manifest gives operations a concrete answer when someone asks, “What produced this output?”
Use a controlled promotion path:
- Run the candidate against the frozen promotion set and the growing diagnostic set. Stop if it misses a blocking rule.
- Exercise the complete path in a production-like environment, including empty retrieval, tool failure, timeouts, denied permissions, budget exhaustion, and unavailable dependencies.
- Expose the candidate only to an identified cohort through a feature flag. Keep the current production version available.
- Compare the candidate with the baseline on declared quality, outcome, latency, cost, refusal, escalation, and correction measures.
- Increase exposure only after the required evidence is available. Record who approved the change and which manifest was promoted.
- Rollback when a predeclared stop condition fires, then preserve the trace and add the failure to the evaluation intake queue.
A/B testing belongs after the minimum quality and risk gate. It can help you compare workflow design, user value, latency, or alternative experiences with statistical confidence. It should not be used to discover whether an unqualified variant violates a known safety or authorization boundary. Every exposed variant must already satisfy the non-negotiable release rules.
Feature flags are useful only when rollback is operational. The rollback path must restore a known-good prompt, model configuration, retrieval setup, policy, and tool contract together. Reverting application code while leaving a changed index or prompt in place does not reproduce the previous system.
Set the rollback objective according to the consequence of exposure, then rehearse it. A production reliability design can target rollback in under 30 seconds, but the important product decision is what happens during that interval. A safe fallback may use a stable model, disable the AI action while preserving the underlying workflow, route work to a review queue, or return a bounded non-AI response. Choose it before the incident.
Also define circuit-breaker triggers. Provider errors, abnormal latency, repeated tool failures, unexpected refusal changes, cost acceleration, and quality anomalies should be able to stop or degrade the AI path without taking down the surrounding product. The user still needs a way to complete the job when the model path is unavailable.
Connect auditability, cost control, and adoption
Production AI is difficult to operate when product analytics, model traces, incident records, and invoices describe different units of work. Use a shared request and session identity so that a user outcome can be connected to the system decisions and cost that produced it.
For each consequential request, record an audit event with the identifiers and versions needed for reconstruction:
- Request, session, tenant, feature, and experiment-variant identifiers.
- User role and authorization scope, without copying unnecessary personal or sensitive data into the event.
- Application, prompt, model, policy, retrieval, index, and tool versions.
- Retrieved-record identifiers, tool calls, permission decisions, and fallback decisions.
- Output disposition: delivered, refused, blocked, corrected, escalated, abandoned, or reversed.
- Latency, usage, attributed cost, error state, and the final business or workflow event when it becomes available.
Do not interpret auditability as permission to store every raw prompt and response indefinitely. Use data minimization, redaction, access controls, and retention rules appropriate to the workflow. Store stable references when they are sufficient. Involve privacy, security, and legal owners where records contain regulated, contractual, or sensitive information.
The audit write path should avoid adding unnecessary latency to the user interaction, while still detecting lost or incomplete events. Tamper-evident techniques such as hash chaining can make later modification detectable. Session replay and traces then help an operator reconstruct the sequence of retrieval, model, policy, and tool decisions rather than guessing from the final text alone.
Cost control should happen before every external call, not after finance receives the bill. The policy layer should check the tenant, feature, user or service identity, allowed model and tool, remaining budget, and request class. When the request would breach policy, the response is explicit: reject it, use a cheaper approved path, reduce optional work, or invoke the defined fallback. Do not silently change behavior in a way that invalidates quality or compliance assumptions.
Attribute spend to the same product units used to measure value. Cost per request is useful for debugging, but it does not answer whether the request accomplished anything. Pair it with successful job completion, rework, escalation, and retention in the workflow. A cheap output that creates manual cleanup can be more expensive than a costlier output that finishes the job.
Adoption needs the same discipline. Enterprise product builders have to connect AI adoption with measurable customer value. Access, page views, chatbot opens, and prompt counts are exposure signals. They do not establish that the feature helped.
Build the adoption funnel around the real workflow:
- Eligible: the user has the right role, data, permission, and job to perform.
- Reached: the user encounters the capability at the point where the job occurs.
- Attempted: the user gives the system a valid task rather than opening it accidentally.
- Successfully completed: the task reaches its workflow-specific success event within the required quality and risk boundary.
- Repeated: the user returns for another eligible task and succeeds again.
- Embedded: successful use persists without unacceptable correction, escalation, reversal, latency, or cost.
Define success in the product’s own language. For a drafting feature, measure whether the draft is accepted and how much rework it needs. For retrieval, measure whether the user can proceed with supported evidence rather than immediately searching again or escalating. For an action-taking agent, measure whether the intended state change completes, remains within permission, and is not reversed because the action was wrong.
Review operations and adoption together. A practical release review examines new failures, evaluation regressions by slice, refusals, fallbacks, latency, cost-policy interventions, successful completion, corrections, escalations, and the largest funnel drop. End with an explicit decision to promote, hold, restrict, or roll back, plus an owner for every unresolved blocker.
This is also where you decide what not to scale. If discovery is weak but successful users retain, improve placement and onboarding. If attempts are high but successful completion is low, fix the product before driving more traffic. If completion looks healthy while correction, reversal, or escalation rises, your success event is too shallow. If value is real but unit economics fail, change the architecture, model routing, or scope before expanding access.
Choose a live AI workflow and complete its release contract before increasing exposure. Add its consequential failures to the evaluation set, put every behavior-changing input under version control, test the rollback, emit the audit event, and enforce the cost policy before the next call. Scale only when you can show what value occurred, what it cost, what failed, and how quickly you can contain the next bad release.
References
- Pendo — Enterprise AI adoption: lessons from Anthropic’s IPO
- AI Engineering Works — Start here: AI Reliability Engineering






