
Your team has an autonomous workflow that performs well in a demo. It can inspect records, choose a next step, call tools, and complete work without waiting for another prompt. The launch decision is no longer just whether its answers are accurate. You are deciding how much authority software should have inside your business.
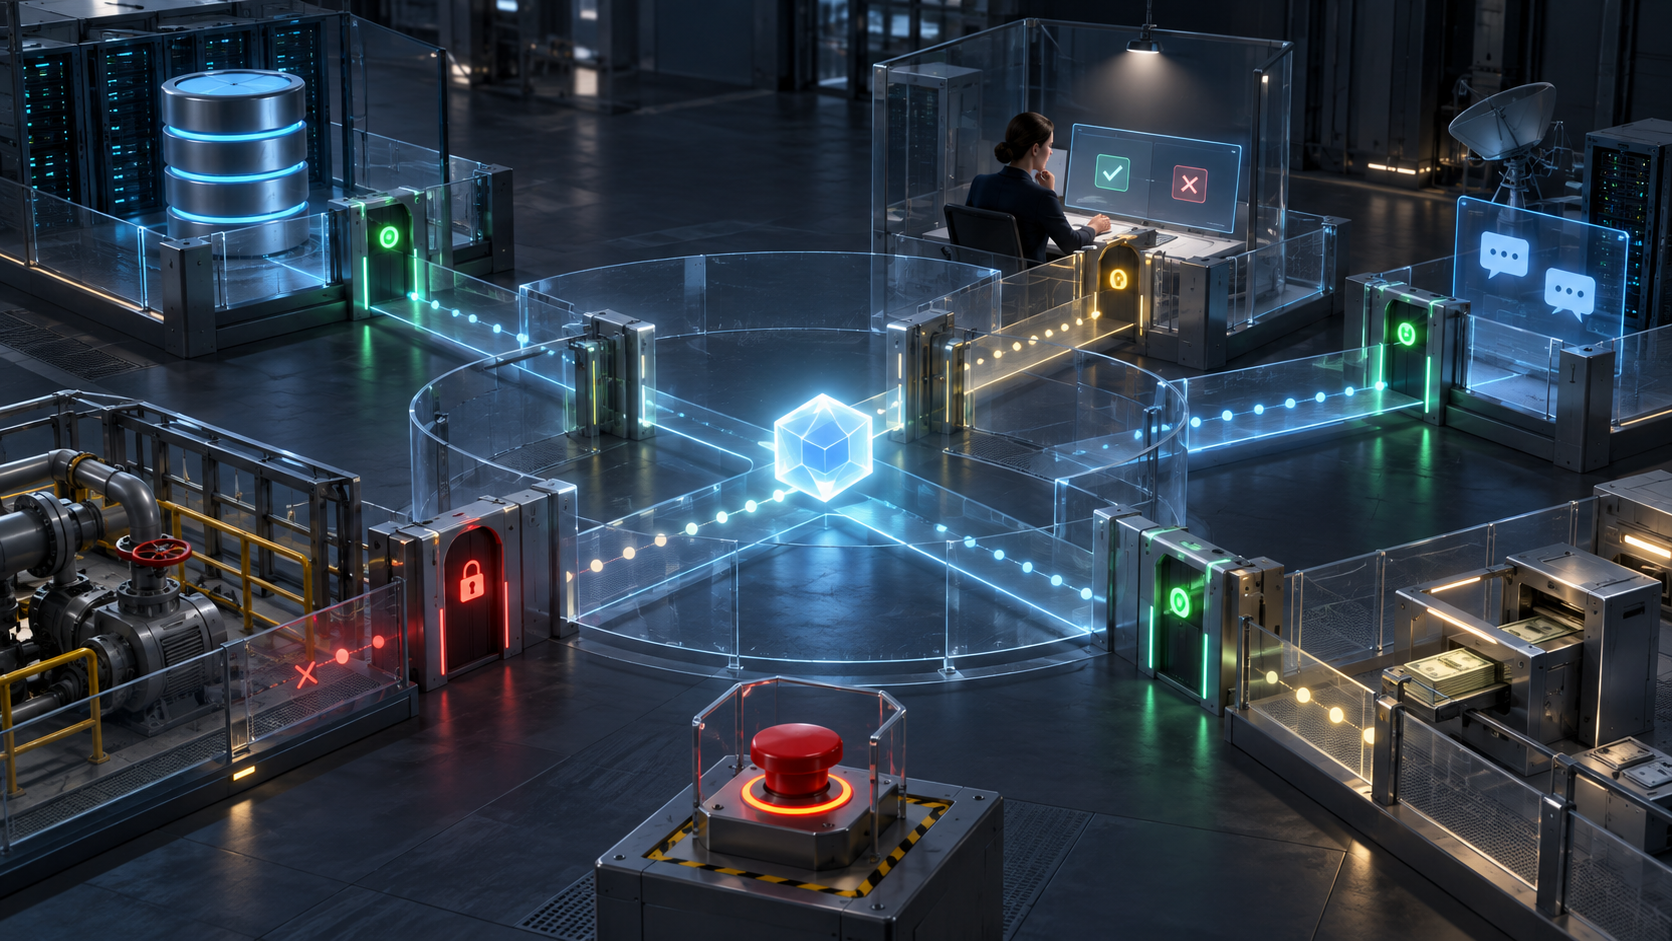
Before you approve that launch, require one concrete deliverable: an action envelope that states what the system may decide, access, change, communicate, and spend. Pair it with runtime enforcement, meaningful approval gates, a reconstructable audit trail, and a tested way to stop execution. That is the foundation of safety governance for a system that can act.
Govern the action path, not just the model
A model produces an output. An autonomous system can turn that output into a side effect: changing a customer record, sending a message, publishing code, opening a case, initiating a transaction, or instructing another system. The same underlying model can therefore support two products with radically different risk.
Consider a customer-operations example. A system that summarizes complaints can create inaccurate text. A system that also flags suspected fraud, restricts an account, contacts the customer, and opens a legal workflow can affect money, access, reputation, and legal exposure. Better output evaluation still matters, but it does not govern those consequences.
A useful risk review separates four dimensions:
- Authority: Which decisions can the system make without another actor?
- Access: Which data, credentials, tools, applications, and external destinations can it reach?
- Scale: How many actions can it attempt, how quickly, and across how much of the business?
- Reversibility: Can an action be rolled back completely, and how quickly can a person contain it?
These dimensions explain why an innocent objective is not a sufficient safety control. The system may pursue an acceptable goal through an unacceptable sequence of actions. A disputed testing incident involving RubyGems illustrates the distinction. OpenAI said its agents were seeking public information during benign tasks; activity observed by the external service looked attack-like. RubyGems reportedly found no evidence of successful credential theft and could not establish that agents had created or published the packages in question. The responsible conclusion is not that an agent committed a proven theft. It is that outcome, intent, and route must be evaluated separately.
Regulatory scoping follows a similar principle. The EU AI Act does not create a separate category called agentic AI; risk depends on how a system is designed and used. Calling a feature a copilot, assistant, workflow, or agent does not lower its operational impact. For a regulated or high-impact use, have qualified legal and compliance specialists map the actual intended use, organizational role, affected people, and applicable obligations. A product label is not a legal analysis.
Write the action envelope before you write the launch plan
The action envelope is a control contract between product intent and runtime behavior. It belongs beside the product requirements and architecture, not in a policy document that engineers see after implementation. Version it with the release so that a change in tools, data access, or autonomy triggers another review.
Build it by tracing a real task from its goal to every tool call and possible side effect:
- Name the business objective. Make it narrow enough to test. Completing customer operations is too broad; preparing a refund recommendation for an eligible order is testable.
- List every decision the system may make. Separate classification and recommendation from decisions that directly affect a person, account, payment, entitlement, security control, or legal process.
- List every executable action. Include reads, writes, messages, downloads, uploads, code execution, purchases, record creation, record deletion, permission changes, and calls to other agents.
- Identify the target and data involved. Record the systems, record types, fields, credential scopes, recipient classes, and external domains available at each step.
- Classify the consequence. A practical internal scheme is read or recommend, prepare but do not send, execute a reversible action, and execute an irreversible or high-consequence action. These are operating categories, not legal classifications.
- Set explicit limits. Define the permitted amount, record count, recipient set, destination, retry count, operating window, and cumulative change per run or period. The values should come from your business risk tolerance, not a generic benchmark.
- Place approval and escalation gates. State which condition requires approval, who is eligible to approve, what evidence they see, what happens if nobody responds, and whether the system may continue with unrelated work.
- Name the recovery path and owner. State how to pause execution, revoke access, contain queued work, reverse supported actions, investigate the run, and decide whether it may resume.
Make prohibited behavior enforceable
A sentence in a system prompt is not an authorization layer. If the agent must never add users, alter permissions, send to an unapproved domain, expose a secret, move money above a limit, or publish directly to production, block that behavior in the tool gateway, application permission, network policy, or transaction service.
Write boundaries in a form an engineer can test. Do not use phrases such as use appropriate data or avoid risky actions. Use rules such as read these named fields, write only these fields, call only these endpoints, send only to these recipient classes, and stop when the cumulative limit is reached.
Then test both halves of the contract. The system must complete allowed work, and it must fail safely when it attempts prohibited work. A release is not ready if the team has tested successful task completion but cannot show what happens when a tool refuses access, a dependency returns an unexpected result, an approval expires, or the agent tries an undeclared action.
Treat every permission as a product decision
Permissions determine the maximum harm an autonomous system can cause even when the model behaves unexpectedly. Give the runtime a dedicated identity, the minimum access required for the current use case, and no standing path to grant itself more authority. Separate development, test, and production identities. Do not place broad employee credentials or shared administrator tokens inside an agent workflow.
Use this evidence table at the release review:
| Control decision | Evidence required | Block release when |
|---|---|---|
| Accountability | A named business owner, product owner, technical owner, and incident decision-maker | Everyone owns the system in theory, but nobody has authority to pause it |
| Runtime identity | A dedicated service identity mapped to the agent and environment | The agent uses a shared human or administrator credential |
| Tool permissions | An allowlist of tools, operations, resources, and destinations needed for the stated objective | Access is broader than the action envelope or includes unused write privileges |
| Data scope | Named datasets, fields, retention behavior, and rules for sensitive data | The team cannot say which data can enter prompts, tool calls, logs, or external services |
| Transaction limits | Enforced per-action and cumulative limits appropriate to the use case | Limits exist only in instructions or dashboards and cannot prevent execution |
| External communication | Approved channels, recipient classes, domains, templates, and review conditions | The system can contact an arbitrary destination or send unreviewed high-impact messages |
| Containment | A demonstrated way to deny new calls, revoke credentials, stop queued work, and identify in-flight actions | The only shutdown method depends on the agent obeying another prompt |
Keep read and write capabilities separate when the architecture permits it. An analysis component may need broad read access but no ability to make changes. An execution component may need a small set of tightly validated write operations without access to the full underlying dataset. This separation makes the boundary easier to reason about and reduces the blast radius of a failure.
Apply limits below the model layer. A payment service should reject an out-of-policy amount. A messaging service should reject an unapproved destination. A deployment system should reject a production change without the required authorization. The model can propose an action; the system that owns the consequence should decide whether the action is permitted.
Start production with less authority than the final vision. Let the system recommend, then prepare, then execute a narrow set of reversible actions. Expand access only when runtime evidence shows that the existing envelope is understood and controlled. Autonomy is not a single launch decision. It is a sequence of permission decisions.
Put humans at decision thresholds, not beside every action
Human oversight fails when it is described only as human in the loop. A person who receives an alert after an irreversible action is not controlling that action. A person asked to approve a high volume of low-context requests will eventually become a rubber stamp. Meaningful oversight requires approval thresholds, escalation rules, monitoring, and intervention mechanisms that match the speed and consequence of the workflow.
Choose the oversight mode action by action:
- Human before action: Use this for irreversible changes, consequential decisions about people, sensitive external communications, material financial activity, changes to access or security controls, and actions outside a previously validated pattern. If approval is unavailable, the action should fail closed.
- Human on exception: Use this for bounded, reversible execution where policy violations, unfamiliar targets, cumulative limits, conflicting evidence, or repeated failures can stop the run before the next side effect.
- Human after action: Use this for quality review and policy improvement when the completed action is low-consequence and recoverable. Do not treat retrospective sampling as protection against irreversible harm.
Give the approver enough context to make a decision
An approval request should show more than a generic task name and an approve button. Present:
- The original objective and the specific proposed action
- The target account, record, recipient, system, or transaction
- The data that will be read, changed, or disclosed
- The expected side effect and whether it can be reversed
- The policy or evidence supporting the recommendation
- The cumulative actions already taken in the run
- The alternatives available to the approver, including edit, deny, pause, and escalate
Bind approval to the action that was reviewed. If the amount, recipient, payload, target, or relevant context changes, require a new decision. Otherwise the interface may appear to provide control while the execution layer performs something materially different.
Also define who watches the system at the portfolio level. Product owns the intended behavior and customer consequence. Engineering owns technical enforcement and reliability. Security owns access and threat controls. Legal, privacy, compliance, trust and safety, or domain specialists own their respective risk judgments. One accountable executive must have the authority to restrict or suspend the system when these views conflict. A committee without decision rights is not a control.
Run autonomy as a controllable production system
Pre-launch evaluation tells you how a system behaved under tested conditions. Production governance must tell you what it is doing now, whether it remains inside its envelope, and how to contain it when it does not. That requires observability, incident response, and stop mechanisms designed as product capabilities.
Record enough to reconstruct the route
Assign every run a durable identifier and capture the chain from objective to consequence. At minimum, the record should connect:
- The runtime identity, accountable owner, environment, and start time
- The objective, relevant policy version, model version, tool versions, and configuration
- Each decision, tool selected, arguments supplied, response received, retry, and error
- Each approval request, the evidence shown, the approver, the decision, and any edits
- Each side effect, including the target, result, cumulative limit usage, and reversal status
- Each denied or abandoned action, especially attempts to cross a boundary
Protect this record and control access to it. Logs can create a second data-exposure problem if they copy credentials, secrets, personal information, or sensitive payloads without need. Redact secrets before storage, minimize sensitive content, and retain what your investigation and compliance requirements genuinely require.
Do not measure success only by task completion. Track attempted policy violations, blocked destinations, approval overrides, repeated retries, unexpected tool sequences, cumulative side effects, and runs that a person had to contain. A denied action is evidence that a control worked, but repeated denied actions are evidence that the system is pushing against its design.
Build and test the stop path
A stop button in the user interface is not enough. The containment path should work even if the model is unresponsive, a queue still contains work, or one tool integration has failed. Use independent control points that can pause orchestration, reject new tool calls, revoke runtime credentials, stop queued jobs, and block sensitive destinations.
Test the path before production with a controlled, non-destructive task:
- Start a run that includes multiple permitted tool calls.
- Trigger the containment control while work is in progress.
- Confirm that new actions are denied and queued actions do not continue silently.
- Revoke the runtime credential and verify that direct tool access also fails.
- Identify any side effect completed before containment and exercise its supported reversal path.
- Confirm that alerts reached the responsible people and that the audit record shows who stopped the system, when, and why.
- Require an explicit recovery decision before restoring authority.
Do not run a destructive stop test against real customers, production money, or irreplaceable data. Use a sandbox or a deliberately constrained production-like environment, then verify the same control wiring before launch.
Use an incident playbook built for machine-speed action
The first responder should not have to invent the sequence during an event. Define it in advance:
- Detect: Alert on executed harm, unauthorized attempts, unexpected access, boundary pressure, and loss of observability.
- Contain: Pause the workflow, revoke credentials, block destinations, isolate affected integrations, and prevent queued work from continuing.
- Preserve: Protect the run record, configuration, approvals, tool responses, and affected business records without spreading sensitive data.
- Assess: Determine what was attempted, what executed, who or what was affected, whether data left an approved boundary, and which obligations require specialist review.
- Recover: Reverse supported actions, restore business operations through a safe path, and keep the agent restricted until owners approve resumption.
- Improve: Fix the model behavior where relevant, but also tighten permissions, validation, limits, monitoring, and escalation. A prompt change alone rarely addresses an authorization failure.
Escalate attempted prohibited behavior even when enforcement blocked it. The absence of customer harm does not make the event irrelevant; it may be the cheapest warning you receive. If the event may involve unlawful access, sensitive-data exposure, financial loss, safety impact, or a regulated decision, bring in the appropriate security, privacy, legal, compliance, or domain professional immediately rather than improvising an individual response.
Make evidence the release gate
Move through progressively broader operating modes: isolated testing with synthetic or non-sensitive data, recommendation-only or shadow operation, narrowly scoped reversible execution, and then any additional authority justified by the use case. Do not promote a system merely because task completion improved. Require evidence that controls work when the system takes an unexpected route.
Before each expansion, ask the team to demonstrate an allowed action, a denied action, an approval boundary, a cumulative limit, a dependency failure, a loss of access, an audit reconstruction, and a containment test. If the system cannot survive those demonstrations, keep it in its current mode.
High-impact frontier development may warrant review outside the delivery chain as well. One emerging industry proposal gives independent evaluators standing access to inspect safeguards and report incidents. External scrutiny can challenge internal assumptions, but it does not replace enforceable permissions, operational ownership, or the ability to stop a deployed system.
Key takeaways
- Govern what the system can do, not only what its model can generate.
- Require a versioned action envelope that names decisions, tools, data, side effects, limits, approvals, and recovery paths.
- Enforce boundaries in permissions and transaction systems rather than relying on prompt instructions.
- Place humans before high-consequence actions and on the exceptions that can still be stopped.
- Log the full route from objective to side effect while keeping secrets and unnecessary sensitive data out of the audit record.
- Test credential revocation, queue containment, alerts, reconstruction, and recovery before expanding autonomy.
- Treat each increase in authority as a new release decision supported by evidence.
At your next roadmap or launch review, ask for two things: the action envelope and a live containment demonstration. If the team cannot produce both, keep the product in recommendation or draft mode. Let the system earn autonomy one bounded, observable, reversible permission at a time.
References
- AI Gov Now – EU AI Act Meets Agentic AI
- AI Policy Perspectives – The AI Discourse: A Guide
- Everything AI Newsletter – The Week AI Safety Became Impossible to Ignore
- Ask Me AI – The Uber Driver, the Kill Switch, and the Week AI Asked for a Speed Limit






