
Your AI product has users, a full roadmap, and an executive sponsor. It can still be heading toward shutdown. Topline adoption and an impressive model demo tell you that people tried the product. They do not tell you whether people will keep using it, whether the economics work, or whether the product deserves to remain independent.
If you are deciding whether to fund another release, pivot the experience, fold it into a larger platform, or stop, you need a failure test that separates fixable execution problems from a broken product thesis. The goal is not to eliminate failure. It is to recognize the kind of failure you have before the organization spends another planning cycle treating it as a feature gap.
Start by naming the failure you are actually managing
S&P Global Market Intelligence estimates that about 42% of AI initiatives are eventually abandoned by their corporate parents. That number should sharpen your governance, but it should not turn every cancellation into the same story. A product that never found repeat demand is different from a useful feature that belongs inside a larger product. A privacy-delayed launch is different from a service whose inference costs overwhelm its revenue.
Use four possible decisions from the start: continue, reset, absorb, or shut down. If the review only allows teams to argue for more funding, evidence gets interpreted as a roadmap request. Giving each alternative a legitimate place in the process makes it easier to identify what the product is actually telling you.
| What you observe | What may really be failing | Decision to examine |
|---|---|---|
| Users value the capability but rarely open the standalone product | Packaging, distribution, or product boundary | Absorb it into a product they already use |
| Many people try it, but few repeat the core workflow | Problem selection, outcome quality, or product-market fit | Reset the use case or shut it down |
| Usage repeats, but variable cost rises with every successful job | Pricing, architecture, or unit economics | Reprice, redesign the service, or stop subsidizing it |
| The product works technically, but creates unresolved privacy, safety, or legal exposure | Permission to operate | Block expansion until the hard gate is resolved |
| A device demo works, but the complete experience is unreliable | End-to-end readiness | Narrow or delay the launch |
Before discussing solutions, write a one-sentence failure thesis: “Because this user does not repeat this workflow, and each successful outcome requires this level of cost or intervention, the current product cannot produce this business result without this unproven assumption.” Replace every vague phrase with an observed behavior, a cost, an owner, or an explicit unknown. If the team cannot complete the sentence, it is not ready to defend the roadmap.
Five patterns that turn AI momentum into a shutdown
1. The platform turns your product into a feature
Relay shut down after larger platforms added similar workflow automation. Huxe faced a comparable squeeze as established products expanded their AI audio experiences. Notion Mail found that users were handling email through separate AI agents, weakening the reason for its own experience to exist. Even OpenAI absorbed standalone bets such as Atlas and Operator into ChatGPT when their useful capabilities fit better inside the larger product surface. These were not all identical business outcomes, but they expose the same strategic risk: a capability can be valuable while its standalone container becomes unnecessary.
Run a platform-substitution test before approving another feature cycle. Ask what remains if the underlying model provider, operating system, CRM, productivity suite, or distribution partner ships a similar workflow. A durable answer usually rests on something the platform does not automatically inherit: proprietary workflow data, deep domain integration, a trusted customer relationship, regulated operating knowledge, unique distribution, or a system of action that crosses multiple tools.
Do not accept “better prompts” or temporary model access as the moat. If the differentiated value disappears when a platform adds a menu item, treat absorption as a product strategy option rather than waiting for the market to force it on you.
2. Adoption grows faster than the business underneath it
Sora struggled with operating costs and retention before its video-sharing product closed. Figgs AI attracted more than 1 million users, yet its developers said the free service had become too expensive to sustain. Yupp supported comparisons across more than 800 models at its peak but still did not find product-market fit strong enough to continue. These cases correct a dangerous assumption: a large volume of AI activity is not the same as a viable product.
Measure economics around a successful user outcome, not a login, generated token, or raw request. For an AI support agent, that might be a correctly resolved case. For a coding agent, it might be an accepted change that passes the required checks. For a media product, it might be an asset the user keeps, exports, or publishes. Then attach the complete variable cost: model inference, media generation, storage, retrieval, external tools, moderation, retries, human review, support, and refunds.
Report this by use case and cohort. Averages can hide the fact that retained power users generate most of the value and most of the cost, while a much larger group tries the novelty once. If the product becomes less attractive financially as users become more engaged, growth is amplifying the problem.
3. A successful demo is mistaken for end-to-end readiness
AI hardware makes this mistake particularly expensive. Humane raised $230 million, but its AI Pin struggled with product performance, and customers were warned to stop using its charging case because of a potential battery fire risk. The business closed before HP acquired most of its assets for $116 million. Rabbit said it sold 100,000 R1 units soon after launch, while early reviewers found the product unfinished, unreliable, and limited by its integrations. Rabbit continued updating the device, illustrating the difference between a difficult launch and an abandoned product. In both cases, early financing or sales did not settle the readiness question.
Your readiness gate must cover the whole system under normal and degraded conditions: device behavior, cloud availability, model latency, tool authentication, integration failures, battery and thermal safety, support capacity, returns, and recovery when an agent takes the wrong action. A polished happy path cannot compensate for a critical failure in a component the user experiences as part of one product.
For software, apply the same logic to agentic workflows. A model completing one step in a controlled demo is not proof that the product can handle expired credentials, ambiguous instructions, unavailable tools, malformed data, retries, duplicate actions, and safe handoff to a person. Launch readiness belongs to the system, not the model.
4. The promise gets ahead of the product and its trust controls
Microsoft’s Recall triggered an immediate privacy backlash and was delayed for nearly a year; a security researcher later demonstrated a way to extract captured data, reopening the underlying concern. Apple repeatedly delayed the AI-powered Siri capabilities it had promoted and reached a $250 million settlement connected to how iPhone 16 AI features were marketed. OpenAI’s attempt to combine Chat, Codex, and Work modes into a super-app experience was rolled back after users found the change confusing and cluttered. In each case, the rollout itself became part of the product risk.
Create a promise ledger before launch. Every material statement in the announcement, sales deck, onboarding flow, and pricing page should map to a tested capability, supported device or account type, available language or market, known limitation, and accountable owner. If a feature is staged, gated, or dependent on an integration you do not control, say so where the promise is made.
For privacy-sensitive capabilities, complete the threat model and data-control design before the announcement fixes customer expectations. Document what is collected, where it is stored, who or what can retrieve it, how users disable it, what is excluded, and how deletion works. A reversible interface change can be rolled back. Exposure of sensitive user data cannot be treated as an ordinary experiment.
5. Legal and safety exposure becomes part of the operating model
Character.ai filed for bankruptcy after achieving substantial financial and technical milestones. It had raised $150 million at a $1 billion valuation, and Google reportedly paid $2.7 billion to license its technology and hire its founders. Lawsuits alleging chatbot harm to teenagers, a Disney cease-and-desist letter, settlements, and other operational pressures followed. The bankruptcy filing cited legal, regulatory, and operational headwinds. Those allegations do not by themselves establish liability, but the sequence shows that valuable technology and major transactions do not remove permission-to-operate risk.
Put safety, rights, privacy, and regulatory exposure into the product model before scale. For character or companion experiences, that includes age-related safeguards, escalation for high-risk interactions, persona and intellectual-property rights, content controls, auditability, and incident response. For enterprise agents, it includes data boundaries, authorization, action logs, approval requirements, and a reliable way to stop or reverse actions.
Some risks should be hard gates, not weighted metrics. Strong retention cannot offset a critical safety defect, unlawful data use, or an unmitigated security path. Have the appropriate legal, security, privacy, and safety owners decide whether those gates are satisfied; a product scorecard is not a substitute for their professional review.
Use a five-gate scorecard, not a single success metric
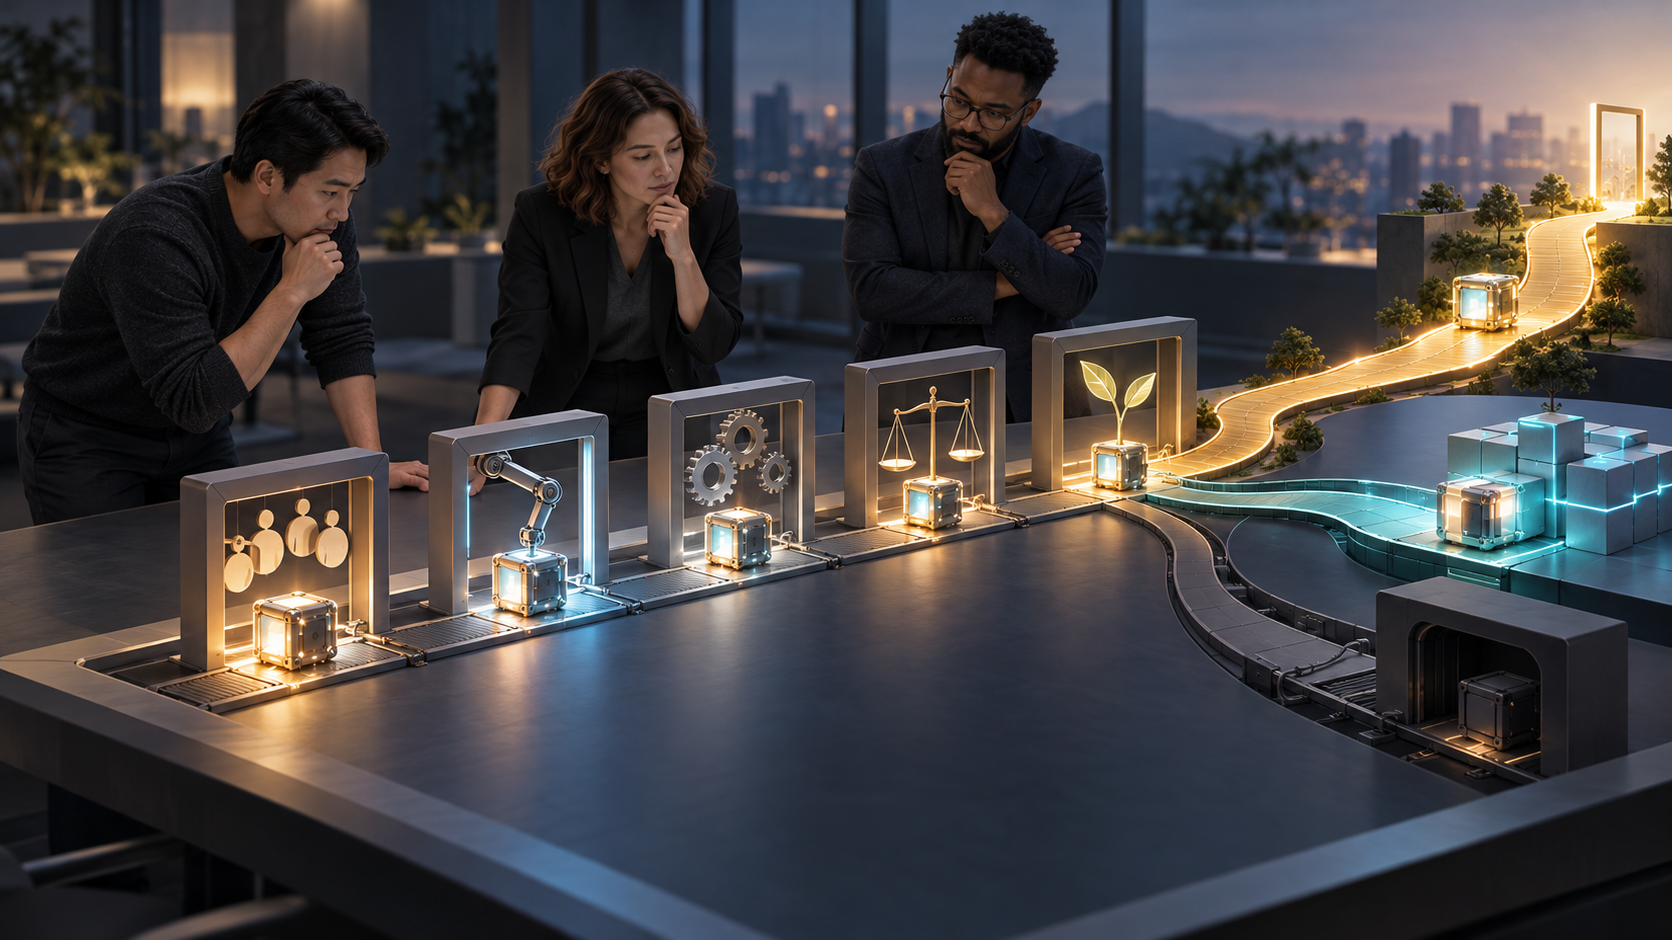
A useful funding review forces evidence across five gates. Do not reduce them to one weighted score. An average lets excellent adoption conceal unacceptable risk, or cheap inference conceal the absence of a real user problem.
- Demand: Name the user, the triggering situation, and the outcome they repeatedly seek. Report retained completion of that workflow by cohort, not total registrations. Distinguish users who inspect a generated answer from users who accept it, act on it, or return to obtain the same kind of outcome again.
- End-to-end quality: Maintain an evaluation set drawn from real target tasks and known failure modes. Track task success, human takeover, retries, latency at the moment value is delivered, and the severity of failures. A model-quality improvement matters only when it improves the user’s complete job.
- Economics: Calculate cost per successful outcome and contribution after all variable AI and operational costs. Show the result by use case and customer cohort. State which cost improvement is already demonstrated and which still depends on a future model, volume discount, architecture change, or pricing decision.
- Defensibility and distribution: Identify the asset that keeps the product relevant when a major platform adds a similar capability. Then test whether that asset improves acquisition, workflow depth, outcome quality, switching cost, or distribution. Naming an asset is not enough; it must change customer behavior or economics.
- Permission to operate: Record unresolved privacy, security, safety, intellectual-property, contractual, and regulatory issues. Assign an owner and a release condition to each one. Critical issues remain visible as hard gates instead of being buried in a general risk register.
Each gate should end with a decision statement, not a dashboard screenshot: what the team now knows, what remains unproven, what evidence would change the conclusion, and when that evidence will be reviewed. This prevents a familiar pattern in AI programs: better model metrics arrive every month while the original product and business assumptions remain untouched.
Make continuation compete with absorption and shutdown
The next roadmap should not be the default outcome of a product review. Put all four decisions on the same page and specify the evidence that supports each one.
| Decision | Evidence that supports it | What happens next |
|---|---|---|
| Continue | The target workflow repeats, end-to-end quality is improving, economics have a credible path, and every hard trust gate is satisfied | Fund the next riskiest assumption, not an undifferentiated feature backlog |
| Reset | The user problem is real, but the use case, interaction model, audience, quality, or price is wrong | Run a bounded test with one falsifiable product thesis and a named decision point |
| Absorb | The capability creates value, but a standalone destination adds acquisition and retention friction | Move it into the workflow where users already perform the job and measure whether frequency improves |
| Shut down | Repeat demand is absent, economics rely on indefinite subsidy, differentiation is disappearing, or a critical trust issue has no acceptable remedy | Stop new promises, protect users, unwind dependencies, and preserve reusable learning |
For any continue or reset decision, require a short pre-mortem. State what must become true, the earliest signal that it is not becoming true, who owns that signal, and what action follows. Also separate reversible choices from irreversible ones. Changing an onboarding sequence is reversible. Shipping hardware at scale, retaining sensitive data, making a broad marketing claim, or allowing an agent to take consequential actions may not be.
If shutdown is the answer, manage it as a product operation rather than an announcement. Stop selling capabilities that will not be supported. Give users clear dates and a practical export or migration path. Map API clients, integrations, model dependencies, stored data, contractual commitments, and internal workflows before turning systems off. Have legal and security owners review retention and deletion obligations because they vary by contract and jurisdiction. Preserve evaluations, incident history, architecture decisions, and falsified assumptions so the next team does not pay to relearn them.
Finally, change how funding is released. Tie each stage to reduction of the largest remaining risk: repeat demand, system quality, viable economics, differentiation, or permission to operate. Feature completion is evidence of output. It is not, by itself, evidence that the product deserves another stage of investment.
Key takeaways for your next funding review
- A valuable AI capability can still be the wrong standalone product. Test absorption before a platform makes the decision for you.
- Measure retention and cost around successful user outcomes. Registrations, requests, and generated content can all grow while product-market fit deteriorates.
- Evaluate the complete system, including tools, integrations, retries, support, privacy, and recovery. A reliable model does not guarantee a reliable product.
- Treat safety, security, privacy, and legal permission as hard gates where the downside cannot be balanced by adoption.
- Make continue, reset, absorb, and shut down explicit alternatives. Then fund the evidence needed to resolve the riskiest remaining assumption.
Before your next roadmap meeting, ask the product owner to bring one page covering the five gates and the four possible decisions. If a cell cannot be completed, that missing evidence is part of the decision. It may not mean shutting the product down immediately. It does mean you should stop expanding its promise until the team can show why it has earned the right to continue.
References






