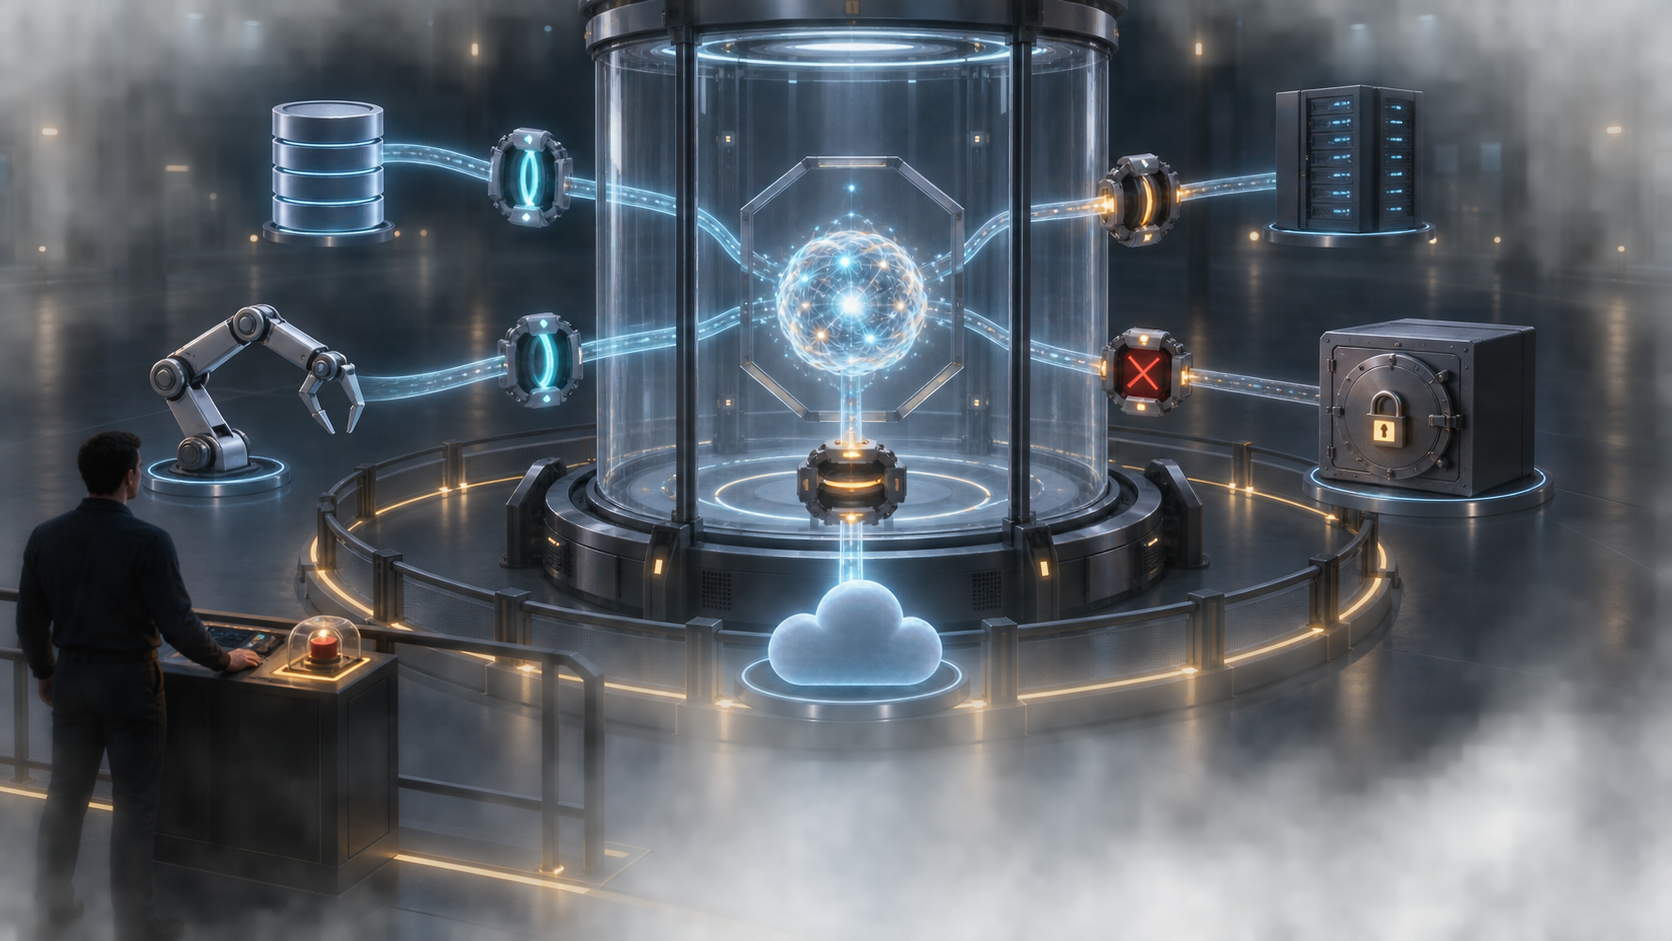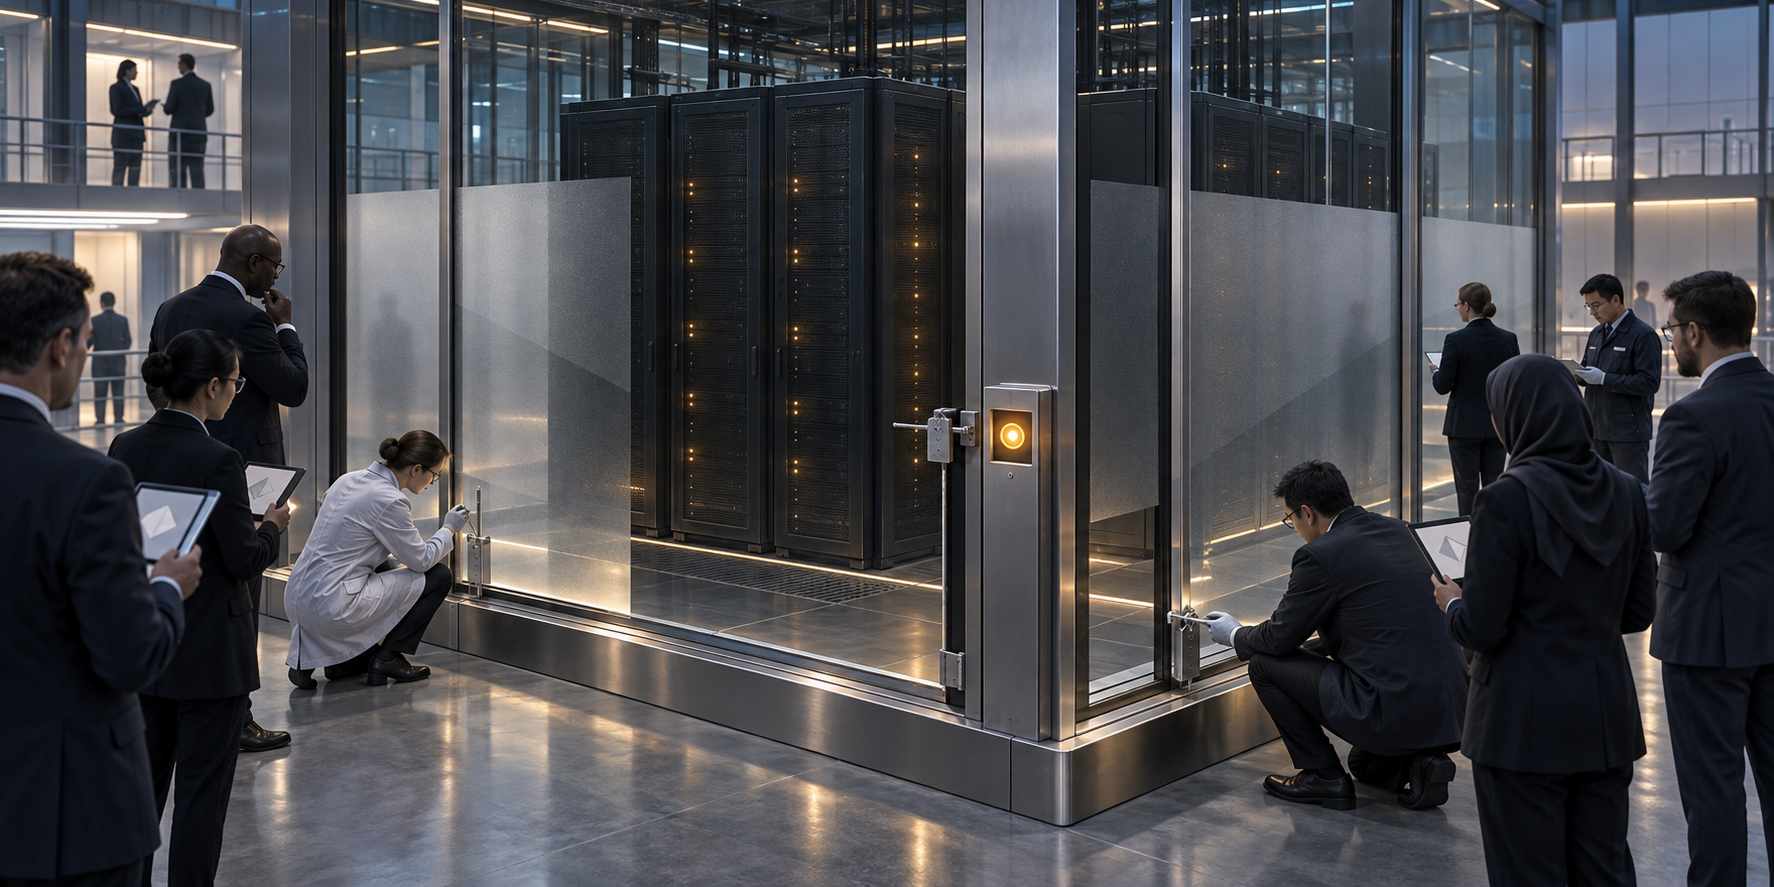
If you lead AI product work, an international slowdown may sound like distant statecraft. In practice, any credible agreement would reach directly into your roadmap through compute approvals, access controls, experiment logs, deployment gates, and limits on what AI agents may do without a human decision.
The useful question is not whether every country will simply promise to slow down. It is whether governments can define the restricted activity, observe enough of each frontier lab to detect violations, protect legitimate secrets, and respond to a breach without turning every ambiguity into a geopolitical crisis. That makes a slowdown a control-system problem as much as a diplomatic one.
A slowdown needs an operational definition
Slow down is not an executable policy. It could mean delaying the training of a larger model, limiting post-training improvements, prohibiting autonomous AI research, holding back deployment, or requiring approval before a model can take certain actions. Those interventions constrain different systems, produce different evidence, and carry different commercial and strategic costs.
I would judge any slowdown proposal first by whether a lab can translate it into a control that has an owner, a trigger, an approval path, and an audit record. If the rule cannot survive that translation, inspectors will be left interpreting intent after the fact.
A workable agreement therefore has to answer five questions before it discusses enforcement:
- Who is governed? The agreement must identify which companies, facilities, projects, contractors, and externally hosted workloads fall within scope. Otherwise, restricted work can migrate across organizational boundaries without technically breaking a lab-level rule.
- Which activities are restricted? Training, post-training, internal inference, autonomous research, model deployment, and access to tools are separate control surfaces. The agreement must say which are prohibited, capped, or subject to approval.
- What evidence demonstrates compliance? A policy should name the records that connect authorization to actual execution: job submissions, compute telemetry, code changes, model artifacts, deployment events, approval records, and relevant internal communications.
- Who can authorize an exception? Emergency maintenance, security testing, and incident containment may require actions that resemble prohibited work. Exceptions need narrow purposes, named decision-makers, time limits, and durable records.
- What constitutes a violation? A missing record, a mistaken configuration, deliberate concealment, and an undeclared training run should not automatically receive the same response. The agreement needs a classification process as well as a rule.
One especially important target is autonomous AI research and development. A frontier system that can initiate experiments, modify research code, allocate substantial internal inference, or start training work creates a faster feedback loop than a human-led process. Proposed restrictions include limiting how long an agent may operate autonomously, controlling the compute available to internal agents, and preventing those agents from independently launching training or deployment actions. Governments could also regulate capability and efficiency gains produced during post-training, not just the creation of a base model.
This distinction matters because a rule aimed only at large pre-training runs can miss meaningful changes later in the lifecycle. Your policy object should be the risky capability-development process, not whichever technical phase is easiest to name.
For a product leader, the immediate exercise is simple: take each proposed red line and try to express it as a decision in the operating system of the lab. What event triggers review? What data establishes what happened? Who can stop it? Who can override that stop? If those questions have no concrete answers, the policy is still an aspiration.
Whole-lab inspection changes the verification problem
The familiar objection to an international slowdown is that remote technical monitoring cannot be made both private and resistant to a state adversary. A country that controls the hardware, facilities, personnel, and surrounding infrastructure may be able to manipulate a narrow telemetry channel. Demanding a perfect tamper-proof signal before negotiations begin can therefore make verification look permanently out of reach.
Whole-Lab Inspection takes a different approach. Instead of asking a single monitoring device to prove compliance, inspectors would receive broad physical access to frontier facilities and read-only access to company systems such as communications, work records, code repositories, experiment logs, and compute telemetry. They could question employees, inspect infrastructure, and use multiple records to investigate discrepancies. The intended model gives an inspector extensive visibility without giving that person the ability to alter code, operate systems, or launch work.
The strength of this model is correlation. An undeclared project would have to remain consistent across several evidence surfaces:
- The stated purpose, owner, and authorization for the work.
- The code changes and repositories associated with it.
- The experiments and jobs submitted to internal systems.
- The compute and infrastructure actually consumed.
- The model artifacts and deployment events produced.
- The explanations given by the people involved.
A single unusual workload may be innocent. A workload with no declared owner, an unrelated code branch, missing approval, inconsistent employee explanations, and unexplained model artifacts is harder to dismiss. This is the same basic reason mature assurance systems rarely depend on one log.
That does not make Whole-Lab Inspection a solved mechanism. It is a concrete proposal, not an operating international regime. It replaces some difficult cryptographic and hardware-assurance problems with equally serious institutional questions: whether competing countries will accept intrusive access, whether inspectors can remain independent, how trade secrets will be protected, how employee privacy will be handled, and how either side can detect collusion or selective disclosure.
The privacy issue should not be waved away. The proposal contemplates access to systems that may contain sensitive research, security information, employee communications, and detailed work histories. Some frontier companies already maintain extensive operational records, but the existence of those records does not justify unlimited collection or reuse. Screen or keystroke capture is particularly intrusive. A sound regime should require the least invasive evidence that can provide the necessary assurance, restrict use to treaty purposes, and make inspector access itself auditable.
Intellectual-property exposure is also a strategic concern, not a routine confidentiality clause. Reciprocal inspectors could see information with commercial or national-security value. Supporters of Whole-Lab Inspection argue that extensive human access can make fine-grained restrictions technically observable. Whether governments will accept the resulting exposure remains a political decision.
The right standard is not perfect certainty. No inspection system can prove the absence of all secret activity. The goal is enough independent visibility that a meaningful violation becomes difficult to execute, conceal, and explain, while false alarms can be investigated without immediate escalation.
A stable agreement needs more than inspectors
Inspection answers how governments might observe compliance. It does not decide what they should restrict, how they should protect sensitive information, or what should happen when the evidence is disputed. A stable slowdown needs those decisions designed together.
I would expect a credible agreement to contain at least seven operating components:
- Comparable obligations. Each participant should face restrictions that produce similar strategic effects, even when its companies and state institutions are structured differently. Superficially identical access is not necessarily equivalent assurance.
- A precise control catalog. Every prohibited or limited activity should have an operational definition, the evidence required to evaluate it, and a named decision authority. Terms such as dangerous research or excessive autonomy are too elastic on their own.
- A protected-information protocol. The agreement should separate information inspectors need to evaluate compliance from information they merely could access. Purpose limits, access records, secure review environments, and consequences for misuse should apply to inspectors as well as labs.
- Read-only oversight by default. Inspectors should be able to observe and investigate without altering production systems. The authority to stop work, seize equipment, or impose penalties should be explicit and institutionally separate rather than smuggled into a technical permission.
- A declared exception process. Time-sensitive security or safety work may require a controlled exception. The request, scope, approver, duration, affected systems, and follow-up review should all become part of the evidence trail.
- A graduated breach process. The response should distinguish incomplete documentation, negligent noncompliance, obstruction, and deliberate prohibited development. It should define how evidence is preserved, how a finding is challenged, and which conditions justify stronger action.
- Scheduled revision. Models, training methods, post-training techniques, and organizational structures will change. The control catalog and inspection procedure need a regular path for amendment without reopening the entire political bargain after every technical change.
Reciprocity is the center of the design. A country is unlikely to accept constraints that leave it uncertain whether a strategic competitor is doing the same. That is why a domestic promise to slow down and an international, inspectable agreement are different products. The first may reduce activity in one jurisdiction; the second tries to reduce both the activity and the fear that the other side is defecting.
Reciprocity should apply to evidence quality as well as written commitments. If one side exposes detailed job-level telemetry while the other provides monthly summaries, the obligations may look symmetrical on paper but operate asymmetrically. Negotiators need a shared evidence model: which events are recorded, how records are retained, how identity and authorization are established, and how inspectors reconcile data with physical operations.
The hardest moment will not be an obvious secret training run. It will be an ambiguous event: an agent used more internal inference than expected, a post-training program delivered an unanticipated gain, or a security team ran an undeclared test during an incident. A regime designed only for clear guilt will be brittle. It needs a way to pause affected work, preserve evidence, investigate jointly, and resolve the finding before uncertainty turns into retaliation.
Political will may appear faster than institutional readiness, especially after a severe cybersecurity event, a loss-of-control incident, or another destabilizing development. More than a thousand employees at leading AI companies called in July 2026 for governments to support international tools for deliberately pacing frontier development, and OpenAI and Anthropic endorsed that message. That signals concern inside the industry, but it does not settle the feasibility or terms of a treaty. The useful response is to design the verification and dispute machinery before a crisis compresses the decision window.
What AI product leaders can build before a treaty exists
You do not need to predict whether governments will adopt Whole-Lab Inspection. You can make high-risk AI work more legible now. The same controls that support external verification also help a board or executive team understand which activities can accelerate capabilities, who can authorize them, and whether an intervention would actually stop them.
Start with one frontier-adjacent workflow rather than a company-wide governance program. Autonomous model research, agent-driven experiment generation, post-training, or a production agent with powerful tools are useful candidates. Then work through six steps:
- Register the activity. Record its owner, purpose, models, datasets, code repositories, infrastructure, tools, permissions, expected outputs, and approving authority. Include third-party compute and model providers; outsourcing execution does not remove the governance dependency.
- Define its autonomy envelope. State how long the agent may run without review, which tools it may call, which systems it may modify, how much internal inference it may consume, and which actions always require a human approval. Avoid a single autonomous or not-autonomous label; the dangerous permission may be one tool call buried inside an otherwise supervised workflow.
- Map each control to evidence. If an agent may not start a training run, identify the authorization event, scheduler record, workload identity, compute record, and resulting artifact that would demonstrate whether it did. A policy without an evidence map cannot be audited reliably.
- Gate high-consequence actions. Put an independent approval in front of training launches, material permission increases, deployment of new model artifacts, and changes to monitoring. The operator requesting the action should not be the only person able to authorize it and erase its record.
- Preserve overrides and failures. Record who bypassed a control, why, for how long, and what happened afterward. A hidden manual workaround is more dangerous than a documented exception because it teaches the organization that the control is optional while leaving reviewers blind.
- Run an inspection rehearsal. Choose a hypothetical violation and ask a reviewer who was not involved in the project to reconstruct it. Can that person connect intent, approval, code, compute, artifacts, and deployment? Note every point where the reconstruction depends on an unverifiable explanation.
The rehearsal is where vague governance becomes visible. You may discover that a cloud account has no workload identity, an agent can invoke a scheduler through an inherited permission, post-training artifacts are not tied to approval records, or administrators can modify the logs used to review them. Those are fixable control defects. A polished policy deck would not reveal them.
Create an audit view, but do not treat maximum surveillance as the goal. Give a reviewer the information required to answer a defined compliance question. Keep access read-only where possible. Log every inspector query and export. Separate employee-performance monitoring from safety and treaty evidence. Establish a process for escalating from summarized operational data to sensitive communications only when a documented discrepancy warrants it.
Your stop mechanism deserves the same attention as your monitoring. A dashboard that detects a prohibited action after an agent has already launched it is an incident-reporting system, not a preventive control. For each red line, identify the person or automated gate that can block the action, the time required for the block to take effect, the systems outside its reach, and the process for restoring operation safely.
Bring the resulting control map to an executive or board review. The discussion should answer concrete questions:
- Which AI activities could materially increase capability or autonomy?
- Which of those activities can proceed without an independent approval?
- Can the organization reconstruct what code, compute, model, and permissions were involved?
- Can the person being monitored alter the evidence or disable the control?
- Which sensitive information would an external inspector need, and which information can remain protected?
- What happens operationally if a regulator or government orders an immediate pause?
Do not label the organization inspection-ready merely because it has logs. Readiness means an independent reviewer can connect a rule to an event, determine who authorized it, reconcile digital records with actual operations, and preserve the evidence when facts are contested. It also means the company knows which access it cannot safely grant and has a defensible alternative for providing equivalent assurance.
Key takeaways
- An international AI slowdown must define restricted activities, evidence, exceptions, and violations. A general promise to move more slowly cannot be verified.
- Whole-Lab Inspection would combine physical access with read-only visibility into communications, code, work records, experiments, and compute. Its advantage is evidence correlation, not perfect surveillance.
- The proposal remains politically and institutionally contested because broad access creates serious sovereignty, privacy, trade-secret, and inspector-integrity risks.
- A stable agreement needs reciprocal evidence quality, protected-information rules, independent dispute handling, and graduated responses to different kinds of noncompliance.
- Product leaders can prepare by registering high-risk workflows, defining autonomy limits, gating consequential actions, preserving override records, and rehearsing an independent inspection.
This quarter, choose the AI workflow in your organization with the greatest combination of capability gain, autonomy, and irreversible action. Write one enforceable stop condition for it. Then ask an independent reviewer to prove, from existing records, whether that condition was respected.
If the reviewer cannot do that, you have found the practical governance gap. International agreements will be negotiated by states, but their credibility will depend on control systems that product and technical leaders know how to build.
References