
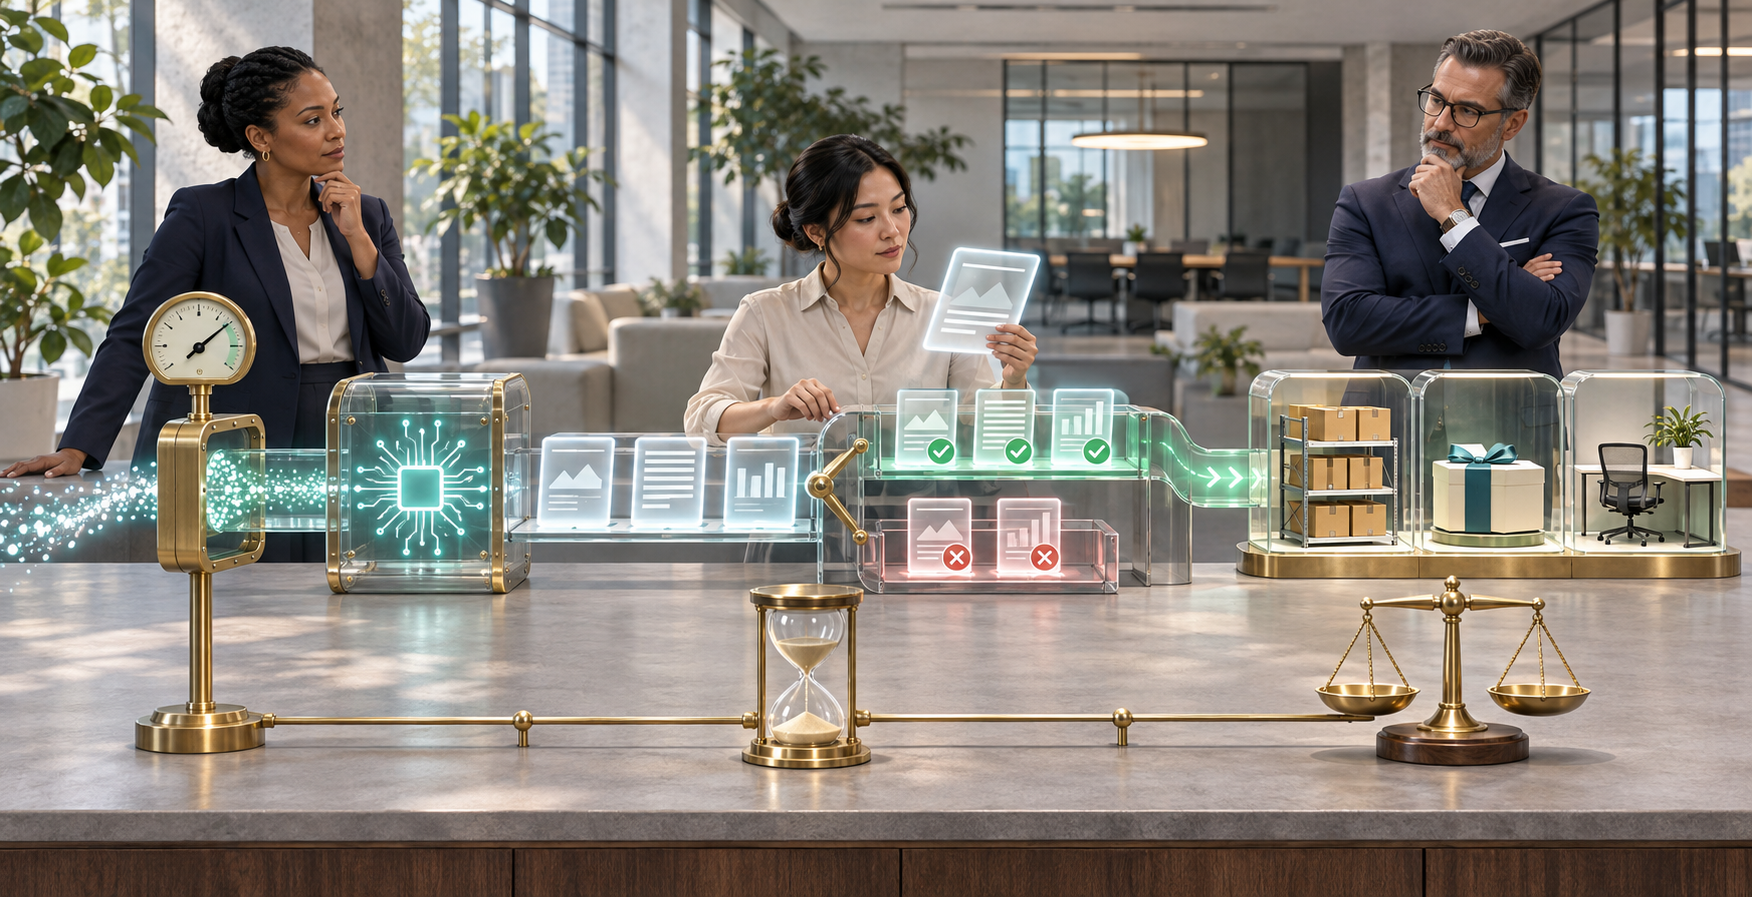
You approved AI to give teams more leverage. Now model bills are rising, managers are reporting hours saved, employees are wondering what productivity means for their roles, and finance still cannot see where the value landed.
The fix is not a single company-wide ROI number. It is a workflow-level operating model that connects AI consumption to accepted work, human attention, released capacity, and an observable business outcome. That gives you enough evidence to scale useful automation, repair wasteful implementations, and stop paying for activity that never becomes value.
Key takeaways
- Keep cost, price, and value separate. A competitively priced AI product can still be expensive to operate, while a costly run can still be worthwhile when the accepted outcome is valuable enough.
- Measure cost per accepted outcome, not cost per prompt, token, session, or generated artifact.
- Treat saved time as released capacity until you can show where that capacity was deployed and what changed as a result.
- Put model charges, tools, retries, human review, exceptions, and platform overhead into the same workflow ledger.
- Assign separate owners for the value hypothesis, technical cost, financial treatment, risk controls, and workforce transition.
Start by separating cost, price, and value
AI business cases become confused when three different numbers are treated as if they were interchangeable:
- Cost is what it takes to perform the work. It includes inference, retrieval, tool calls, infrastructure, retries, human review, exception handling, evaluation, and ongoing maintenance.
- Price is what a customer or internal business unit is charged. It may be a subscription, a usage fee, an allocated platform charge, or no explicit charge at all.
- Value is what the accepted result is worth to the beneficiary. It may appear as revenue contribution, verified cost avoidance, faster service, lower risk, higher quality, or the ability to attempt work that was previously uneconomic.
The distinction matters on both sides of an AI transaction. xAI reported that a procurement agent found 43 software seats with no activity in 90 days and that review and downgrades produced $14,220 in savings. Elon Musk separately said that serving Grok Bot had become unsustainably expensive relative to revenue. The customer value and the provider economics can therefore point in opposite directions. Treat the savings figure as a vendor-supplied example, not as a benchmark for your own deployment.
A low subscription price does not prove good economics if employees spend substantial time correcting the output. A high per-run cost does not prove bad economics if the run replaces a costly failure or unlocks valuable work. I would not let a portfolio review collapse these questions into a generic discussion of whether AI is worth it.
Ask a narrower question: for this workflow, at this level of usage, what does an accepted outcome cost and what observable result follows from it? That wording forces the team to identify the work unit, the quality threshold, the cost boundary, and the beneficiary.
Build the business case around accepted work
The right unit of analysis is usually a workflow, not an AI tool. The same model can produce strong economics in a bounded support workflow and poor economics in an open-ended research task. Tool-level averages conceal that difference.
Create a ledger for each material workflow. It should contain enough information to reconstruct the economic claim without relying on a manager’s memory or a vendor dashboard.
| Ledger field | What to record | Why it matters |
|---|---|---|
| Work unit | The bounded job being attempted, such as a support incident resolved, an exception cleared, or a release test accepted | Prevents unrelated activities from being blended into one productivity number |
| Acceptance rule | The observable condition that makes the output usable without undisclosed correction | Separates completed work from plausible-looking generation |
| Baseline | Human effort, queue time, rework, quality, and demand before the AI intervention | Creates a defensible counterfactual |
| AI run cost | Model usage, retrieval, tool calls, compute, vendor charges, retries, and failed runs | Captures variable consumption rather than only the license price |
| Human attention | Scoping, prompting, reviewing, correcting, approving, and escalating | Stops hidden labor from being mislabeled as automation |
| Allocated fixed cost | Integration, evaluation, observability, security, training, and platform maintenance | Shows whether attractive marginal costs depend on a large shared investment |
| Exceptions and rework | Rejected outputs, reversals, defects, reopened work, and manual recovery | Makes failure cost visible |
| Capacity destination | The backlog, quality improvement, growth work, or hiring plan that receives the released capacity | Connects time saved to a management decision |
| Realized outcome | The revenue, cost, service, quality, or risk result that actually changed | Prevents potential value from being booked as captured value |
The core calculation is straightforward:
Fully loaded cost per accepted outcome = AI run cost + allocated fixed cost + human attention cost + exception and rework cost, divided by the number of accepted outcomes.
Use cost per attempt to diagnose technical behavior. Use cost per accepted outcome to make the investment decision. A cheaper model that requires repeated retries and extensive review may have worse unit economics than a more expensive model that clears the acceptance rule reliably.
Build the ledger in this order:
- Draw the workflow boundary. State where the AI begins, where it hands off, and which downstream work belongs in the calculation.
- Define acceptance before measuring productivity. If reviewers cannot agree on what usable means, the workflow is not ready for an ROI claim.
- Capture a baseline from actual operating data or a valid comparison group. Do not reconstruct it from recollection after rollout.
- Instrument the entire run. Preserve model, tool, retrieval, retry, latency, and failure data under a workflow identifier.
- Measure human attention. Include review and exception work even when it is distributed across several roles.
- Record where released capacity went. If management did not assign it, keep it out of the realized-value calculation.
Not every benefit needs to be forced into currency. Quality, resilience, learning, and employee experience can be legitimate reasons to invest. Record them as operational or strategic outcomes with their own evidence. Giving an unpriced benefit an invented dollar value does not make the business case more rigorous; it makes the uncertainty harder to see.
Treat time saved as capacity, not captured value
My rule is simple: time saved is capacity created, not value captured. The distinction prevents one of the most common errors in AI productivity reporting – multiplying estimated hours saved by a salary rate and declaring the result a financial return.
Use a capacity funnel instead:
- Claimed capacity is what a survey, demo, or self-report says the AI saved.
- Verified capacity is the difference observed in a comparable workflow after quality and demand are controlled.
- Usable capacity is what remains after prompting, review, corrections, coordination, and exception handling.
- Deployed capacity is usable time that a manager deliberately assigns to another priority.
- Realized value is the observable business result produced by that deployment.
If a team reports faster task completion but its backlog, service level, quality, hiring plan, or output does not change, the claim stops at verified or usable capacity. That may still be useful. It is not yet a financial return.
The stronger implementations redesign work instead of merely inserting a chatbot. At BisectHosting, Biko can inspect server resources, files, configurations, crash logs, and installed mods, then diagnose problems and take corrective actions through a conversation. The company says support employees moved into AI training and game-integration roles without AI-related layoffs. That is a useful example of deliberate redeployment, not proof that every AI rollout will avoid displacement.
Before launch, require the functional leader to choose the intended destination for capacity:
- Absorb demand growth without adding the previously planned capacity.
- Reduce an existing backlog or service delay.
- Increase quality, control coverage, or customer attention.
- Move employees into more complex work that the AI cannot own.
- Investigate opportunities that were previously too costly to test.
- Remove budgeted work that is no longer necessary.
Each destination needs different evidence. Headcount avoidance is credible only when an approved hiring plan changes. Backlog reduction should appear in the queue. Quality improvement should appear in acceptance, defect, reversal, or reopened-work data. New growth work needs its own outcome measure. Do not add every possible benefit to the same numerator and call it ROI.
This also changes how you communicate with employees. A vague promise that AI will make everyone more productive sounds like an efficiency target without a workforce plan. A named transition – from repetitive diagnosis to training, integration, customer judgment, or exception ownership – tells people what skills the operating model will need and gives managers something concrete to staff.
Control agent spend at the workflow boundary
Agent costs behave differently from ordinary software seats. A seat usually has a visible price. An agent can consume models, context, tools, search, code execution, retries, storage, and human attention in one run. Autonomy can increase both useful work and waste, so access alone is not a sufficient budget control.
Start with the full cost stack:
- Input, output, and reasoning consumption across every model used in the run
- Retrieval, database, browser, search, and external tool charges
- Compute, storage, observability, evaluation, and security overhead
- Failed attempts, repeated context, loops, and recovery runs
- Human setup, review, correction, approval, and escalation
- Integration maintenance and the cost of changing models or vendors
Then put controls where work is requested and executed, not only on the monthly invoice:
- Tag every run to a workflow, business owner, environment, and cost center. Untagged consumption cannot be governed intelligently.
- Give the agent a task envelope: permitted tools, data boundaries, spend ceiling, retry budget, stop condition, and escalation path.
- Route by difficulty and risk. Use the lowest-cost option that can reliably clear the acceptance rule, then escalate ambiguous or consequential work.
- Send only the context needed for the decision. Repeatedly loading irrelevant history increases cost and can make the task harder to evaluate.
- Preserve state and summaries at handoff so a human or another model does not repeat the entire investigation.
- Separate read, recommend, and act permissions. An agent that can inspect a system does not automatically need authority to change it.
- Keep a usable off switch. Employees and customers need a predictable path to human handling when confidence, consent, or economics no longer support automation.
Model routing is a practical lever when the architecture supports it. Biko uses a model-agnostic harness with a smaller, cheaper model handling initial triage before work is routed onward. That design can reduce unnecessary premium-model usage and makes model substitution easier. It still needs evaluation by workflow; cheap triage is only economical if misrouting, repeated runs, and human recovery do not erase the savings.
For actions that can alter production state, spend money, message customers, expose protected data, or delete information, add scoped permissions, reversible operations where possible, and human approval at the relevant boundary. The downside is not merely a larger model bill. A low-cost autonomous mistake can create operational, legal, security, or customer costs far beyond the inference charge.
Use four portfolio decisions instead of a binary keep-or-cancel debate:
- Scale when acceptance, quality, cost per accepted outcome, and the destination of released capacity all remain credible under representative demand.
- Repair when the workflow has real value but retries, context, review, routing, or exceptions are distorting the economics.
- Constrain when the agent is useful only for certain users, data classes, task types, or permission levels.
- Retire when accepted outcomes do not justify the fully loaded cost or when the supposed benefit has no willing business owner.
Make accountability part of product and workforce governance
AI productivity fails as a shared responsibility when shared means nobody owns the final claim. Assign decision rights explicitly.
| Owner | Accountability | Evidence brought to review |
|---|---|---|
| Product leader | Workflow choice, acceptance rule, user behavior, and value hypothesis | Accepted outcomes, adoption in the target workflow, quality, and business result |
| Functional leader | Baseline validity, process redesign, and destination of released capacity | Queue, staffing, quality, output, and redeployment changes |
| AI platform or engineering owner | Architecture, routing, reliability, observability, and technical efficiency | Run cost, failure modes, retries, latency, model mix, and incidents |
| Finance or FinOps | Cost allocation, internal rates, financial classification, and budget impact | Fully loaded cost, committed savings, realized savings, and forecast variance |
| Security, legal, and risk owners | Data access, permissions, approval boundaries, and regulatory exposure | Control coverage, exceptions, incidents, and unresolved risks |
| People leader | Role redesign, training, performance expectations, and transition consequences | Changed responsibilities, skill gaps, mobility, workload, and employee impact |
Use the same evidence at each decision gate:
- At approval, record the workflow, baseline, acceptance rule, cost boundary, owner, capacity destination, and condition that would stop the investment.
- During the pilot, inspect accepted and rejected work, variable cost, human attention, exceptions, and risk events. Usage alone is not evidence of productivity.
- Before scaling, confirm that unit economics survive representative volume and that the beneficiary is willing to own the budget and operating change.
- After scaling, compare the promised capacity destination with what managers actually changed.
- Before renewal or expansion, reassess price, total operating cost, and value separately. A favorable contract does not rescue a weak workflow.
This governance should measure the work, not turn into employee surveillance. Token volume, prompt count, keyboard activity, and time inside an AI tool are poor proxies for an individual’s value. Use workflow-level evidence by default. Where individual telemetry is genuinely required for safety, compliance, support, or cost investigation, define its purpose, access, retention, and decision use explicitly.
Your next move is to choose the AI workflow with the most consequential spend or the strongest productivity claim and complete one ledger for it. If the team cannot define an accepted outcome, pause the ROI narrative. If it can define the outcome but cannot name where released capacity will go, treat the work as an operational experiment rather than booked savings. When both are clear, set the spend envelope and scale only while the cost per accepted outcome and the realized business result continue to support the decision.
References
- AI Gamechangers – AI has empowered a lot of our support agents to move into more advanced roles
- Nate Jones’s Substack – Elon Musk says Grok Bot costs too much to serve. xAI says it flagged 43 idle software seats that saved $14,220 once downgraded. So what is your agent’s work worth?






